 |
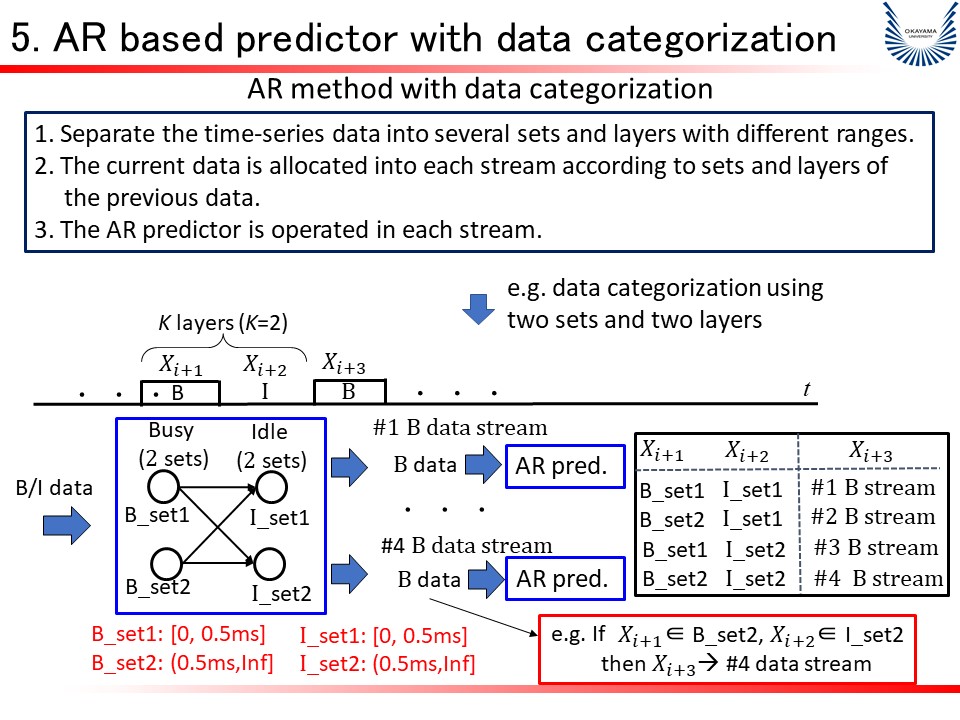
The data categorization can be processed as these steps.
First, we separate the time-series data into several sets and layers with different ranges.
Then, the current data is allocated into each stream according to sets and layers of the previous data.
Finally, the prediction such as AR predictor is operated in each stream.
Here we explain the data categorization using two sets and two layers.
Each busy and idle duration is separated with two sets with ranges as shown in this figure. The current busy or idle will be put into different stream according to the previous X_{i+1} and X_{i+2}. For example, if X_(i+1) belongs to Set_2 and X_(i+2) also belongs to Set_2, then, X_(i+3) is put into the 4-th stream. After that, the future busy or idle duration is predicted in 4-th stream.
|
 IEEE/ICACT20210239 Slide.12
[Big Slide]