 IEEE/ICACT20220141 Slide.12
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20220141 Slide.12
[Big Slide]
| Oral Presentation |
|
|
|
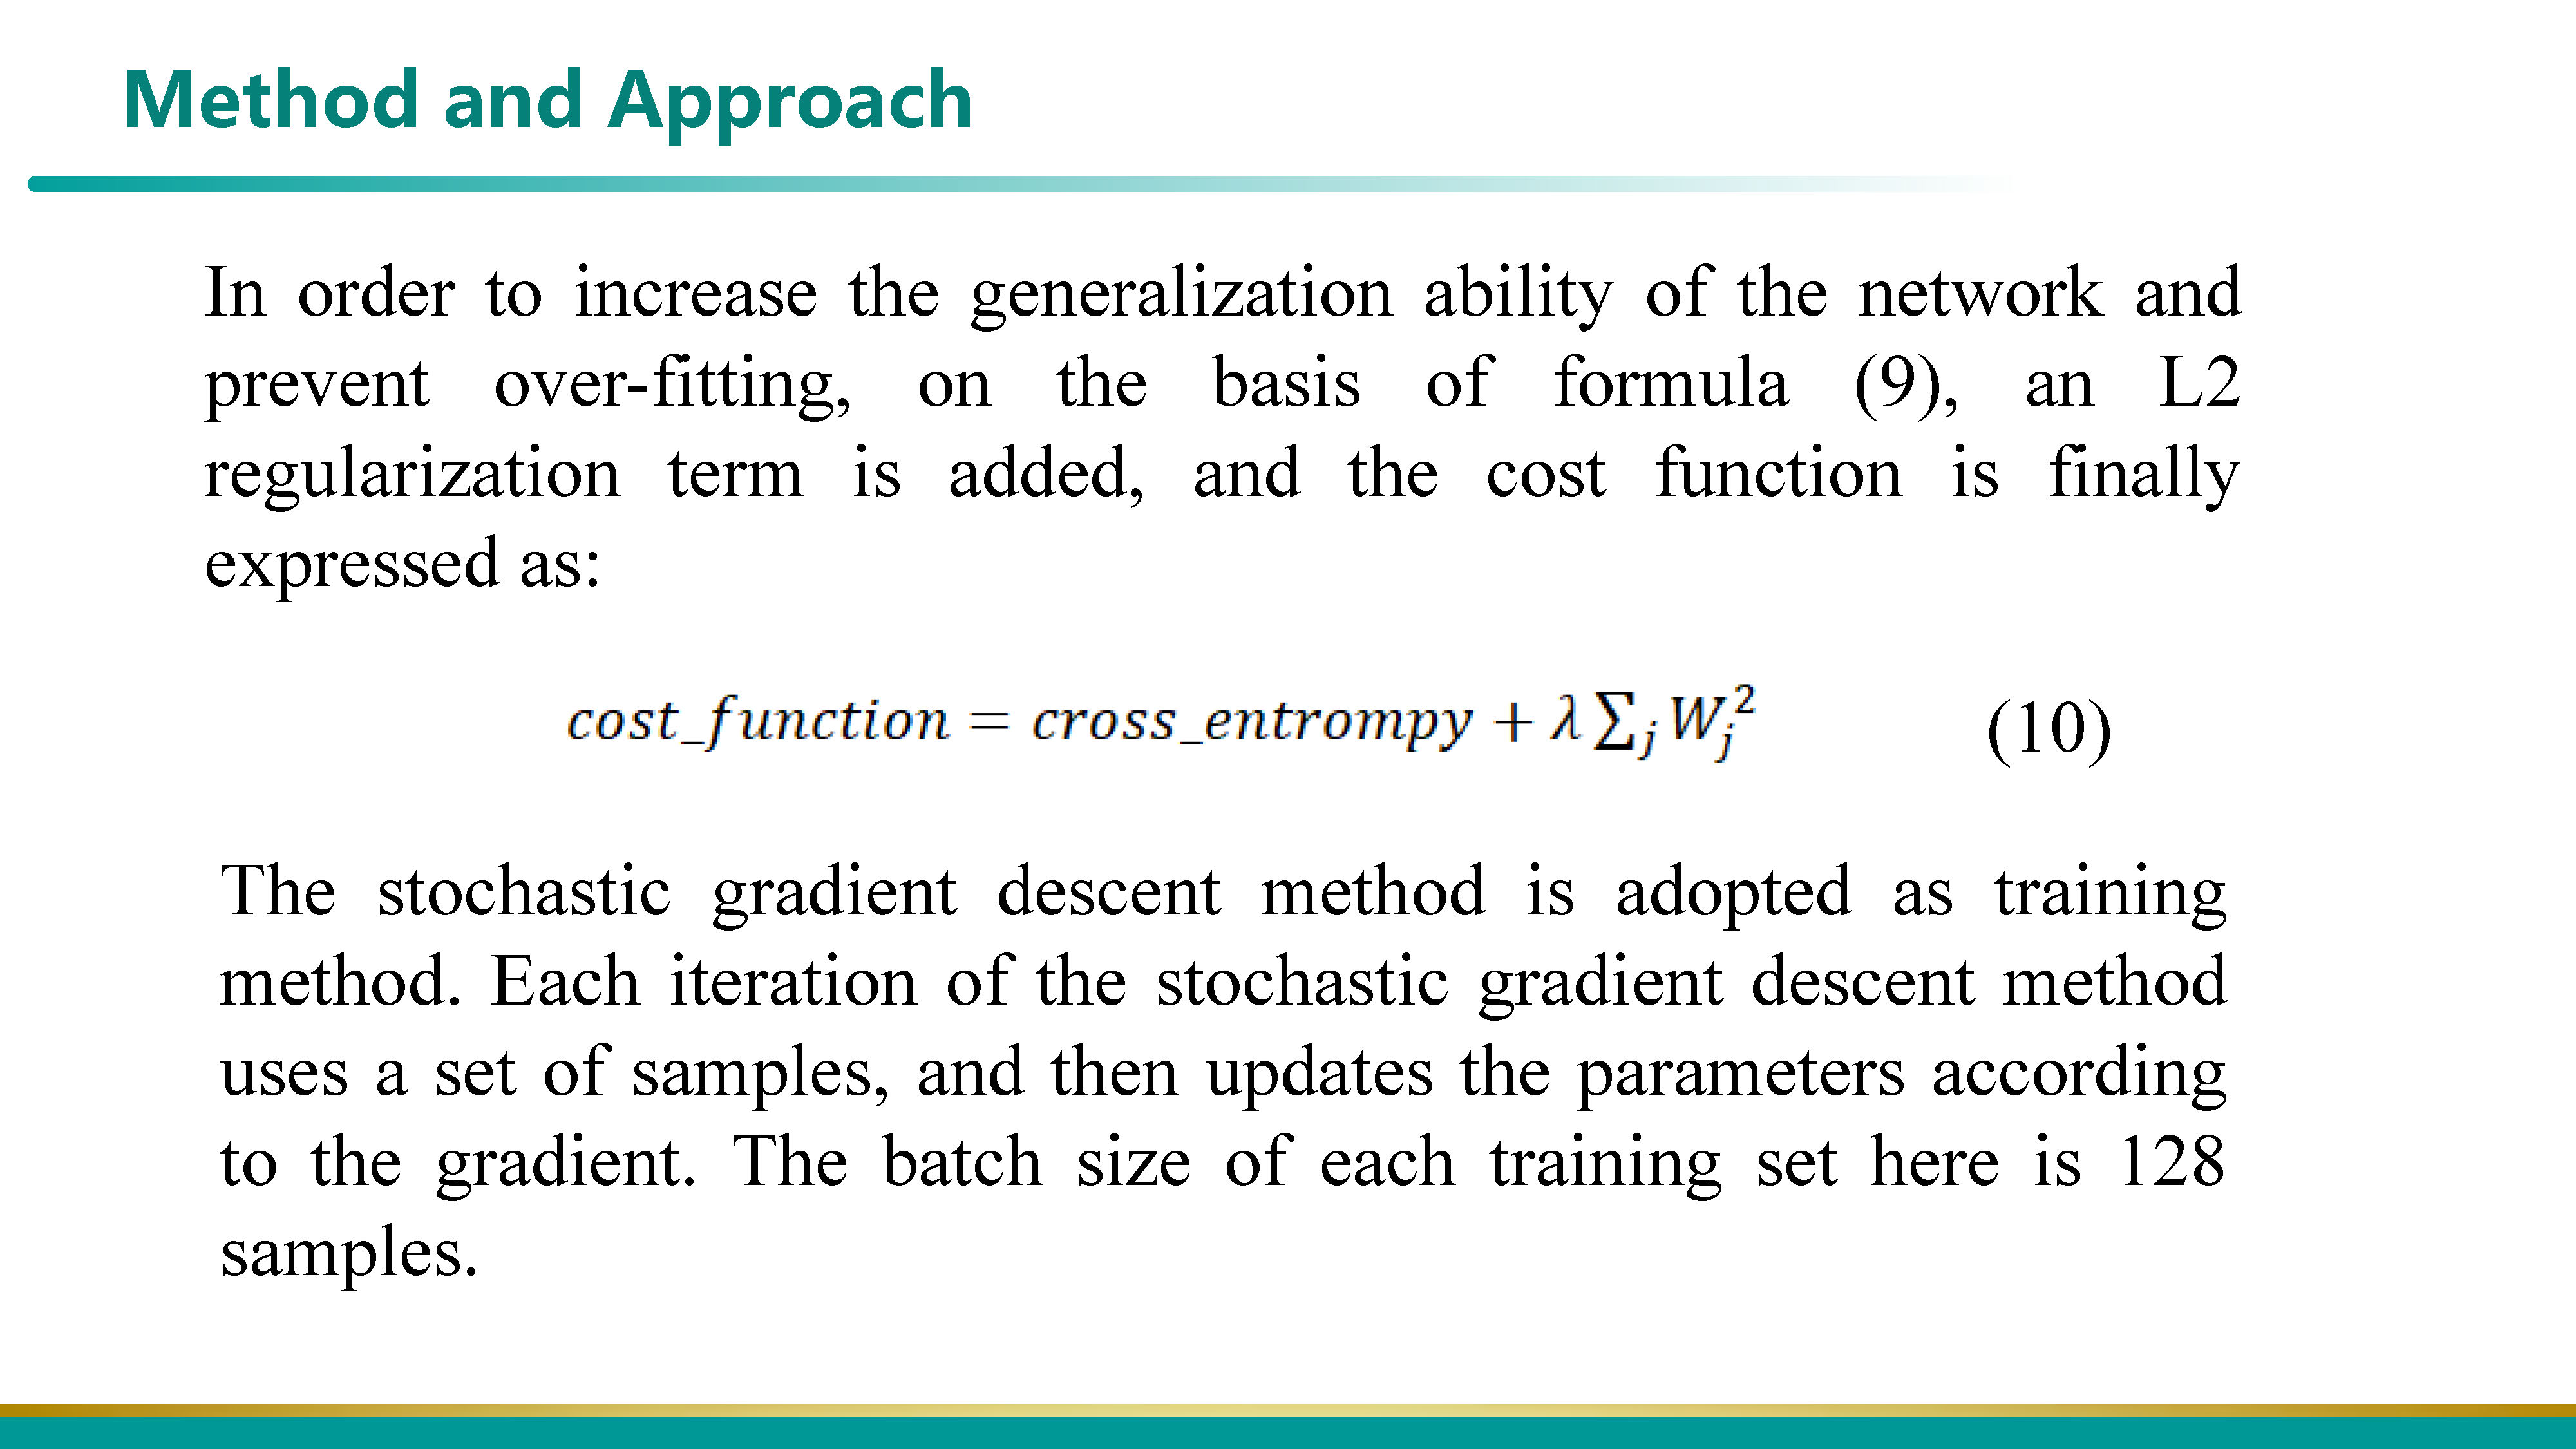
In order to increase the generalization ability of the network and prevent over-fitting, on the basis of formula (9), an L2 regularization term is added The stochastic gradient descent method is adopted as training method. Each iteration of the stochastic gradient descent method uses a set of samples, and then updates the parameters according to the gradient. The batch size of each training set here is 128 samples. | |
| [Go to Next Slide] |