 |
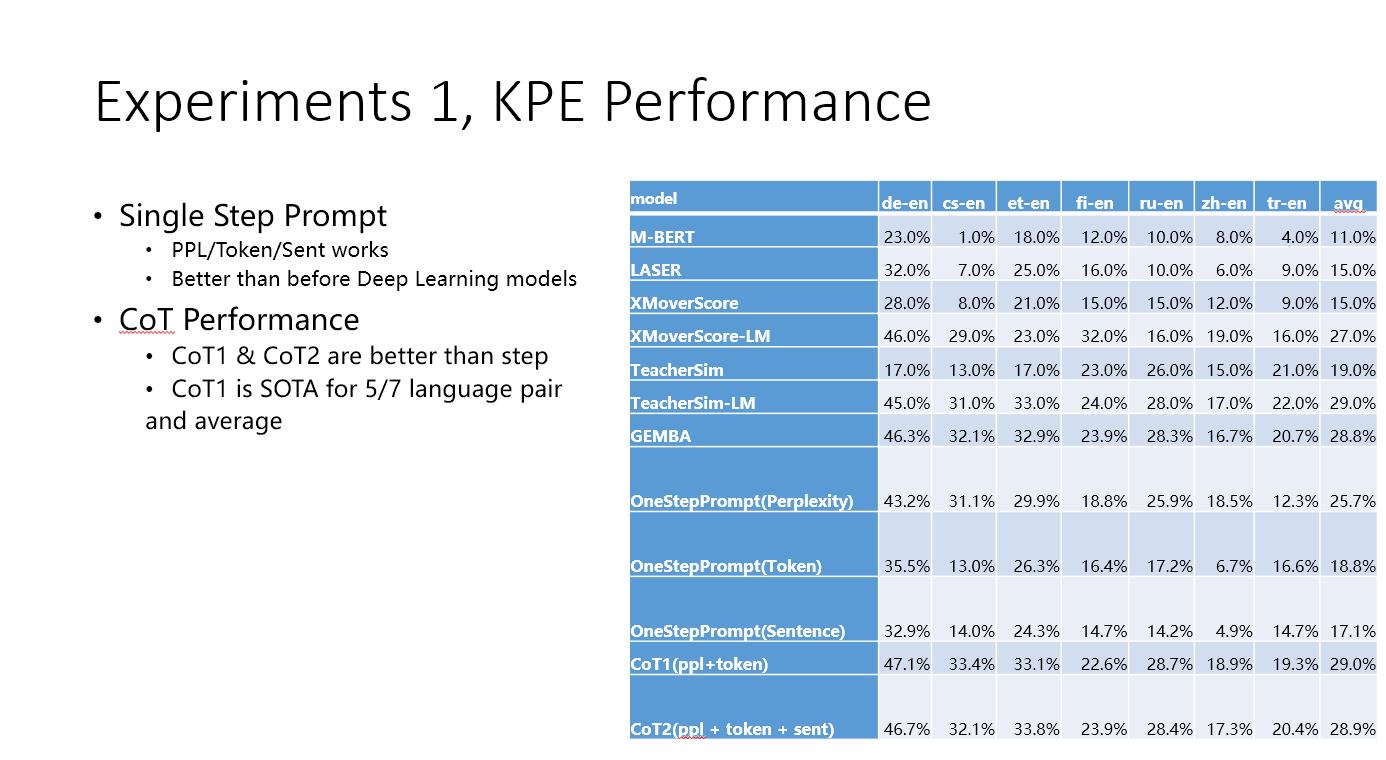
Our single-step knowledge-prompted evaluation (KPE) metrics using perplexity, token, and sentence features outperform past pre-neural quality estimation methods, demonstrating the superior evaluation capabilities of large language models.
Critically, the chain-of-thought (CoT) metrics combining step-wise reasoning trace model judgments more effectively. Both CoT1 and CoT2 significantly outperform the single-step KPE metrics across all test languages.
Specifically, CoT1 achieves state-of-the-art segment-level correlation versus human ratings on 5 out of 7 benchmark language pairs. On average, CoT1 also sets a new highest Kendall's Tau correlation level, surpassing past learning-based and feature-engineered quality estimation systems.
In summary, chaining step-wise KPE reasoning to assess translation adequacy, fluency and semantics sets a new performance level for fine-grained machine translation evaluation using prompted language models, while increasing model interpretability. Our work highlights the promise of knowledge prompting strategies to unlock greater understanding of model decisions. |
 IEEE/ICACT20240321 Slide.12
[Big Slide]