 |
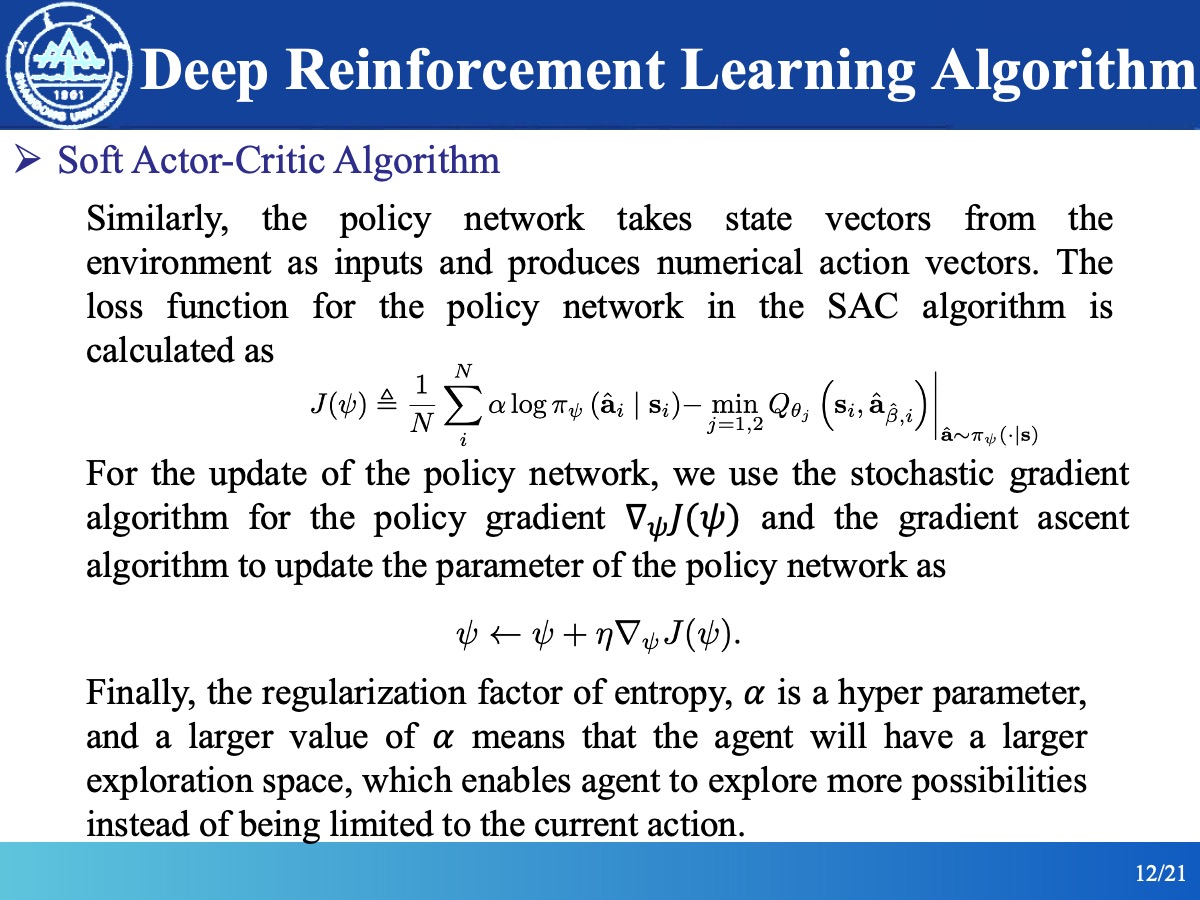
Similarly, the policy network takes state vectors from the environment as inputs and produces numerical action vectors. The loss function for the policy network in the SAC algorithm is calculated as the formula. For the update of the policy network, we use the stochastic gradient algorithm for the policy gradient ¡Ô_𝜓 𝐽(𝜓) and the gradient ascent algorithm to update the parameter of the policy network as the formula. Finally, the regularization factor of entropy, 𝛼 is a hyper parameter, and a larger value of 𝛼 means that the agent will have a larger exploration space, which enables agent to explore more possibilities instead of being limited to the current action.
|
 IEEE/ICACT20240375 Slide.12
[Big Slide]
[YouTube]