 |
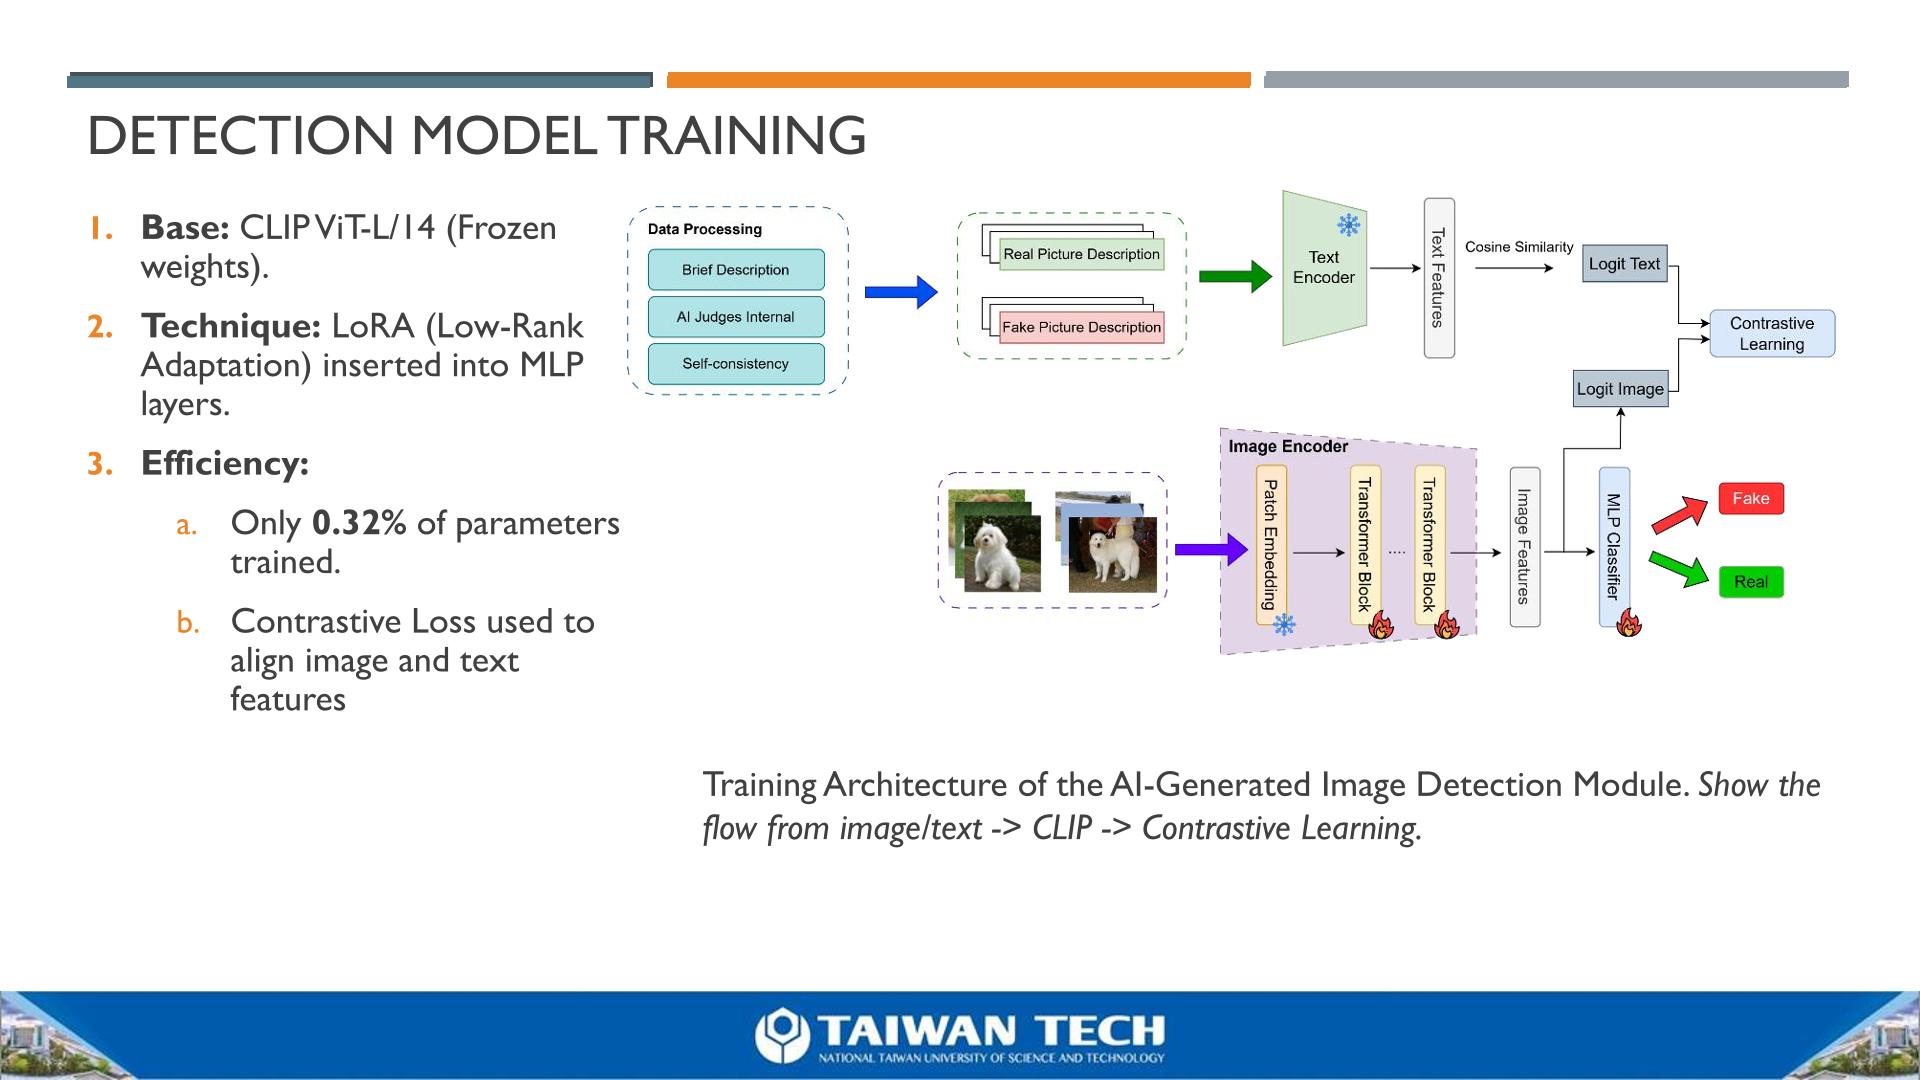
For the detection module, the CLIP ViT-L/14 model functions as the feature extractor, with its pre-trained weights frozen to retain general semantic knowledge . Low-Rank Adaptation (LoRA) modules are inserted into the transformer blocks, specifically training only the rank-8 matrices . This enables fine-tuning using just 0.32% of the total parameters approximately 1.35 million out of 400 million . A contrastive loss function aligns the image and text features, followed by an MLP classifier to determine the authenticity of the image. |
 IEEE/ICACT20260070 Slide.12
[Big Slide]