 |
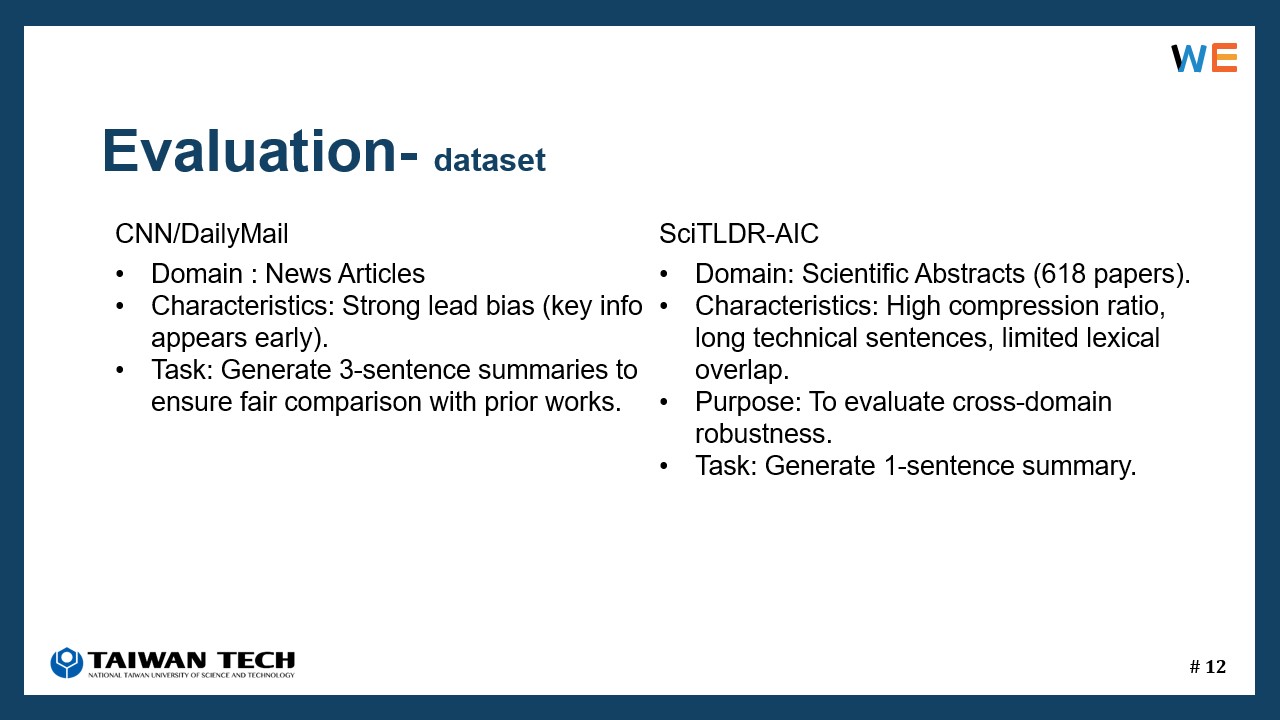
For evaluation, we selected two distinct datasets to test different aspects of our model.
First, we used CNN/DailyMail. This is the standard benchmark for news summarization. Since news articles often have lead bias, we followed the standard practice of generating 3-sentence summaries to ensure a fair comparison with prior works.
However, to verify our models robustness, we didnt want to stop at news. We also tested it on SciTLDR-AIC. This dataset consists of scientific abstracts and represents a much harder challenge due to its technical language and high compression ratio. For this task, we aimed to generate a concise 1-sentence summary. |
 IEEE/ICACT20260145 Slide.12
[Big Slide]