 |
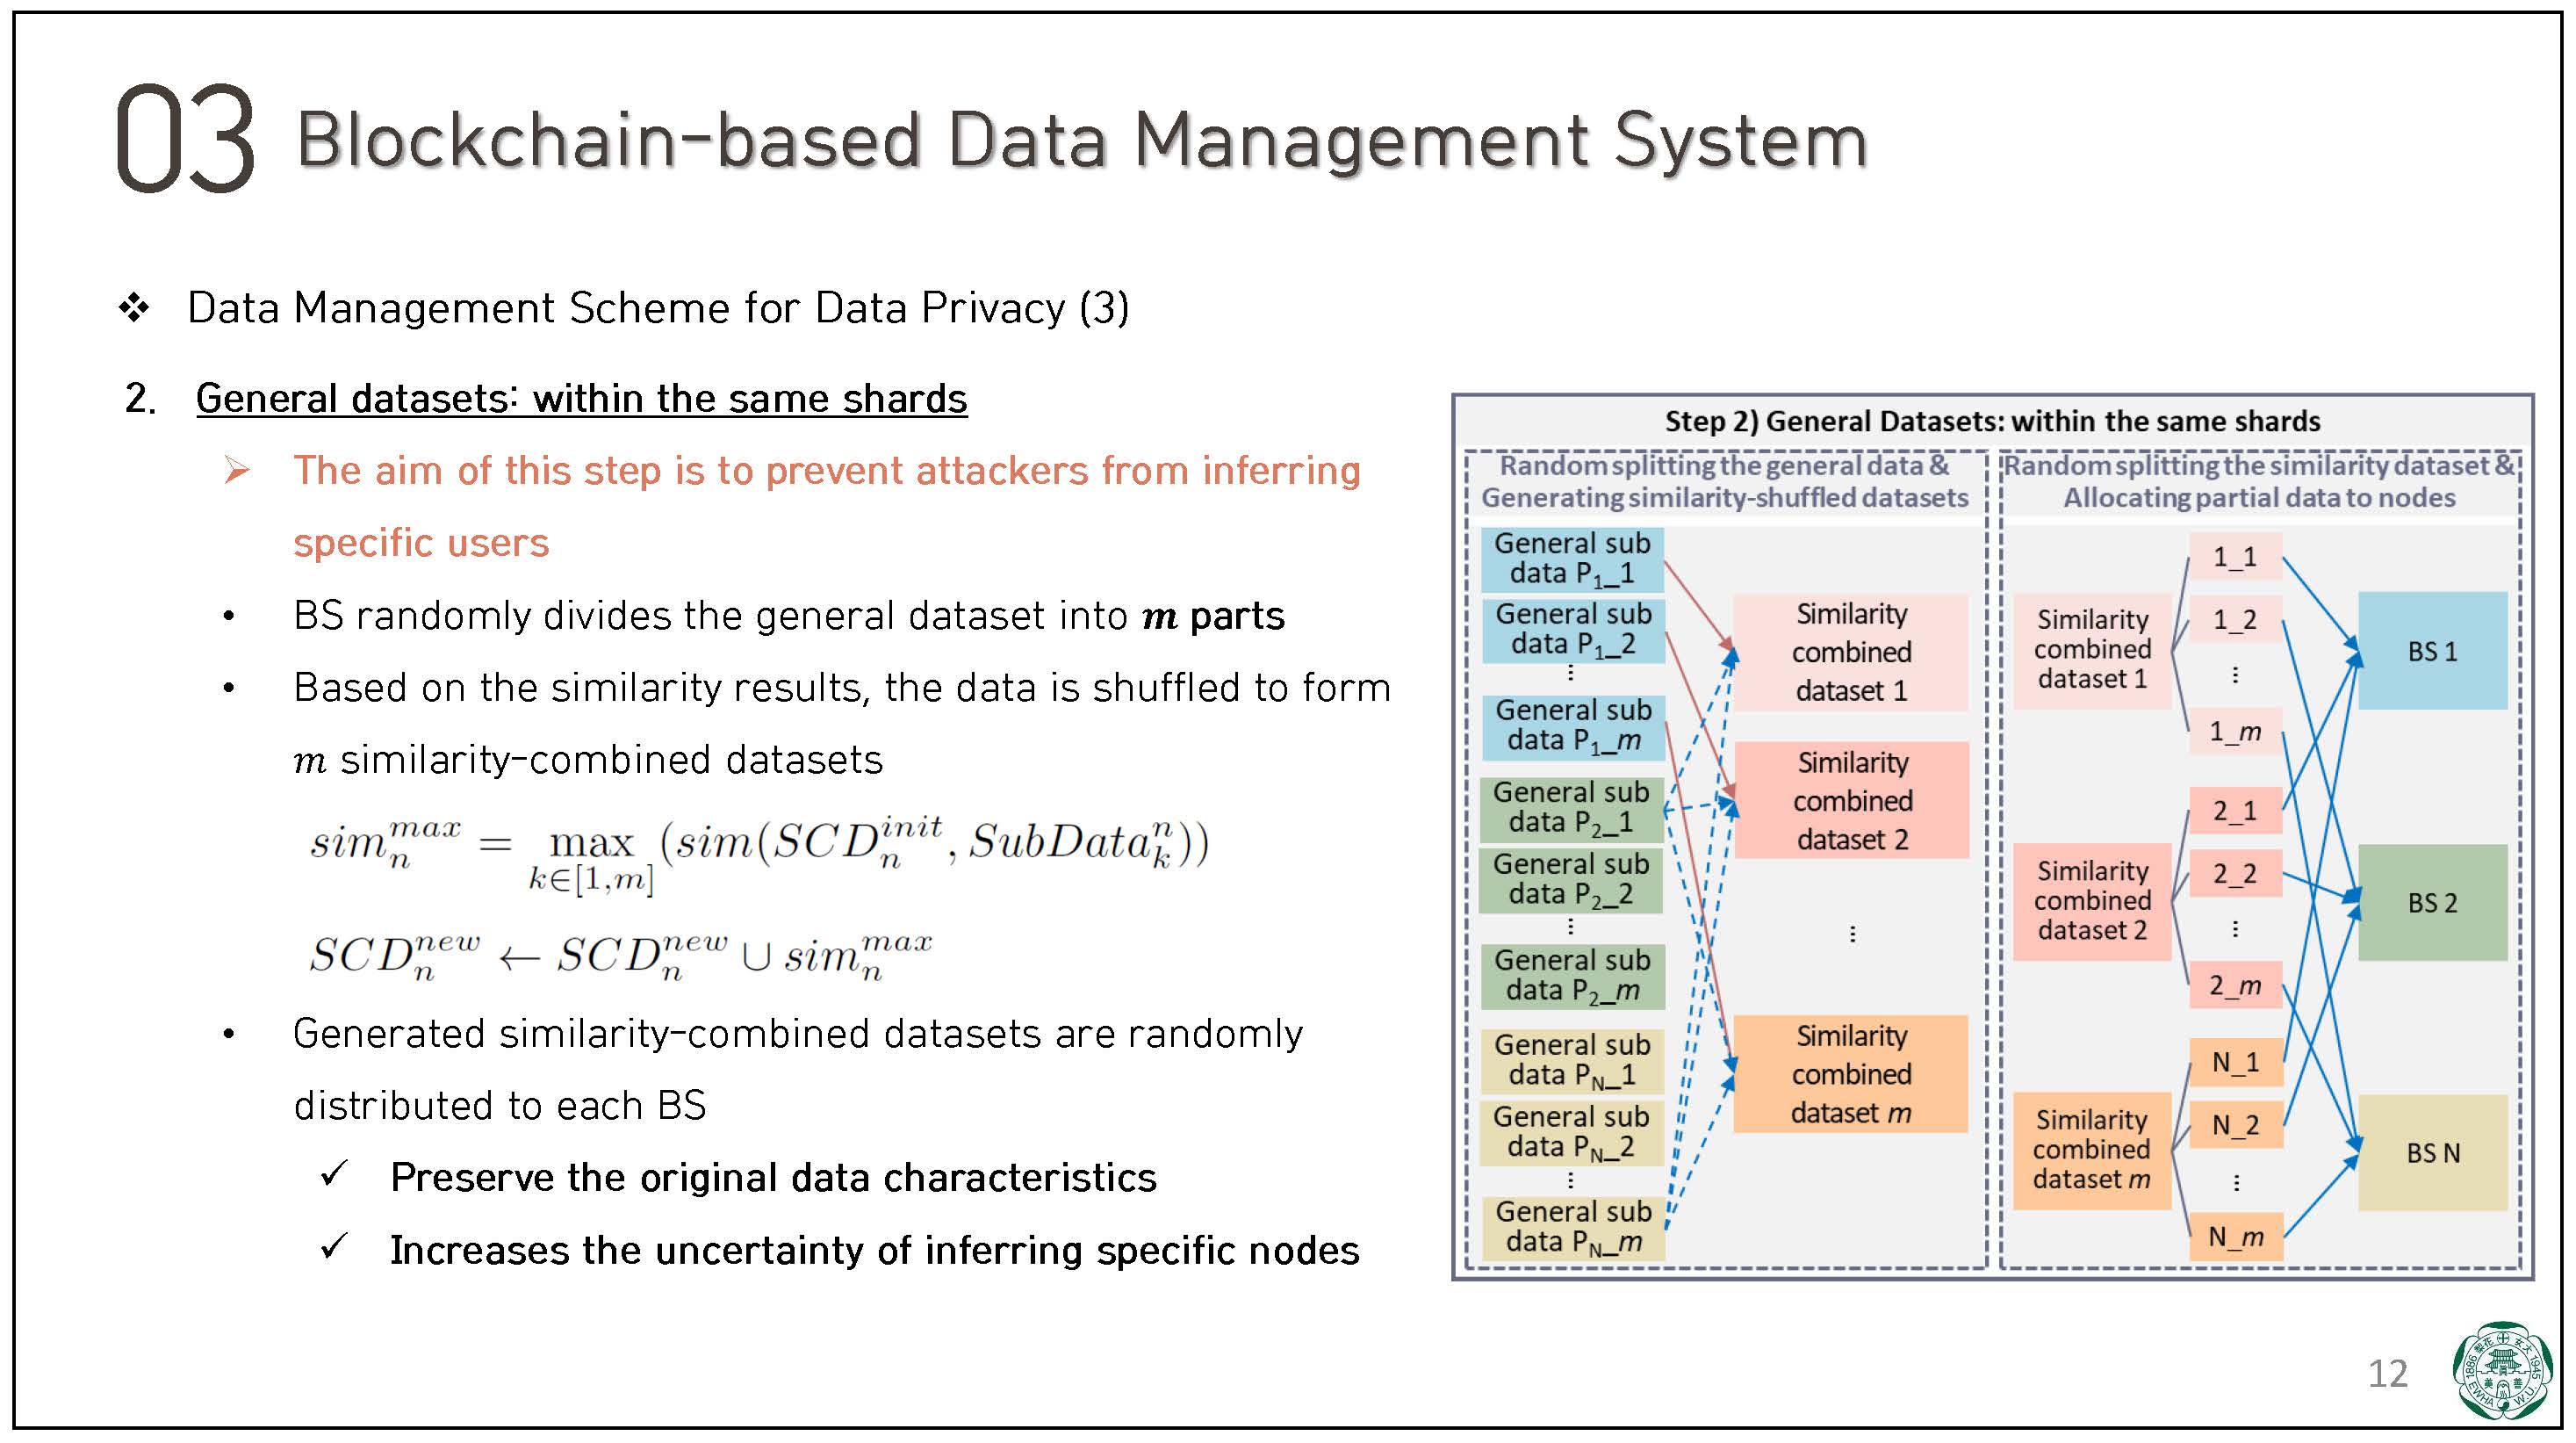
This is general datasets processing step.
The aim of this step is to prevent attackers from inferring specific users.
Base stations randomly divide the general dataset into m parts.
Based on the similarity results, the data is shuffled to form m similarity-combined datasets.
Here, similarity is calculated between the initial similarity-combined dataset and each sub-dataset.
In our implementation, this initial SCD is formed by randomly selecting samples.
Then, the generated similarity-combined datasets are randomly distributed to each base station.
This process helps preserve the original data characteristics and increases the uncertainty of inferring specific nodes.
|
 IEEE/ICACT20260202 Slide.12
[Big Slide]