 IEEE/ICACT20230035 Slide.13
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230035 Slide.13
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
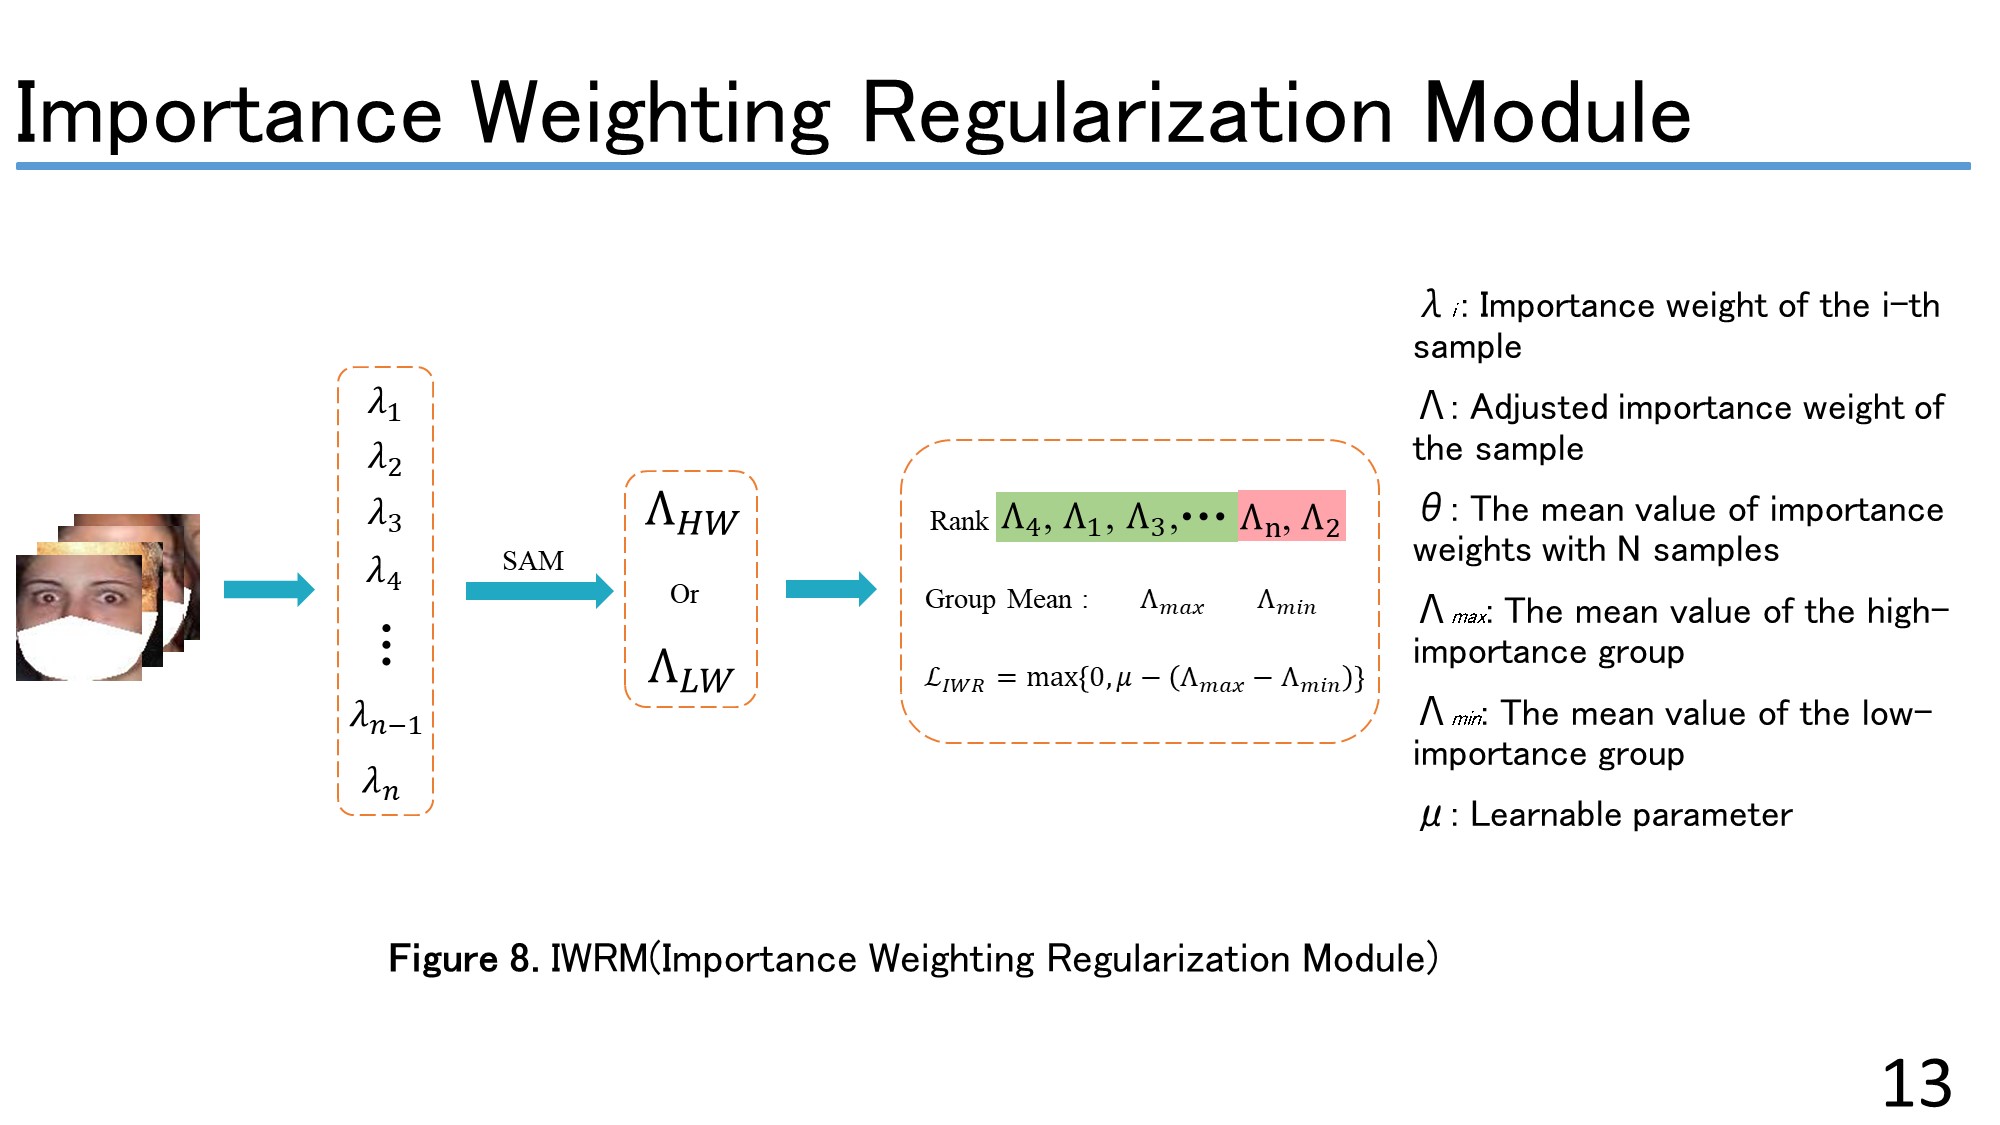
In the importance weight regularization module, each batch of samples is automatically divided into two groups, the high-importance group and the low-importance group. We count the data volume of incoming high-weight and low-weight samples separately. We can compute the model's training loss ℒ_𝐼𝑊𝑅 by computing the resulting mean and the trainable parameter ¥ì. | |
| [Go to Next Slide] |