 |
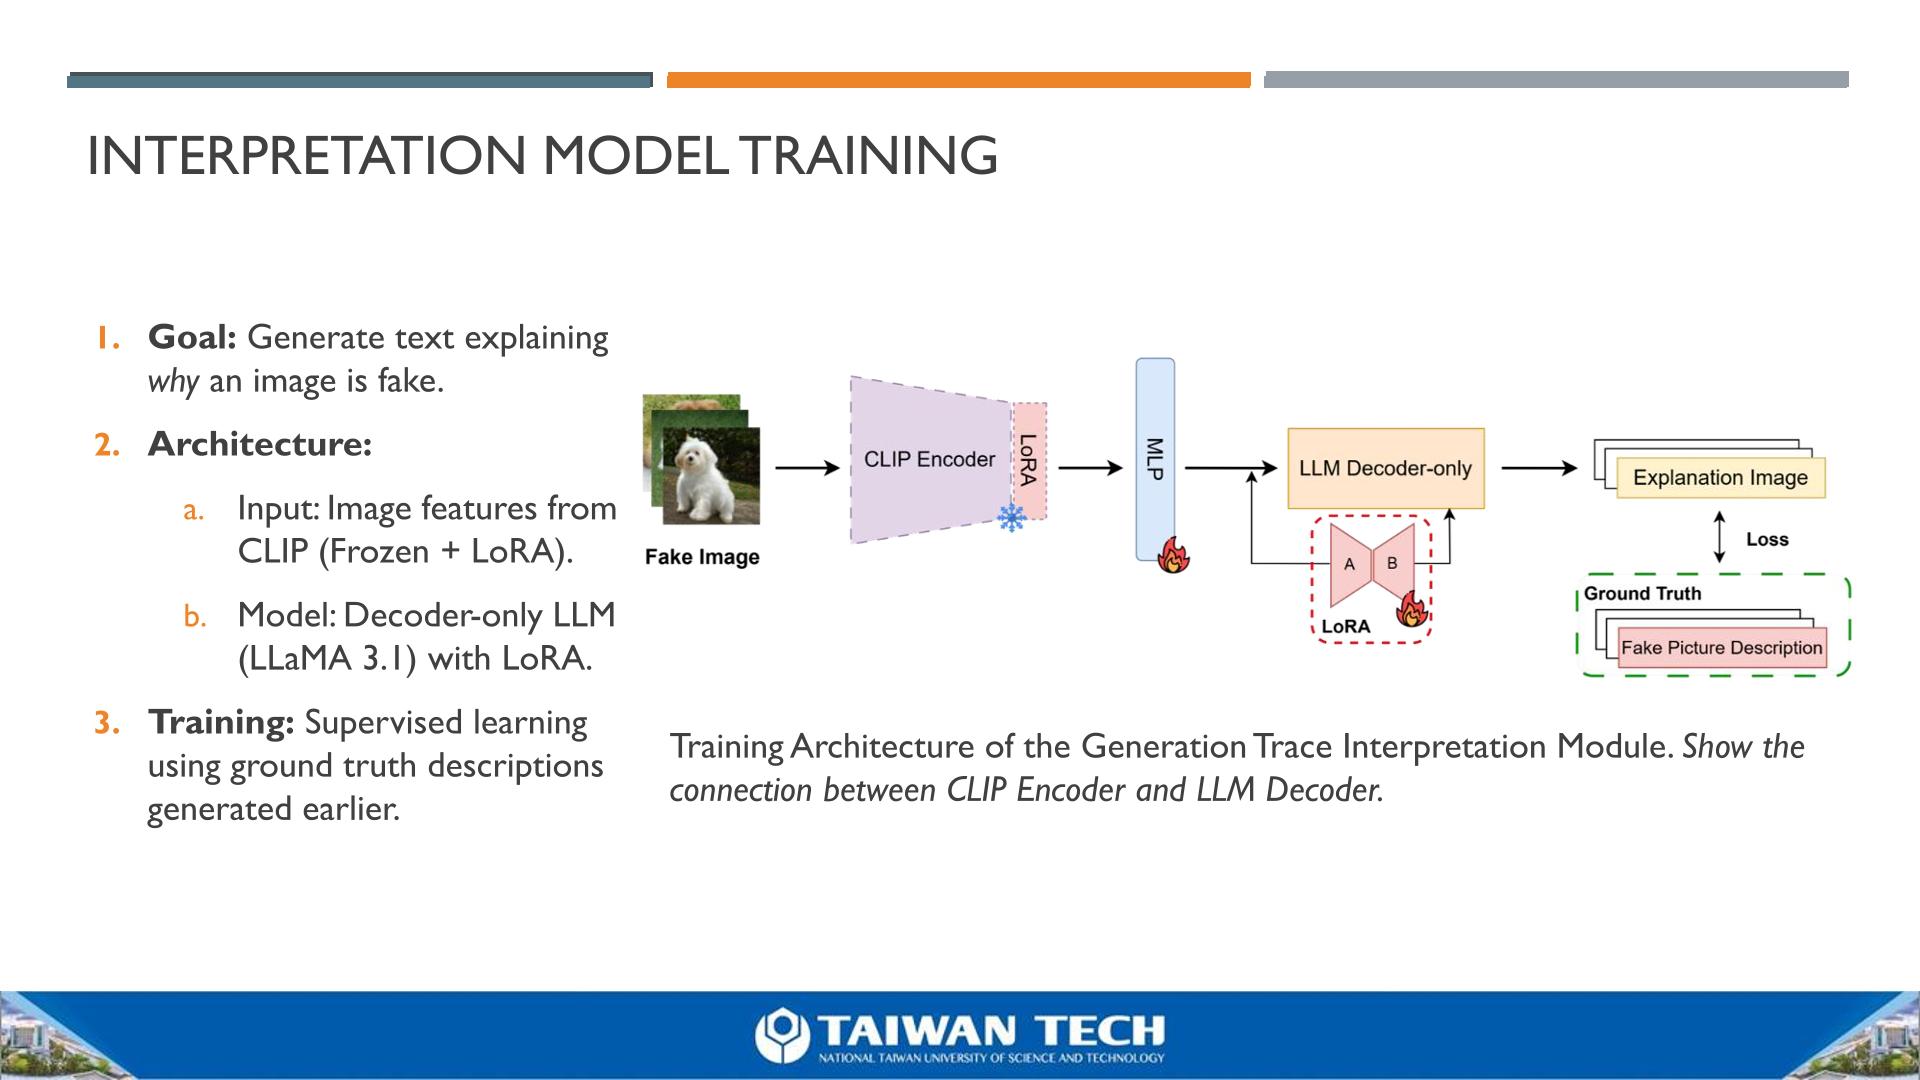
Upon classifying an image as fake, the system passes it to the generation trace interpretation module. This module employs a frozen CLIP encoder with LoRA to extract visual features, which are then projected via an MLP to align with the language models space . These features are fed into a decoder-only LLM (LLaMA 3.1), also fine-tuned with LoRA . Trained via supervised learning on ground truth descriptions, this module generates text explaining specific artifacts, such as unnatural lighting or pixelation, thereby reducing hallucinations and enhancing trust . |
 IEEE/ICACT20260070 Slide.13
[Big Slide]