 |
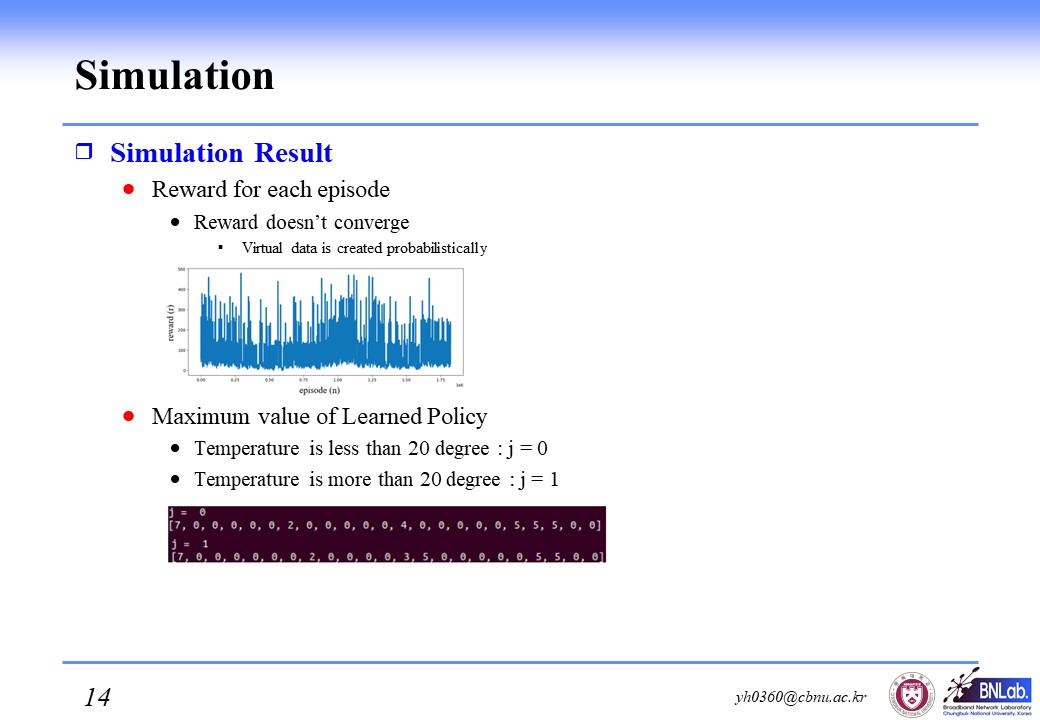
The simulation results are as follows.
The figure above is a graph of the reward by episode.
Rewards do not converge because virtual data was generated probabilistically.
When performing a greedy search in the learned results, it appears as shown in the figure below.
If j is 0, the temperature is less than 20 degrees, and if j is 1, it is higher than 20 degrees.
From the learning results, we were able to confirm that when generating virtual data, the time and menu with high probability distribution were selected.
|
 IEEE/ICACT20220065 Slide.14
[Big Slide]