 |
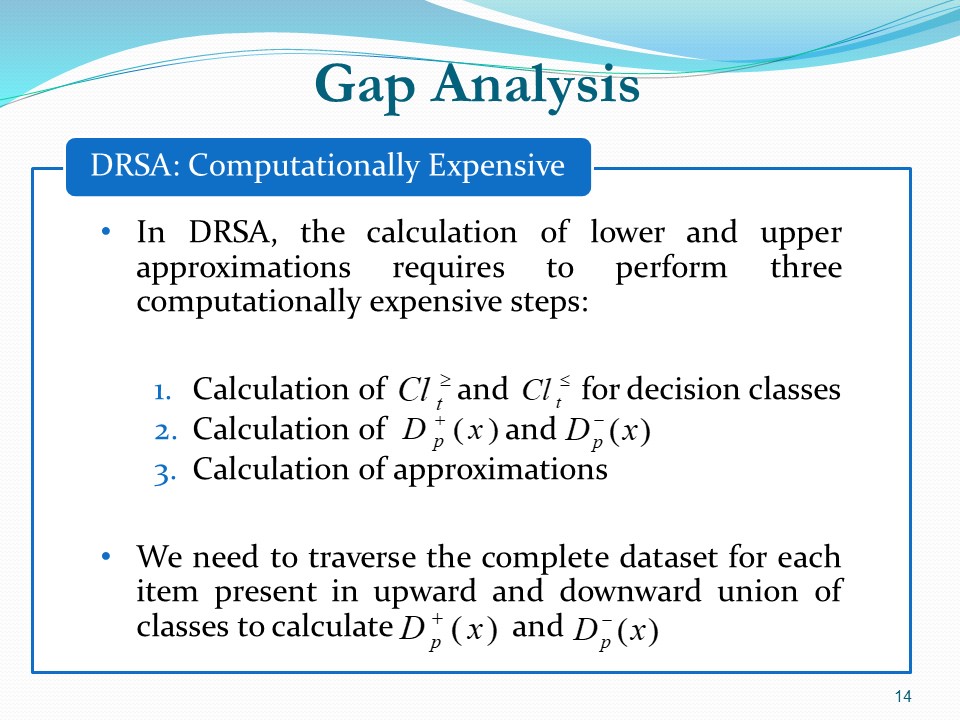
As we discussed earlier, to compute approximations using conventional algorithm of dominance based rough set theory, high computational cost incurred in terms of time and complexity. To compute approximations, it is required to perform three computationally expensive steps. In first step, it requires to compute upward and downward union of classes for each decision class. Then to compute dominance relation, each object repeatedly compared with whole dataset for all its conditional attributes. In the third step, to compute approximation, once again comparison need to be made to check subset and intersect properties. This whole process impose heavy computational cost and affect the performance of algorithm using dominance based rough set theory.
|
 IEEE/ICACT20220156 Slide.14
[Big Slide]