 |
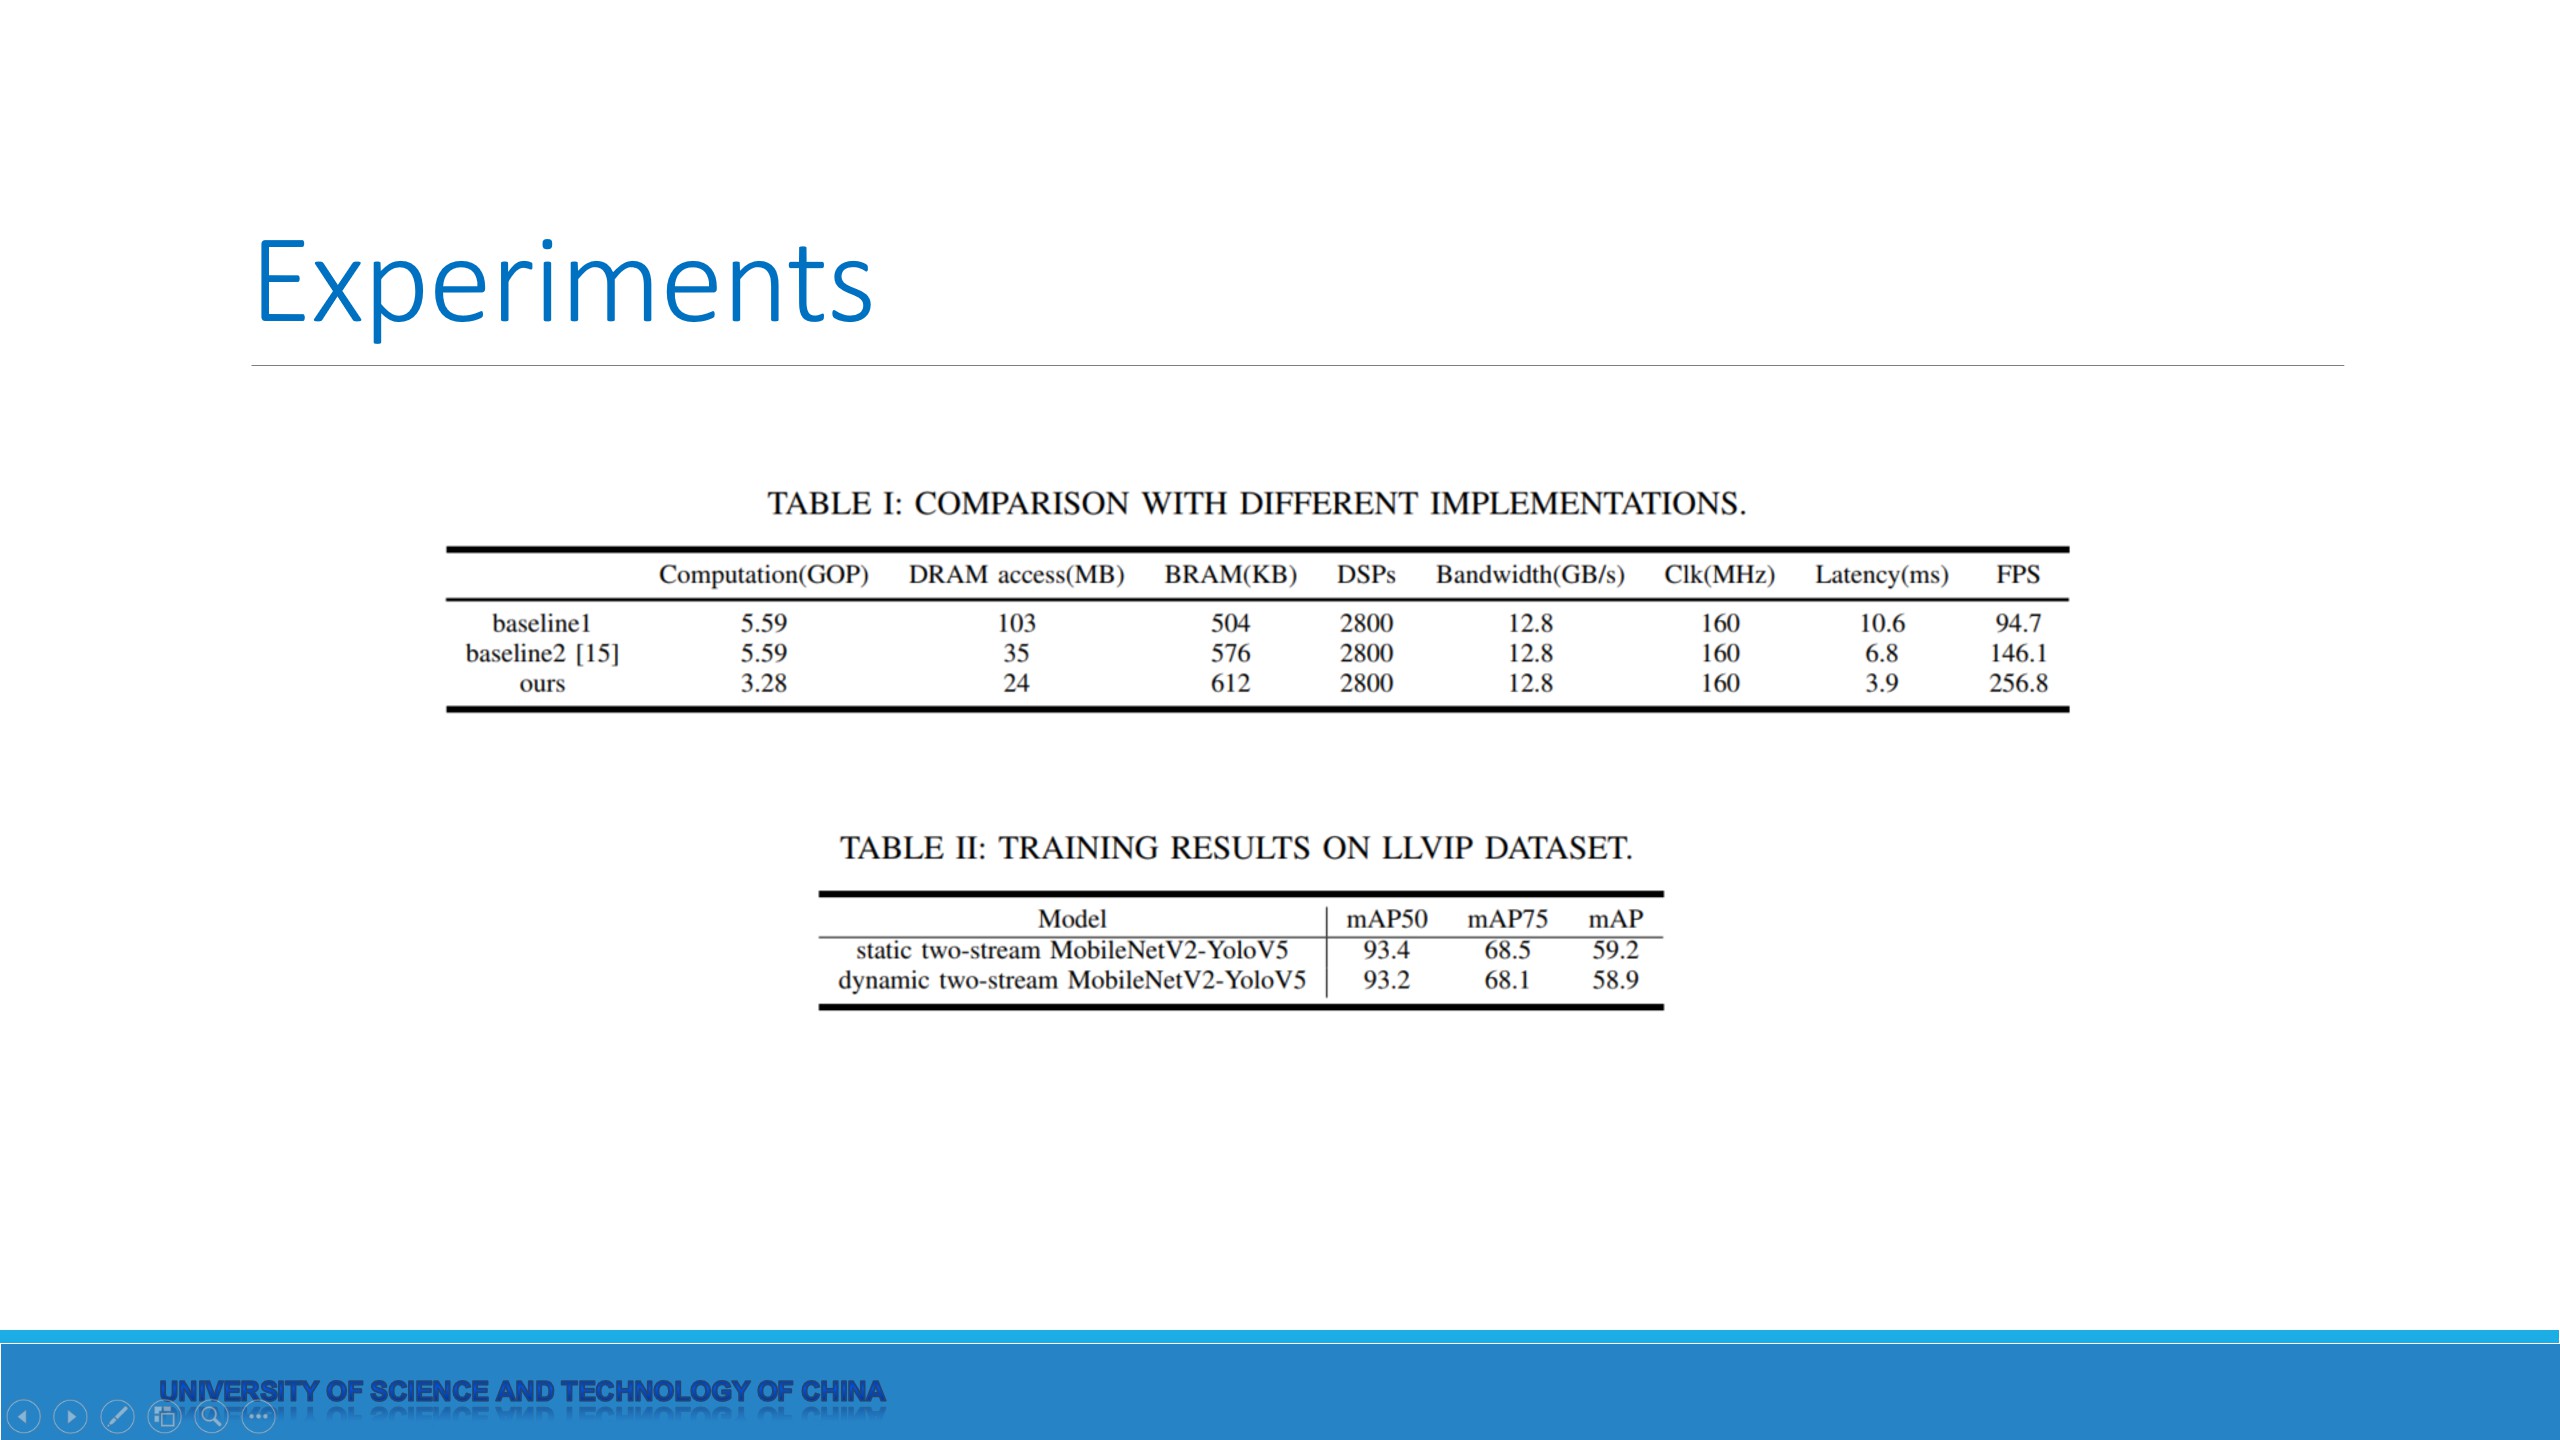
Table I shows the comparison with other baseline implementations. Benefiting from layers skipping and channel pruning, our dynamic neural network accelerator reduces the computational overhead by 41% and DRAM access by 77% compared to the unoptimized baseline1. Compared with baseline2, which only supports cross-layer scheduling for static networks, our implementation reduces the computational overhead by 41% and DRAM access by 31%. Therefore, the inference performance of our implementation is greatly improved by 1.8 -2.7times compared to the baseline.
Table 2 shows the training accuracy of dynamic and static networks on the multispectral detection dataset LLVIP. It can be seen that the accuracy of the dynamic network is close to the accuracy of the static network.
|
 IEEE/ICACT20230038 Slide.14
[Big Slide]
[YouTube]