 IEEE/ICACT20230276 Slide.14
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230276 Slide.14
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
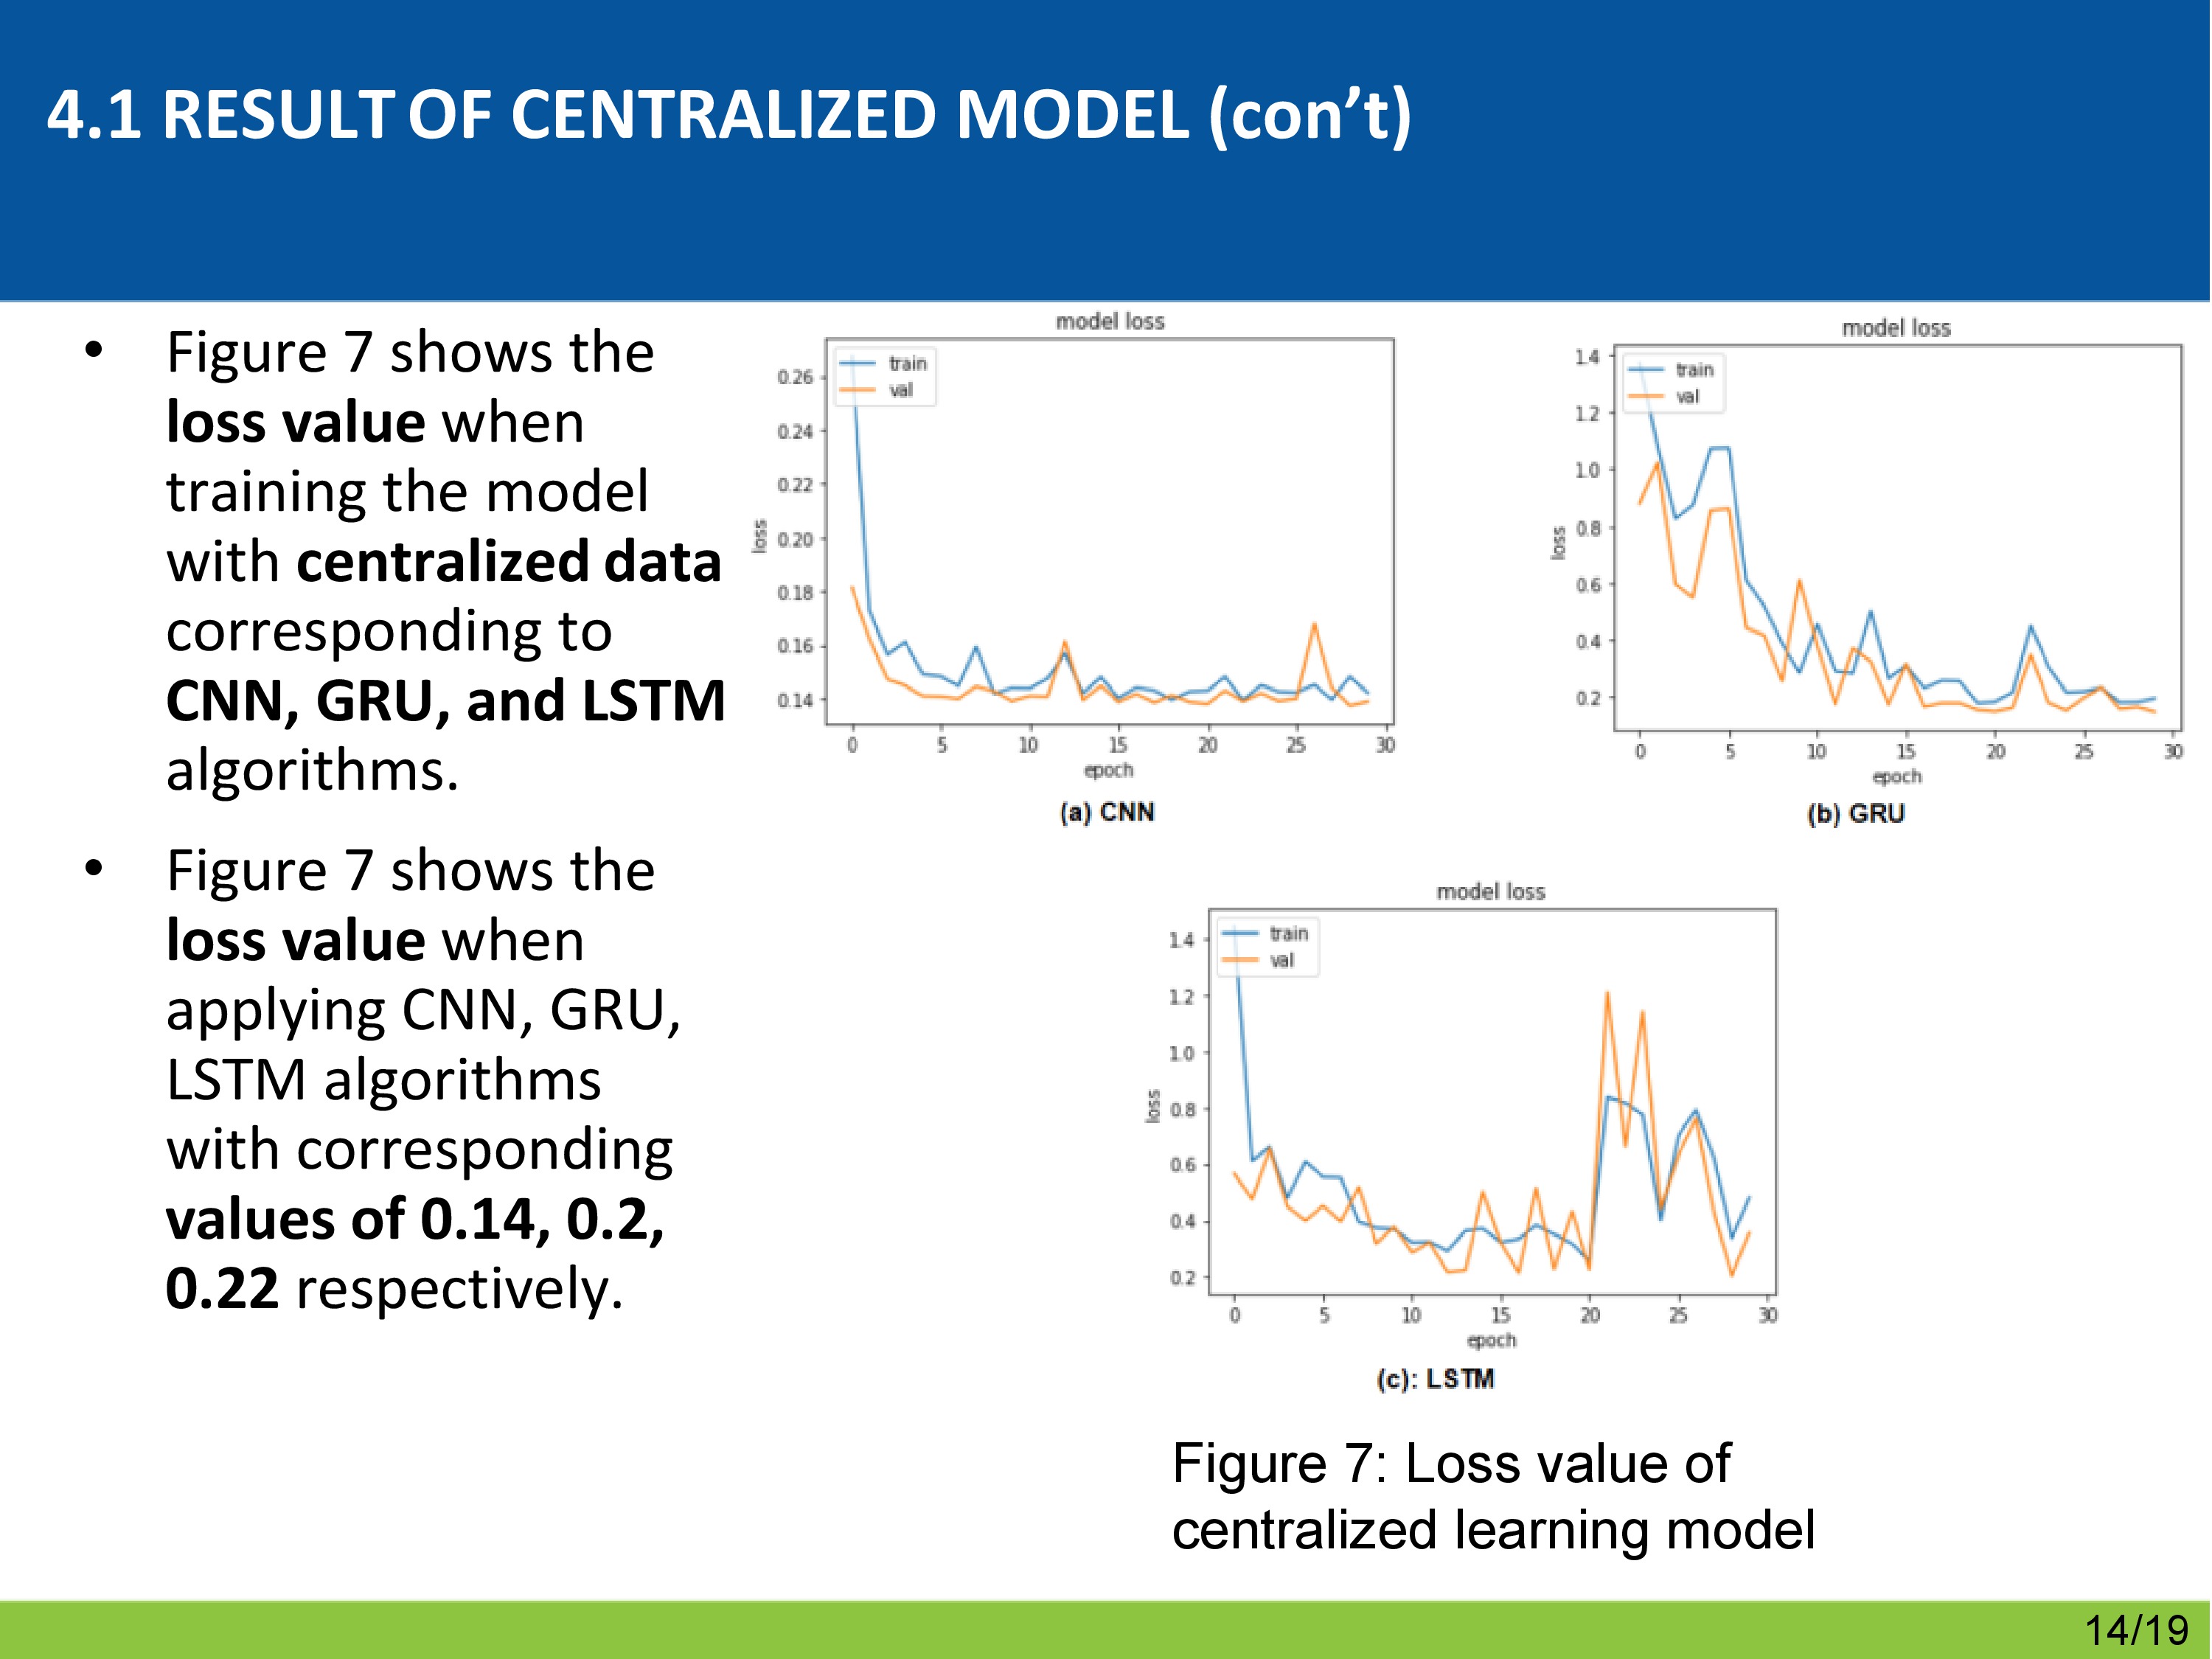
This is the loss value of the training model when experimenting with the centralized model Figure 7 shows the loss value when training the model with centralized data corresponding to CNN, GRU, and LSTM algorithms. Figure 7 shows the loss value when applying CNN, GRU, LSTM algorithms with corresponding values of 0.14, 0.2, 0.22 respectively. | |
| [Go to Next Slide] |