 |
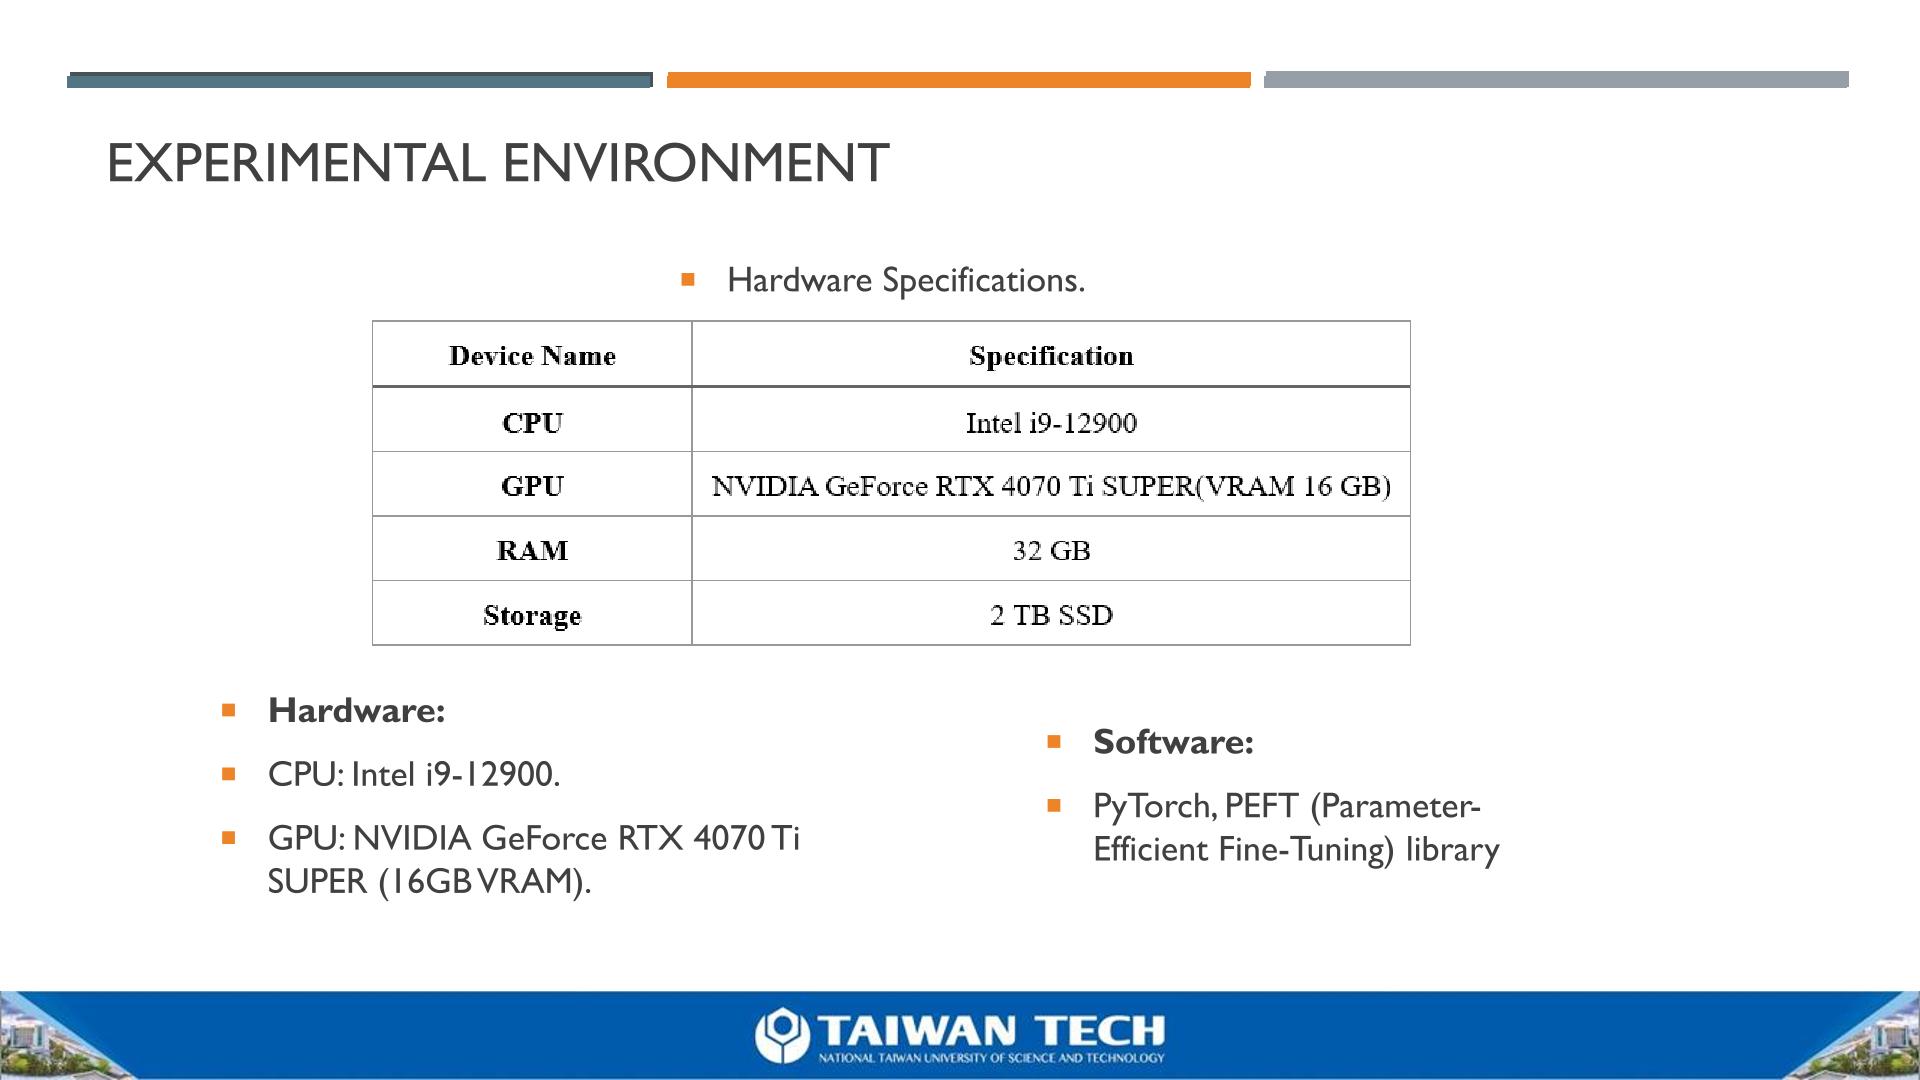
Experiments utilized an Intel i9-12900 processor and an NVIDIA GeForce RTX 4070 Ti SUPER GPU with 16 GB of VRAM. This configuration was selected to manage the memory requirements of the large multimodal models and the quantization processes necessary for the interpretation module . PyTorch and the Hugging Face PEFT library were employed for efficient fine-tuning . The development environment operated across both Windows and Linux to accommodate specific quantization tools required for the LLM training . |
 IEEE/ICACT20260070 Slide.14
[Big Slide]