 IEEE/ICACT20220065 Slide.15
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20220065 Slide.15
[Big Slide]
| Oral Presentation |
|
|
|
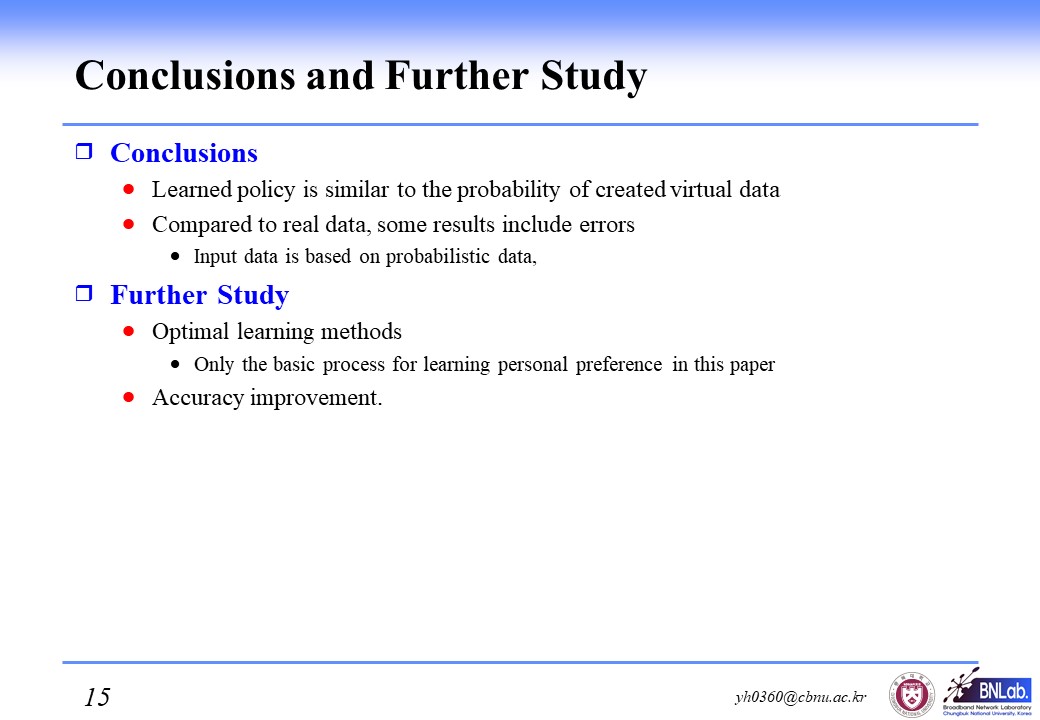
In conclusion, we confirmed that the learned policy is similar to the probabilistic generated virtual data. However, compared to the actual data, some errors were included. This is because the input data is based on probability. We learned personal preferences using only basic processes. As a way to compensate for this, it plans to utilize optimal learning methods such as improvement of accuracy in the future. | |
| [Go to Next Slide] |