 |
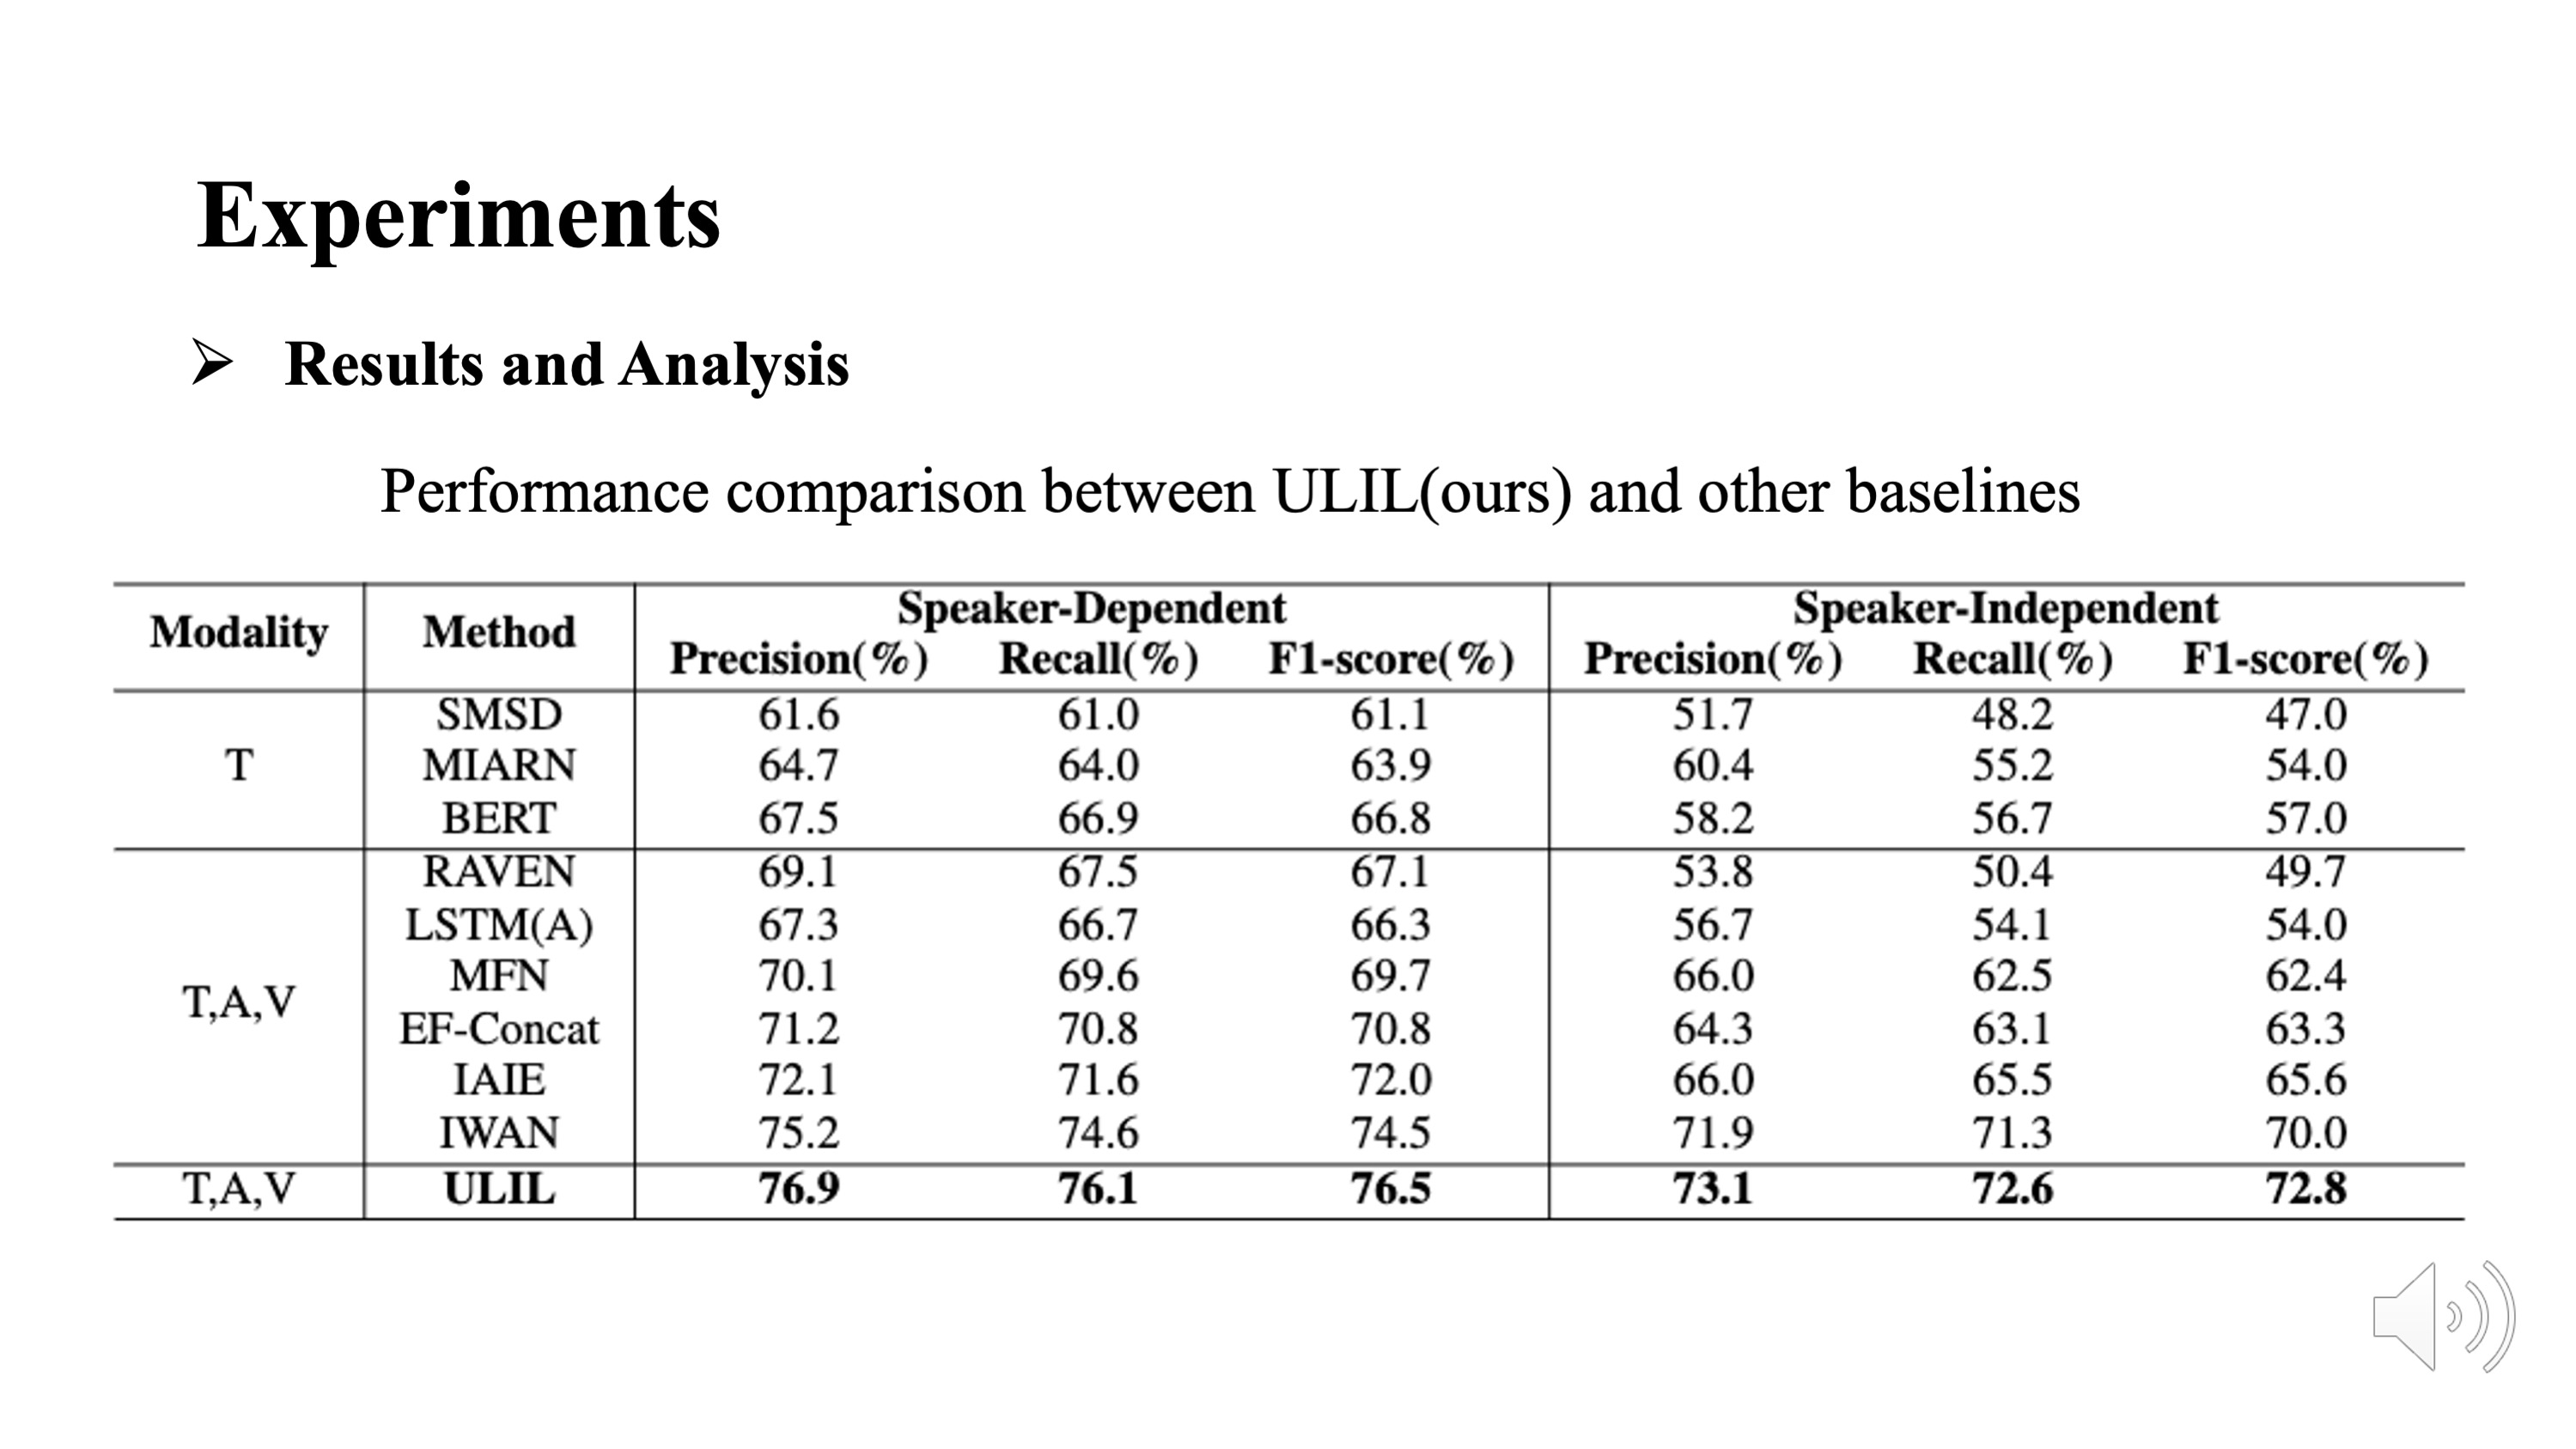
The comparative evaluation experiment results of our proposed model and all baselines are shown in this Table. We can draw the following conclusions:
First, our proposed ULIL outperforms existing baselines on all metrics, confirming the effectiveness of our model in multimodal sarcasm detection.
Second, all of the trimodal sarcasm detection approaches are superior to just text modality detection methods, demonstrating the complementarity of text, image, and audio modalities, thereby enhancing the performance of sarcasm detection.
Third, all models exhibit lower performance in the speaker-independent setup compared to the speaker-dependent one. This is attributed to the absence of speaker overlap between the training and testing sets in the speaker-independent configuration, making it more challenging than the speaker-dependent setting.
Fourthly, in both the speaker-dependent and speaker-independent settings, our model ULIL achieves an F1-score value that is 2\% and 2.8\% higher than the most recent baseline IWAN, respectively.
|
 IEEE/ICACT20240342 Slide.15
[Big Slide]