 |
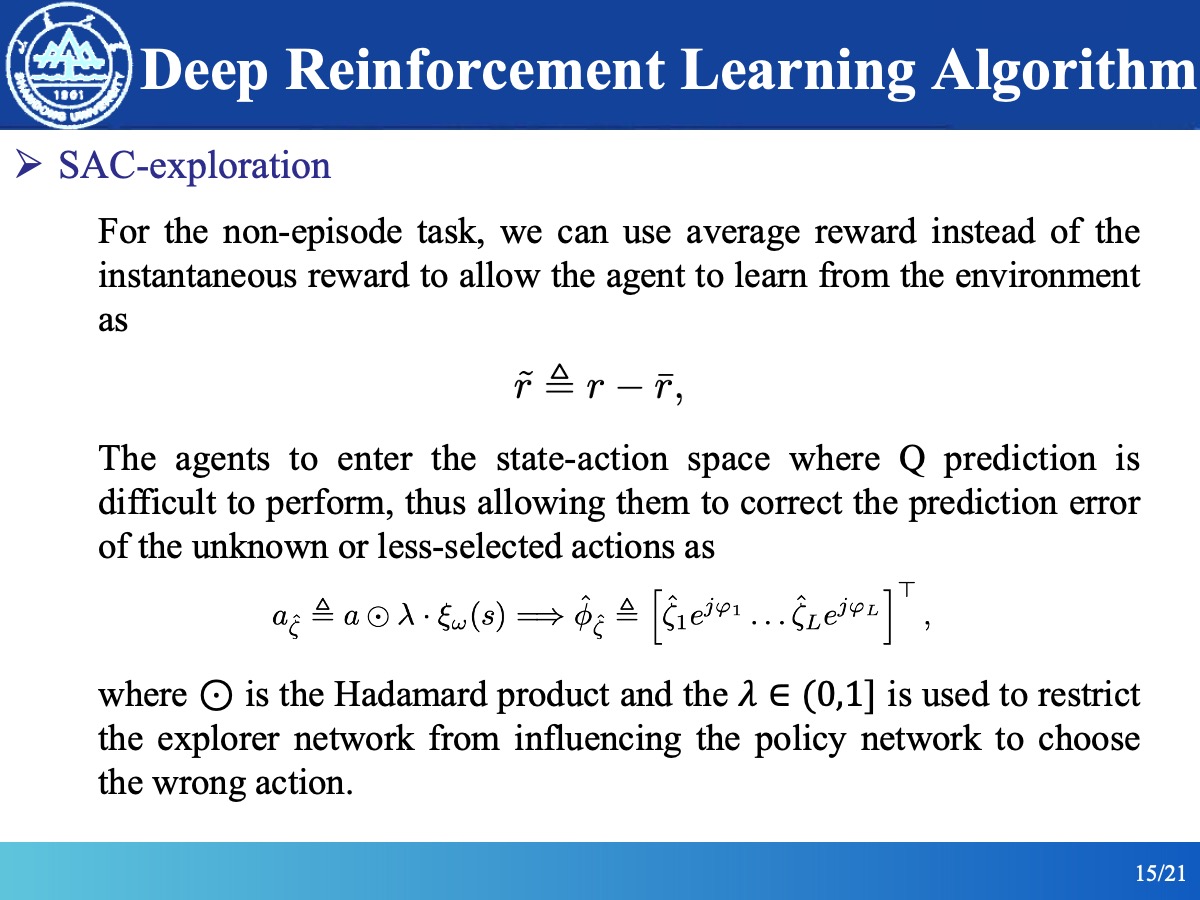
For the non-episode task, we can use average reward instead of the instantaneous reward to allow the agent to learn from the environment as the formula.
The agents to enter the state-action space where Q prediction is difficult to perform, thus allowing them to correct the prediction error of the unknown or less-selected actions as this formula, where ¢Á is the Hadamard product and the 𝜆¡ô(0,1] is used to restrict the explorer network from influencing the policy network to choose the wrong action.
|
 IEEE/ICACT20240375 Slide.15
[Big Slide]
[YouTube]