 |
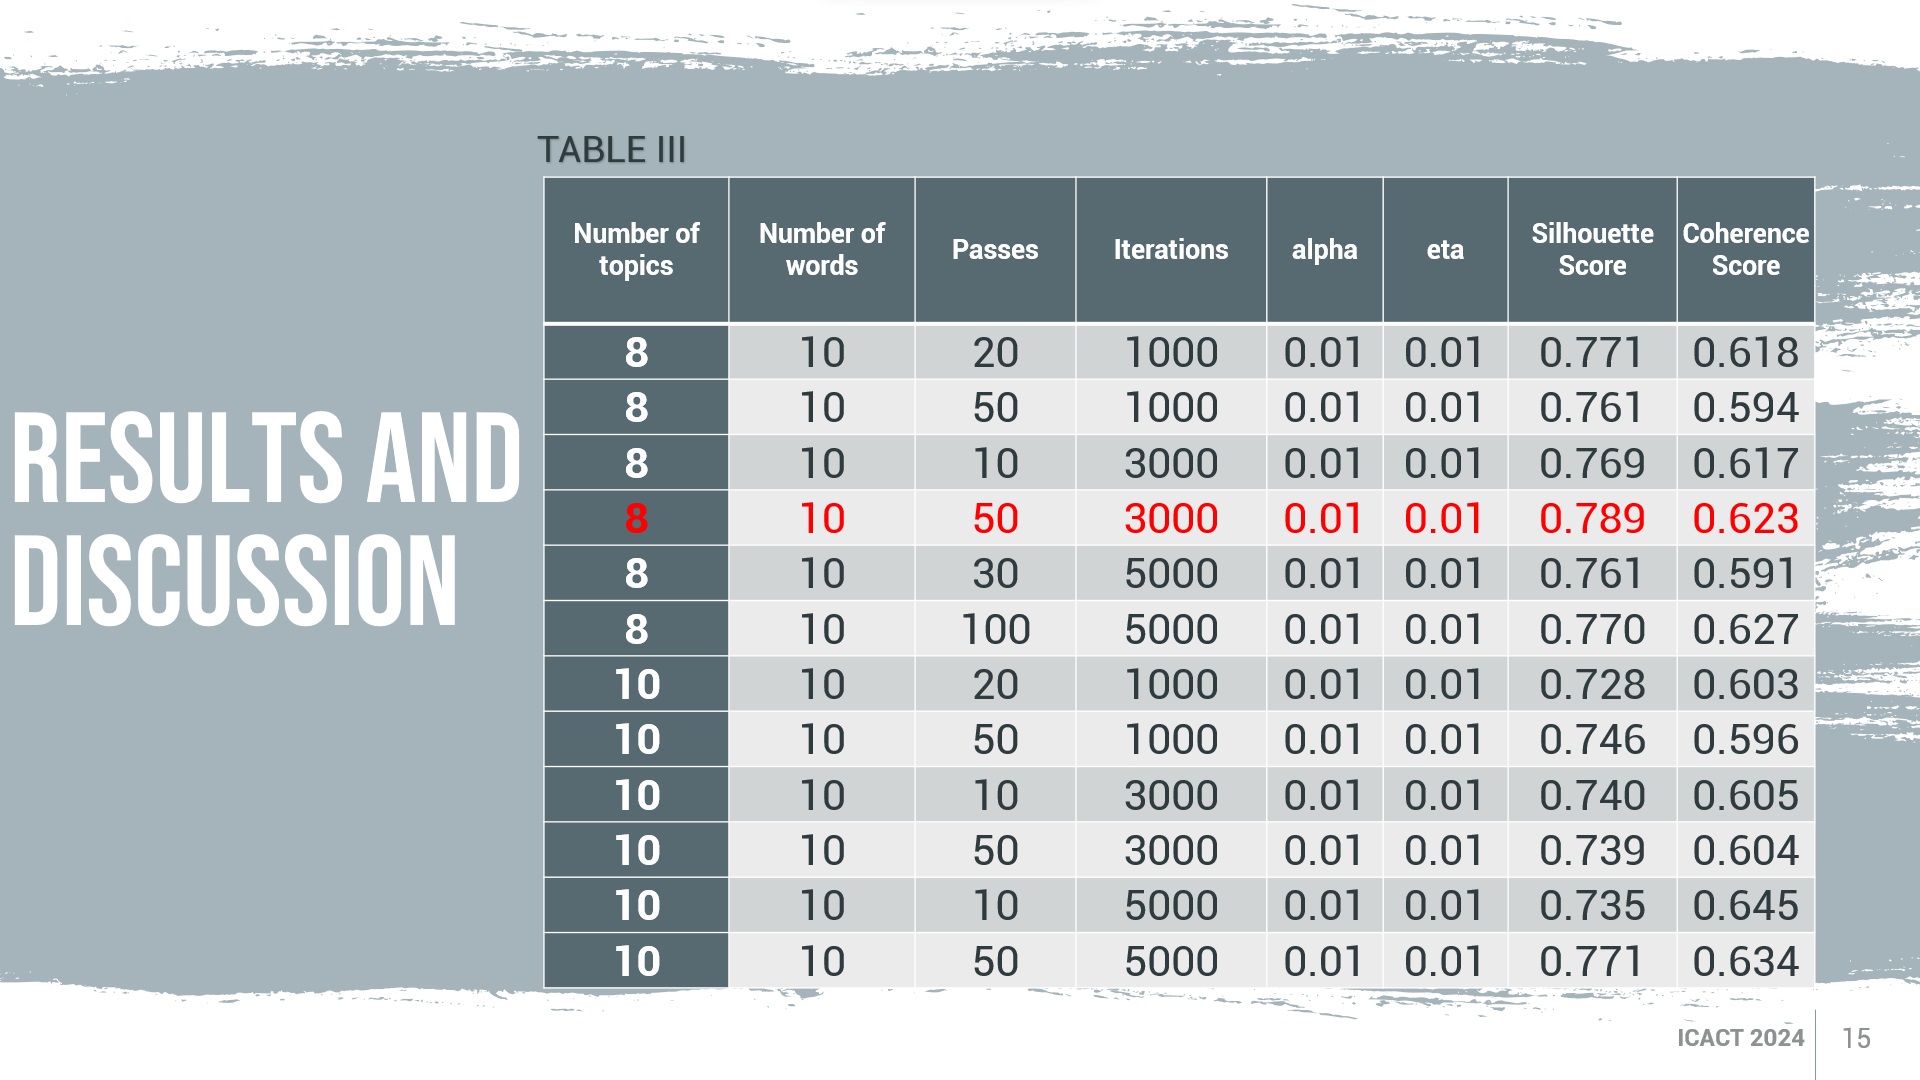
LDA model analysis investigated various configurations, including topics, words, passes, iterations, alpha, and eta, leading to variations in silhouette and coherence scores under different parameter settings, as indicated in Table 3. In particular, configurations with 8 topics, 50 passes, and 3000 iterations showcased higher silhouette scores, implying the model's effectiveness in creating more distinct data clusters. These settings reflect the LDA's strength in delineating clear groupings within the dataset. Although the coherence scores ranged between 0.591 and 0.645, indicating some challenges in capturing complex semantic relationships due to the probabilistic nature of LDA, the model still showed a considerable degree of effectiveness in associating topics and words. This was instrumental in generating relevant labels. Despite the relatively modest coherence scores, LDA demonstrated its capability to formulate coherent and meaningful topics. This underscores its value in delivering interpretable and insightful dataset representations, highlighting its practical importance in data analysis. |
 IEEE/ICACT20240447 Slide.15
[Big Slide]