 |
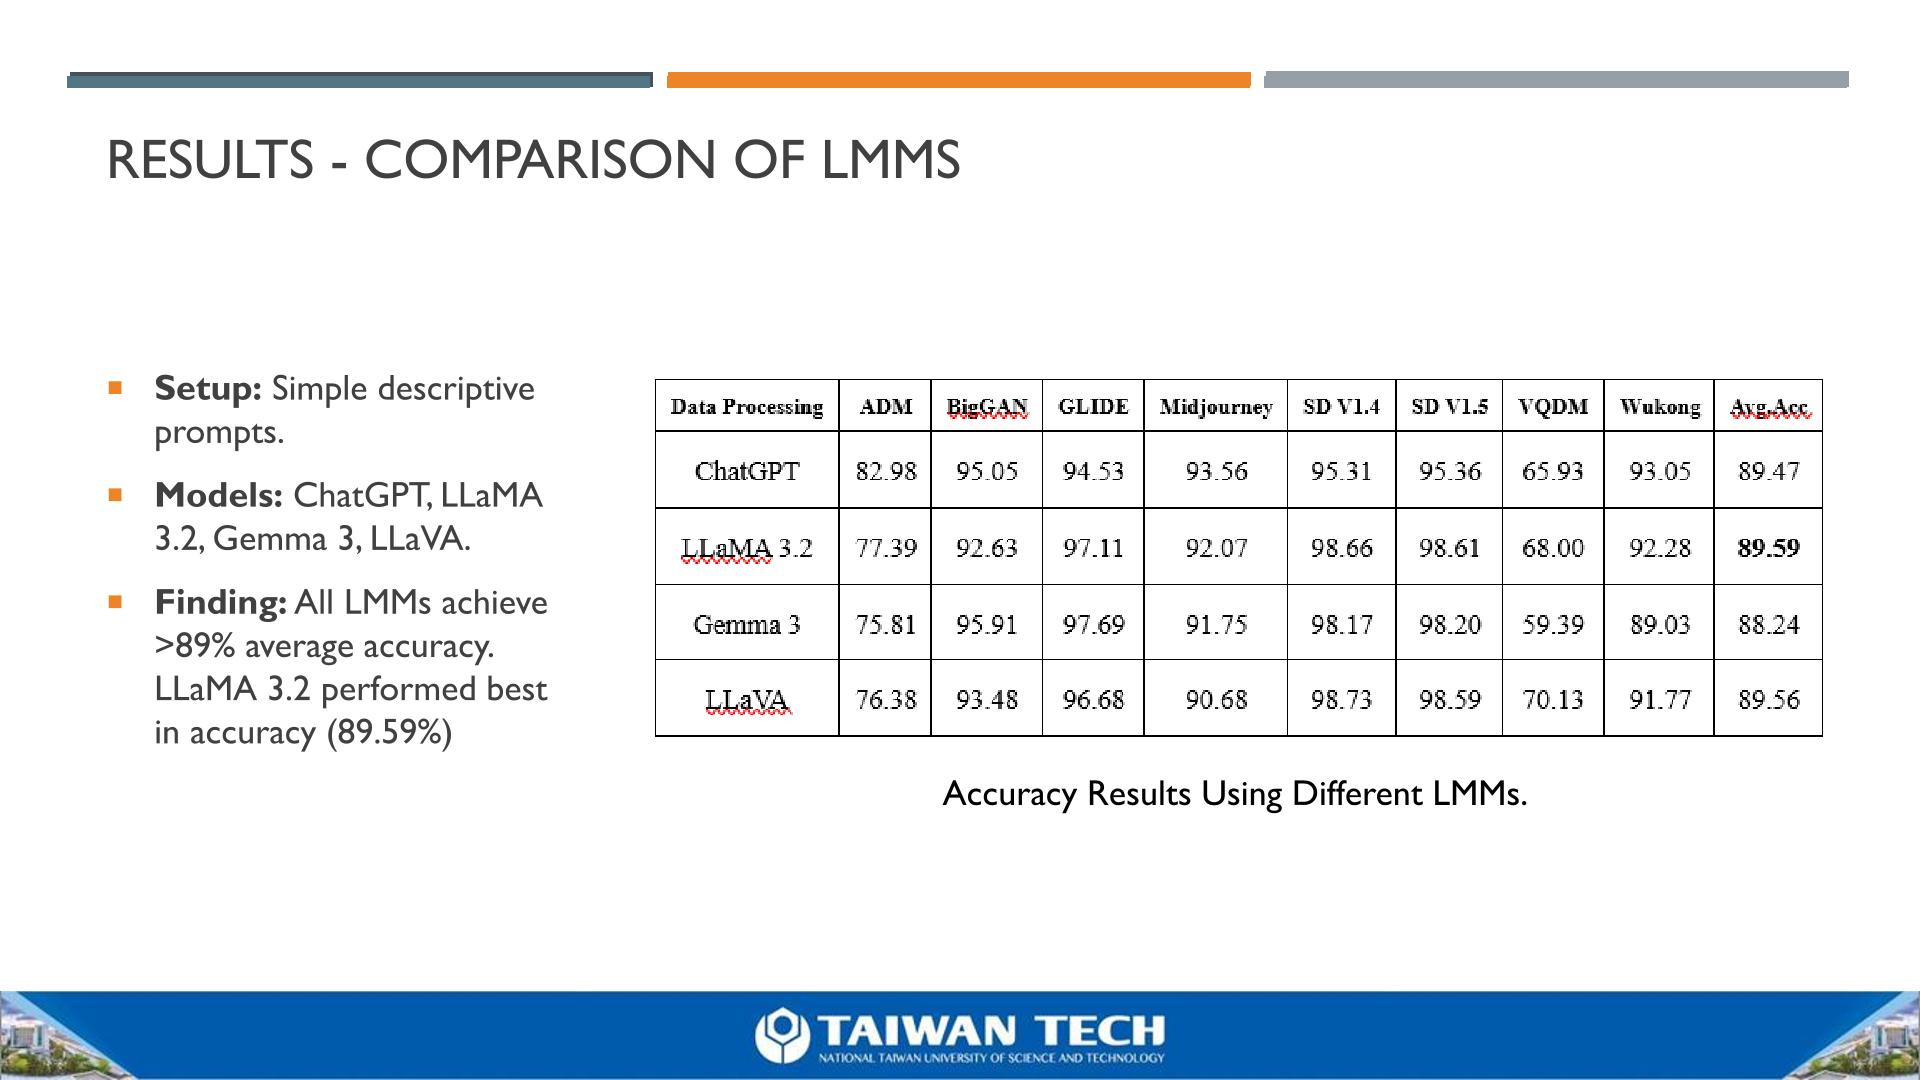
The detection module was evaluated using descriptions generated by various LMMs, including ChatGPT, LLaMA 3.2, Gemma 3, and LLaVA. The results in Table 4.6 indicate that regardless of the model utilized, the average accuracy consistently exceeds 89%, with LLaMA 3.2 achieving the highest accuracy at 89.59% . This demonstrates that the GIDLMM framework generalizes effectively across different multimodal architectures . Additionally, detection performance on advanced generators like Midjourney and Stable Diffusion proved particularly strong, with AUC scores exceeding 97%. |
 IEEE/ICACT20260070 Slide.15
[Big Slide]