 |
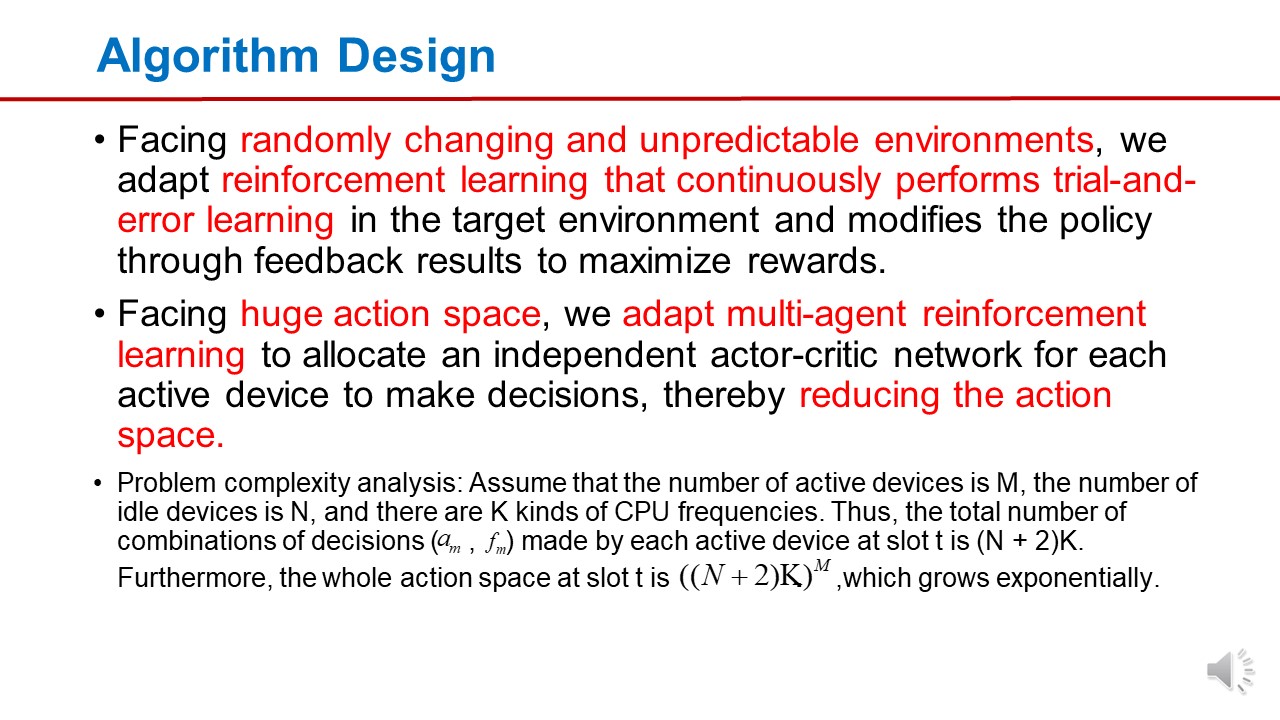
In order to solve this problem, we need to consider the characteristics of the problem mentioned before: therefore, we utilize the reinforcement learning algorithm based on the principle of trial and error to cope with randomly changing system states and output decisions online.
Facing a huge action space, we refine the subject of decision-making into each device, so that the problem can be solved by using a multi-agent reinforcement learning algorithm.
If we do not use the multi-agent algorithm, the size of the action space will be exponentially related to the number of active devices, but after using the multi-agent algorithm, it will be linear
|
 IEEE/ICACT20230243 Slide.16
[Big Slide]
[YouTube]