 IEEE/ICACT20230276 Slide.16
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230276 Slide.16
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
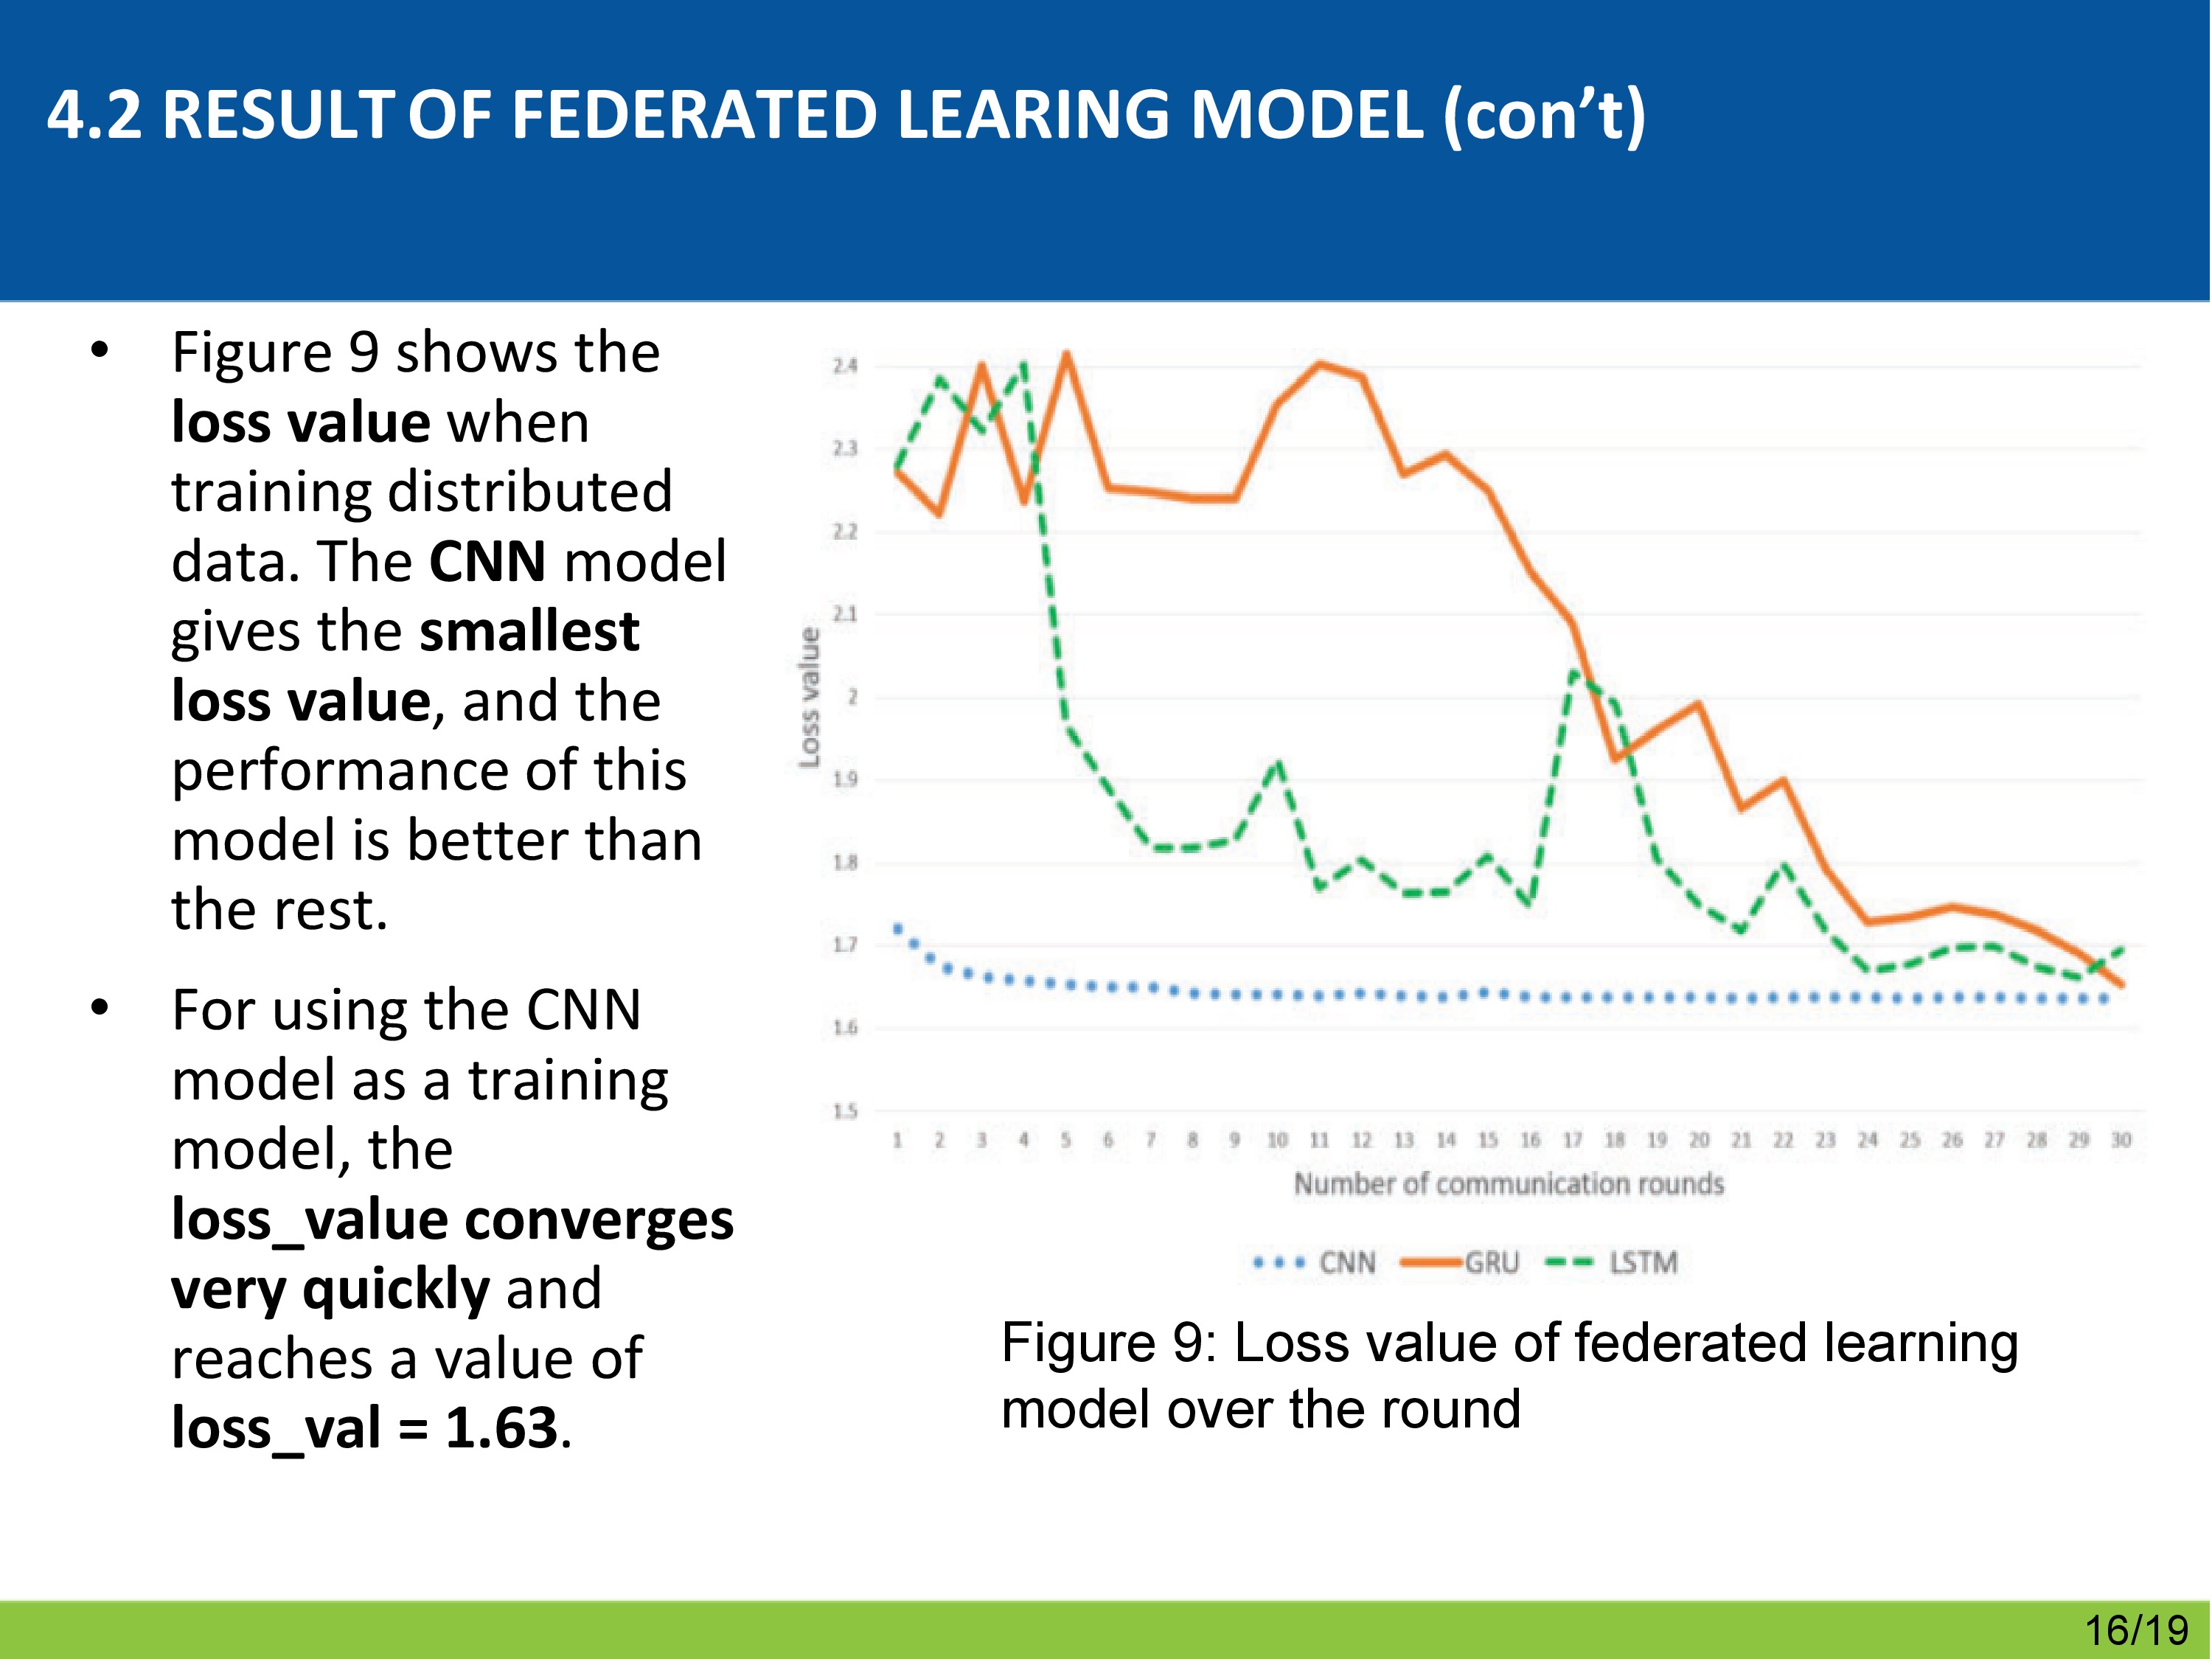
This is the loss value of the training model when experimenting with the FEDERATED LEARING MODEL Figure 9 shows the loss value when training distributed data. The CNN model gives the smallest loss value, and the performance of this model is better than the rest. For using the CNN model as a training model, the loss_value converges very quickly and reaches a value of loss_val = 1.63. | |
| [Go to Next Slide] |