 |
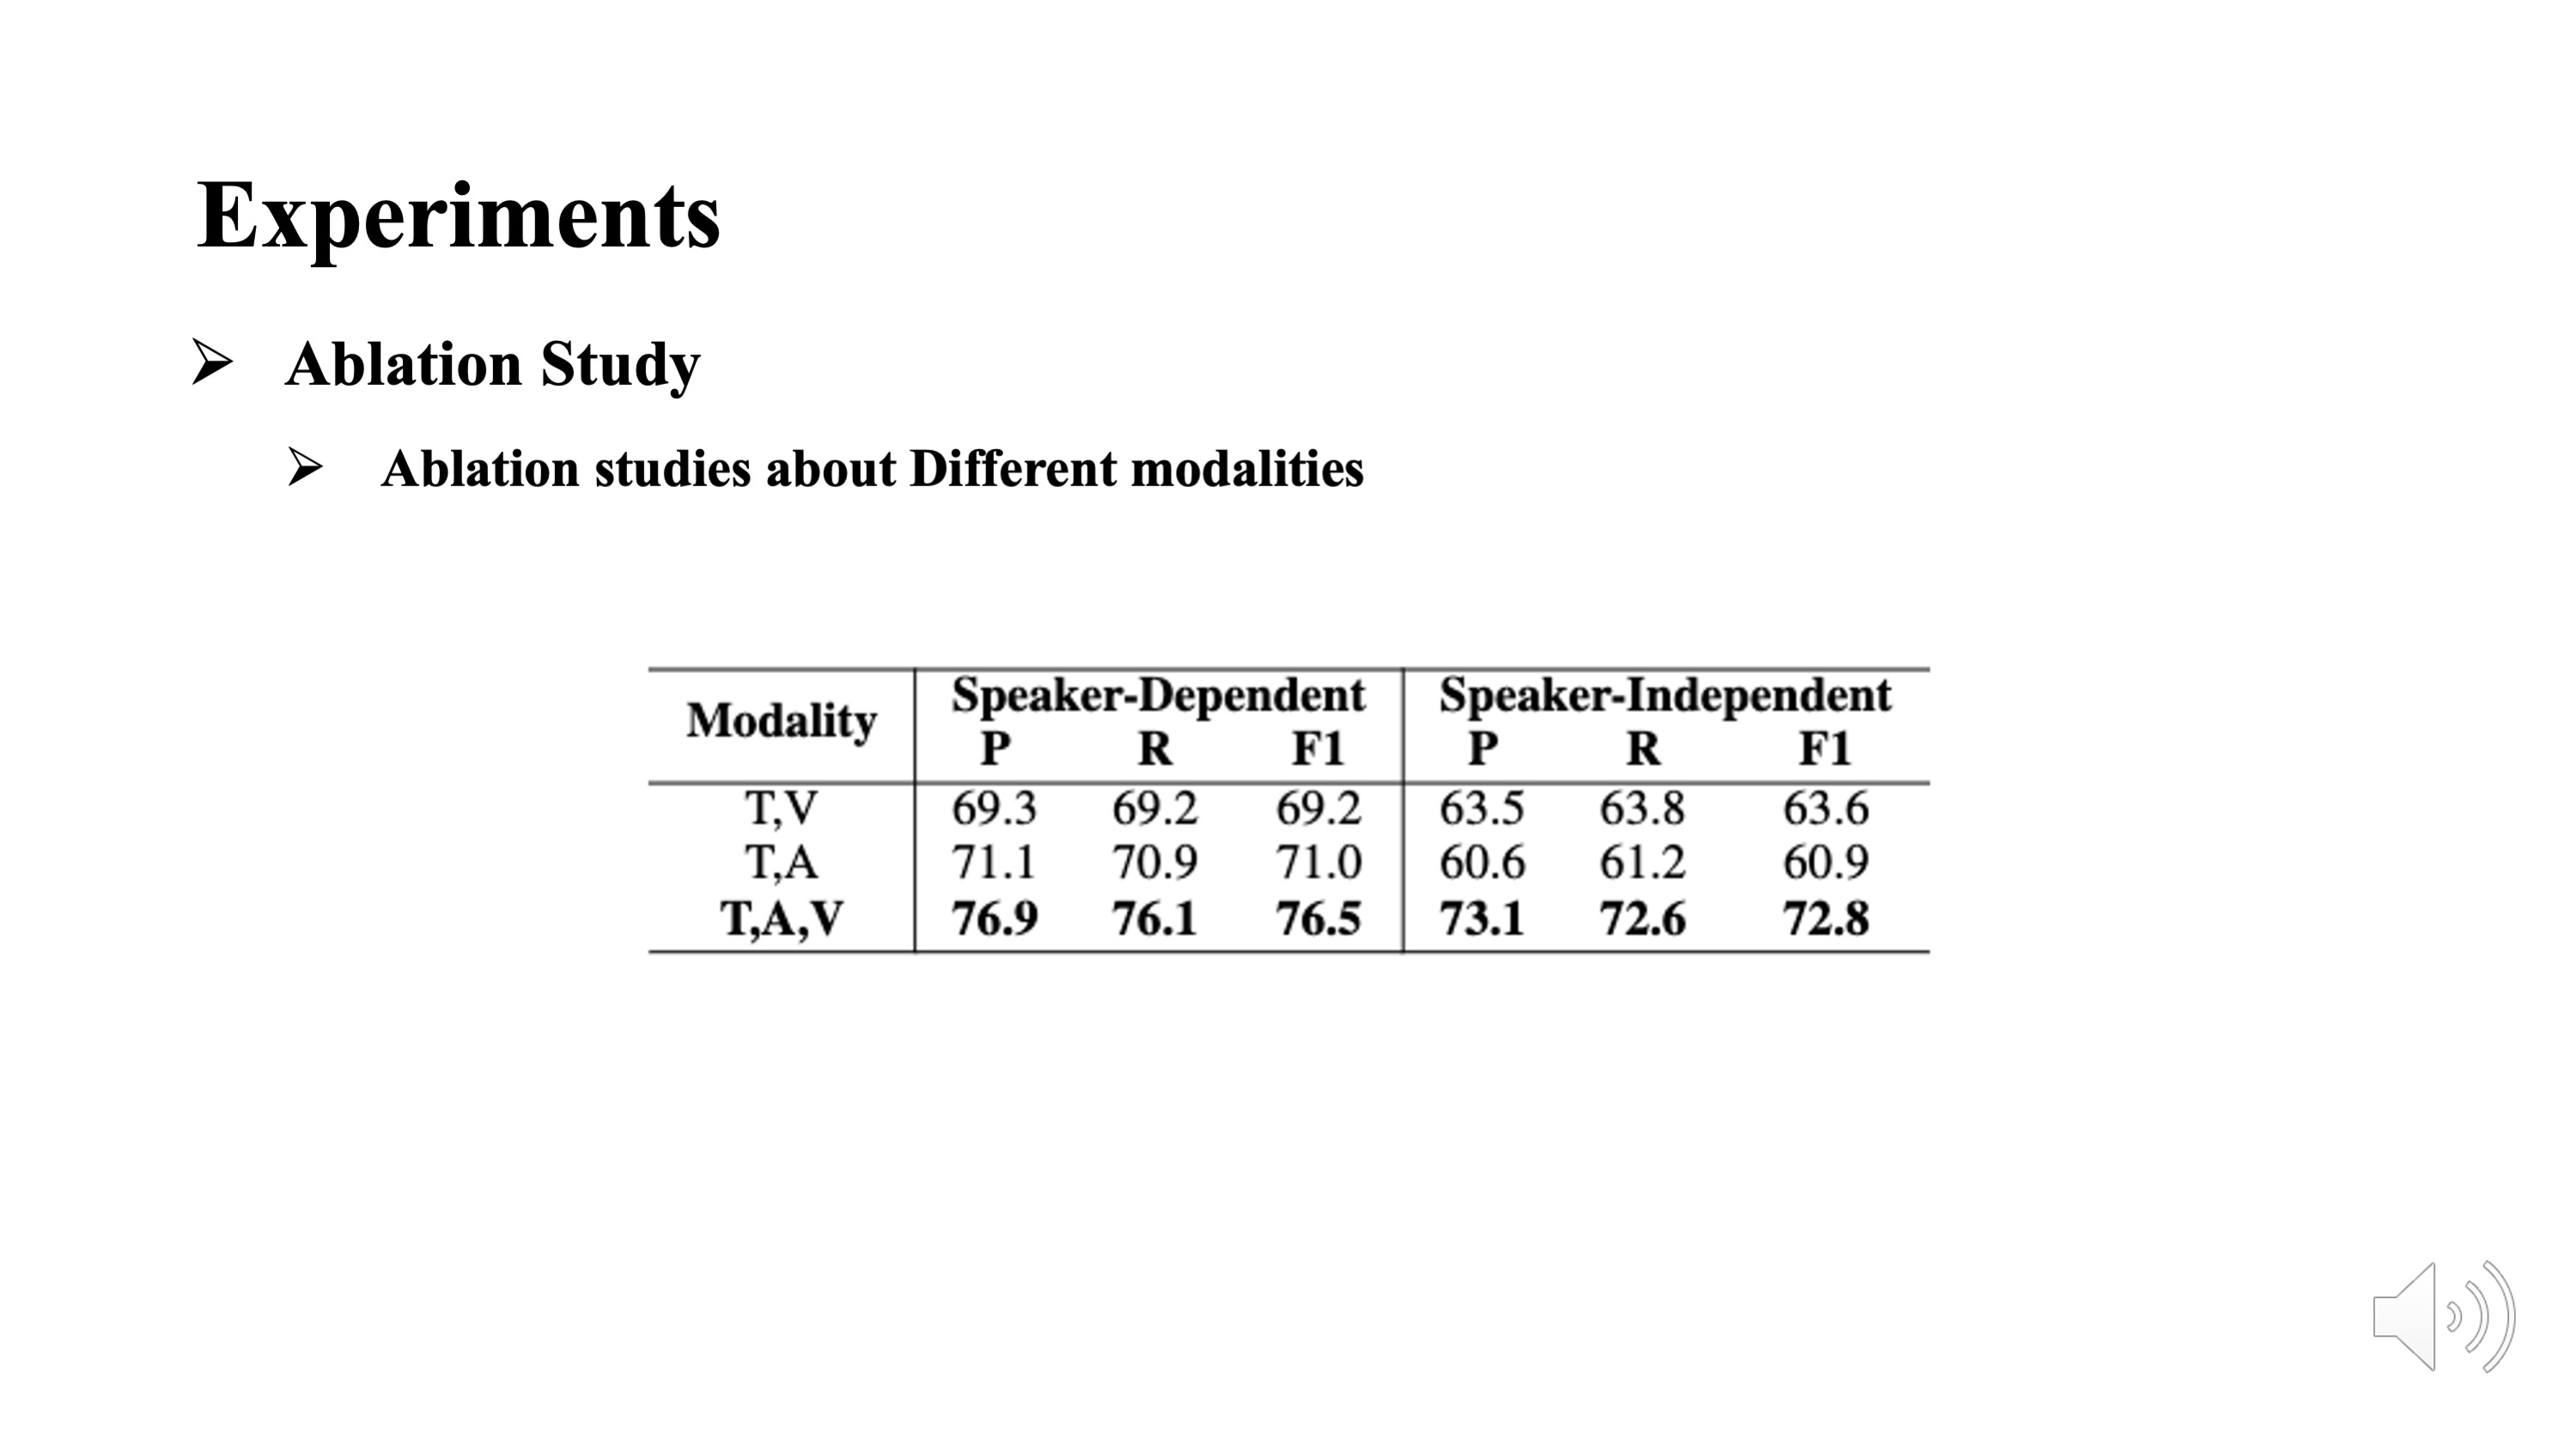
To further analyze our proposed model and assess the necessity of the three modalities, we conduct ablation experiments on the dataset with different modalities removed. As text modality is the most fundamental, we separately removed audio and vision modalities and recorded the experimental results in Table. Removing either audio or vision modality leads to a performance drop, indicating the crucial importance of these two modality features for the sarcasm detection task. Audio and vision modality features complement text features, enabling a more comprehensive capture of inconsistent features.
|
 IEEE/ICACT20240342 Slide.16
[Big Slide]