 IEEE/ICACT20250091 Slide.16
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250091 Slide.16
[Big Slide]
| Oral Presentation |
|
|
|
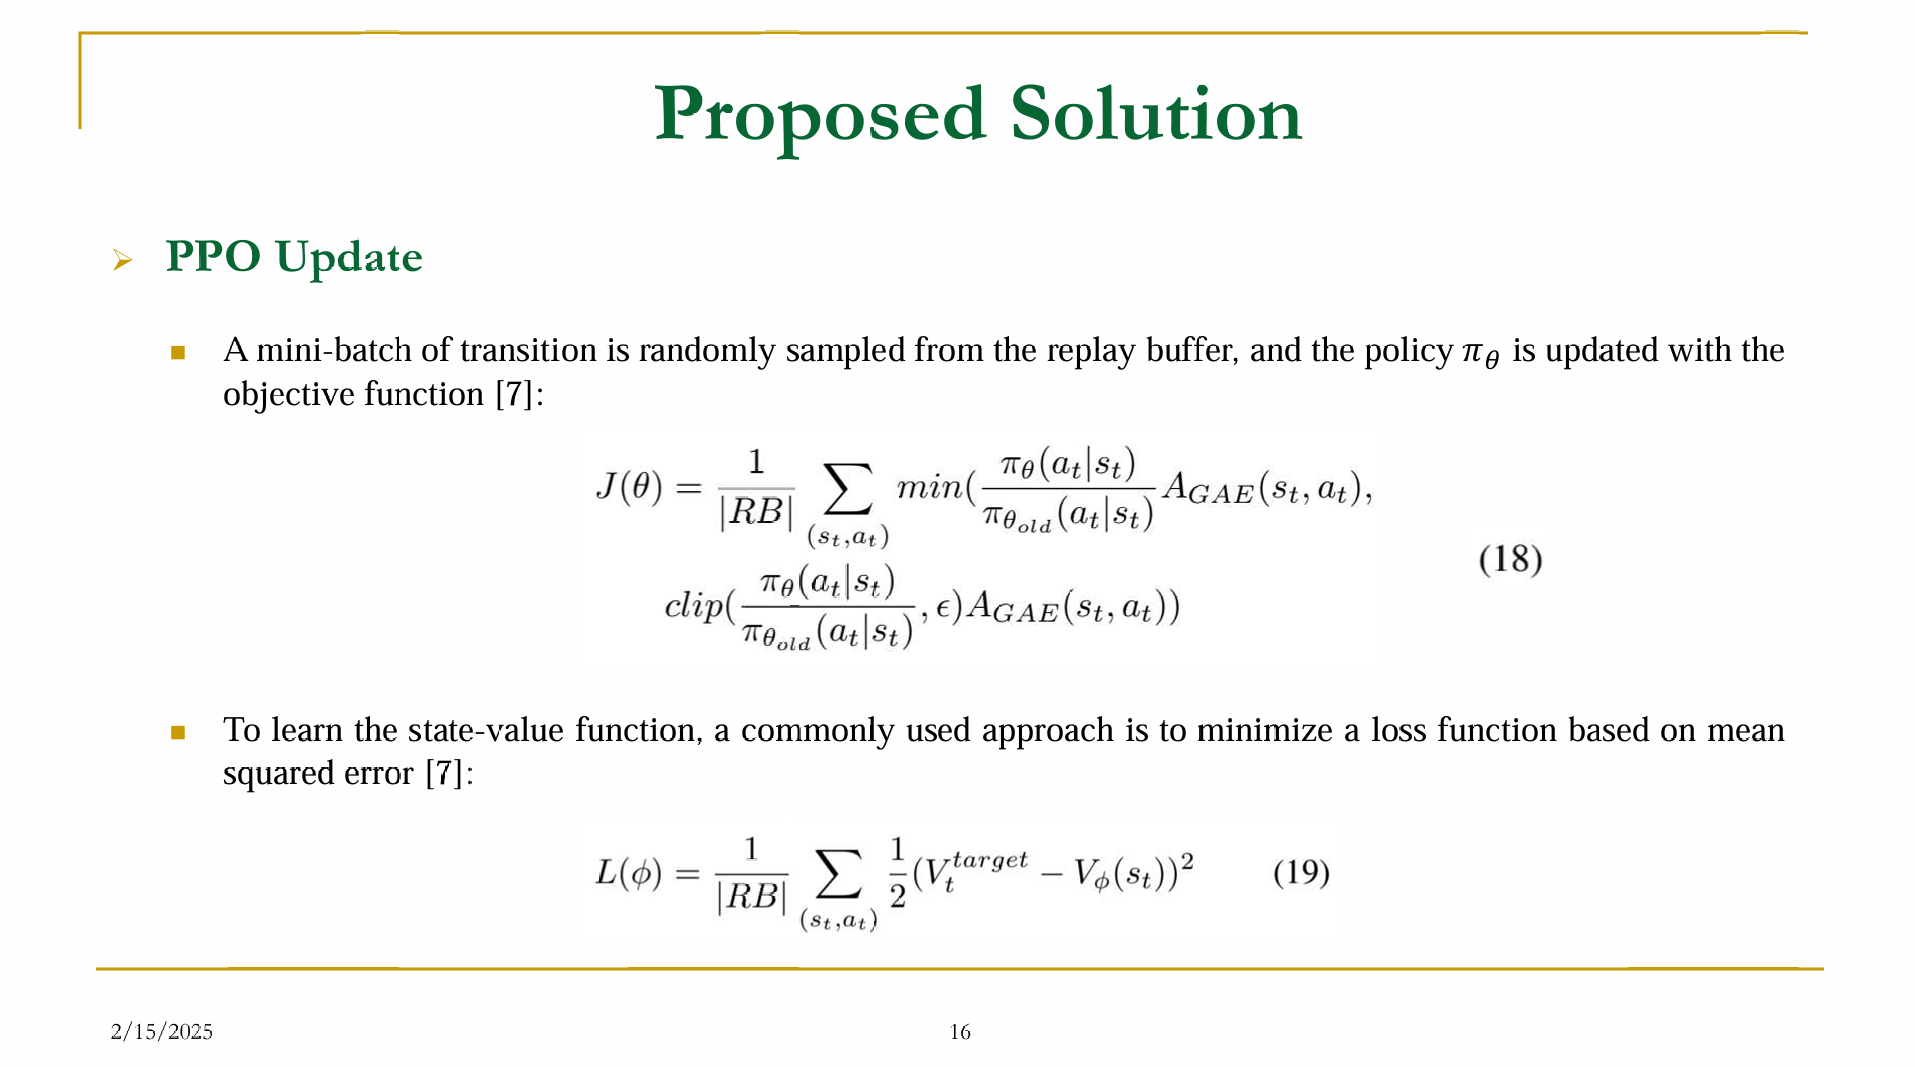
A mini-batch of transition is randomly sampled from the replay buffer, and the policy 𝜋_𝜃 is updated with the objective function 18. To learn the state-value function, a commonly used approach is to minimize a loss function based on mean squared error which can be represented by eqution 19. | |
| [Go to Next Slide] |