 IEEE/ICACT20260085 Slide.16
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20260085 Slide.16
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
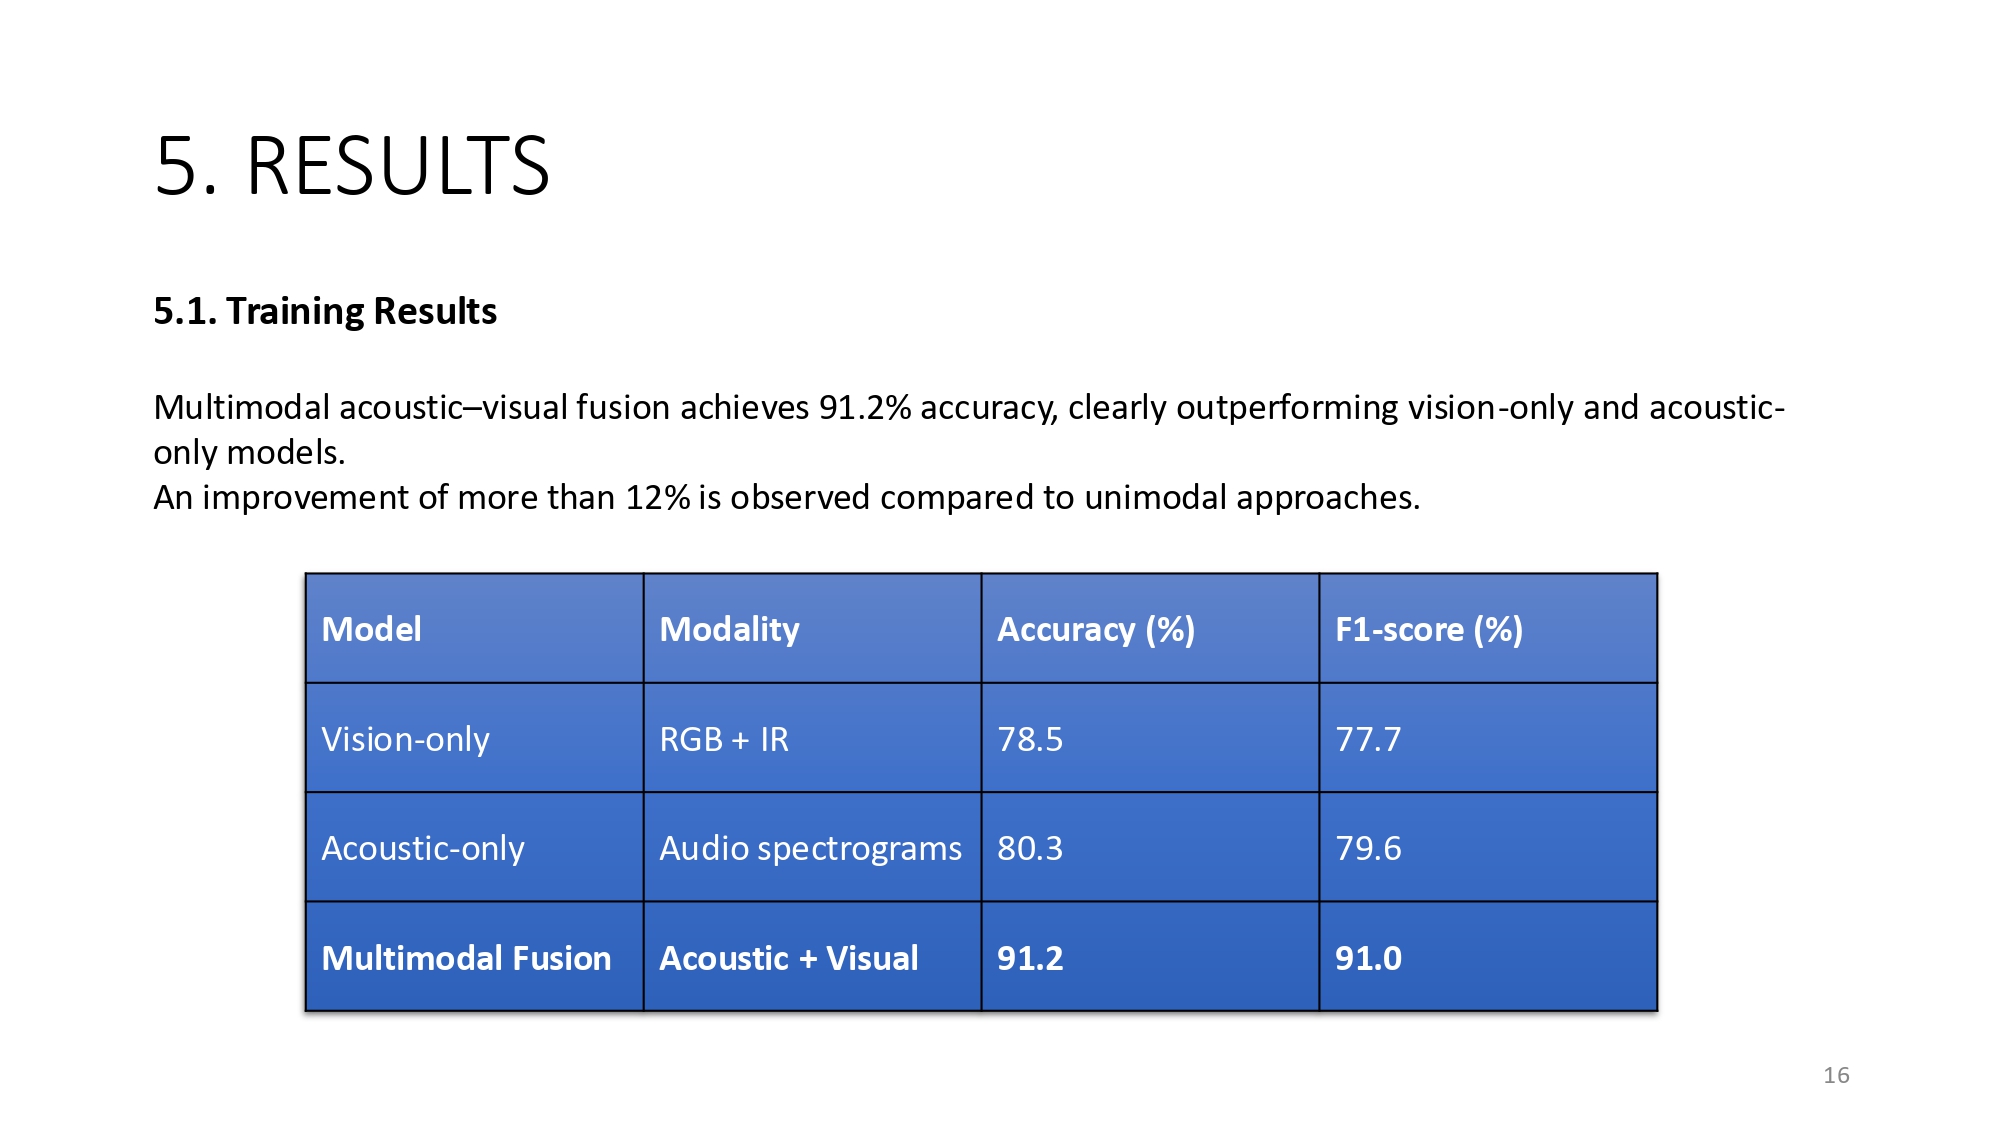
Our training results demonstrate that the proposed acoustic–visual multimodal fusion significantly outperforms unimodal approaches. While vision-only and acoustic-only models achieve accuracies of 78.5% and 80.3% respectively, the multimodal fusion model reaches 91.2% accuracy with an F1-score of 91.0%. This corresponds to an improvement of more than 12% compared to unimodal systems, highlighting the effectiveness of combining complementary acoustic and visual information during training. | |
| [Go to Next Slide] |