 IEEE/ICACT20240375 Slide.17
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20240375 Slide.17
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
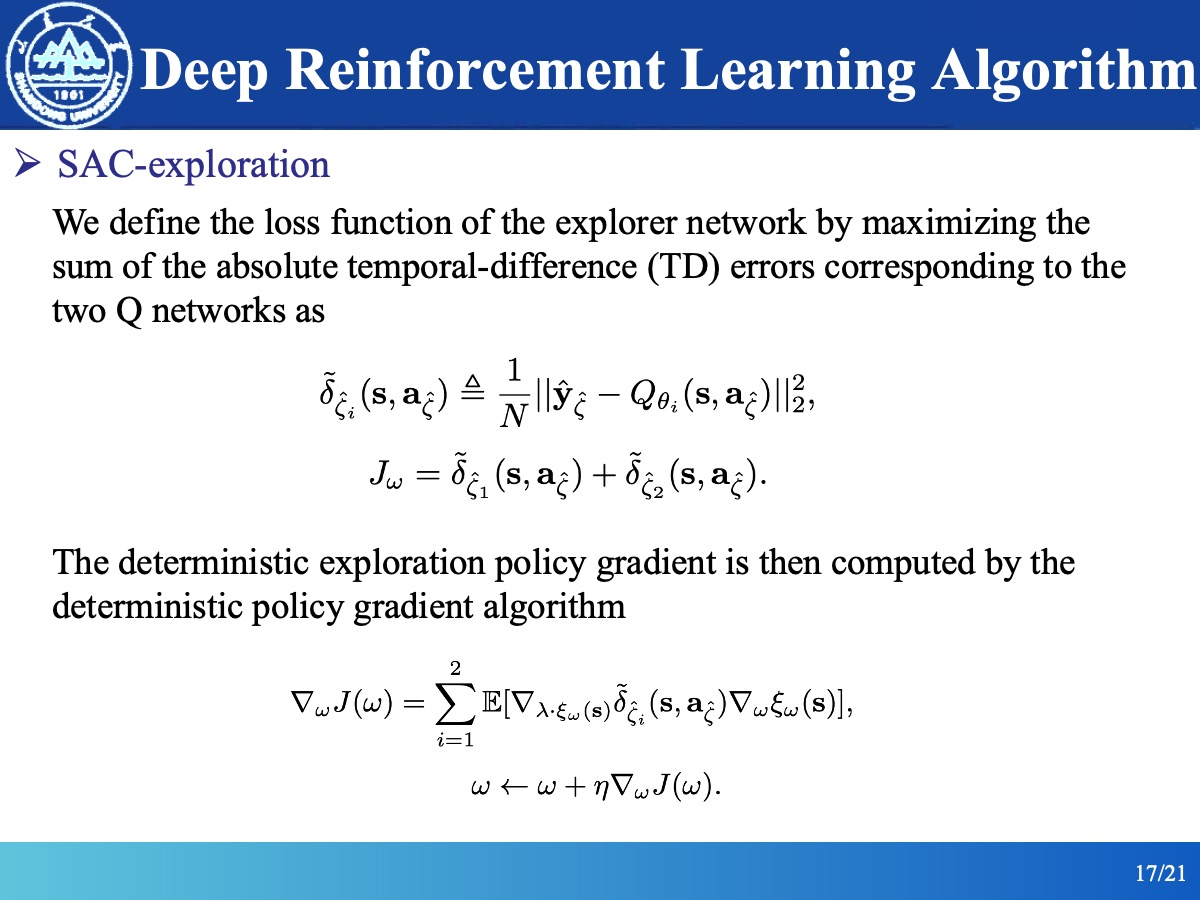
We define the loss function of the explorer network by maximizing the sum of the absolute temporal-difference (TD) errors corresponding to the two Q networks as the formula.The deterministic exploration policy gradient is then computed by the deterministic policy gradient algorithm. | |
| [Go to Next Slide] |