 IEEE/ICACT20250006 Slide.17
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250006 Slide.17
[Big Slide]
| Oral Presentation |
|
|
|
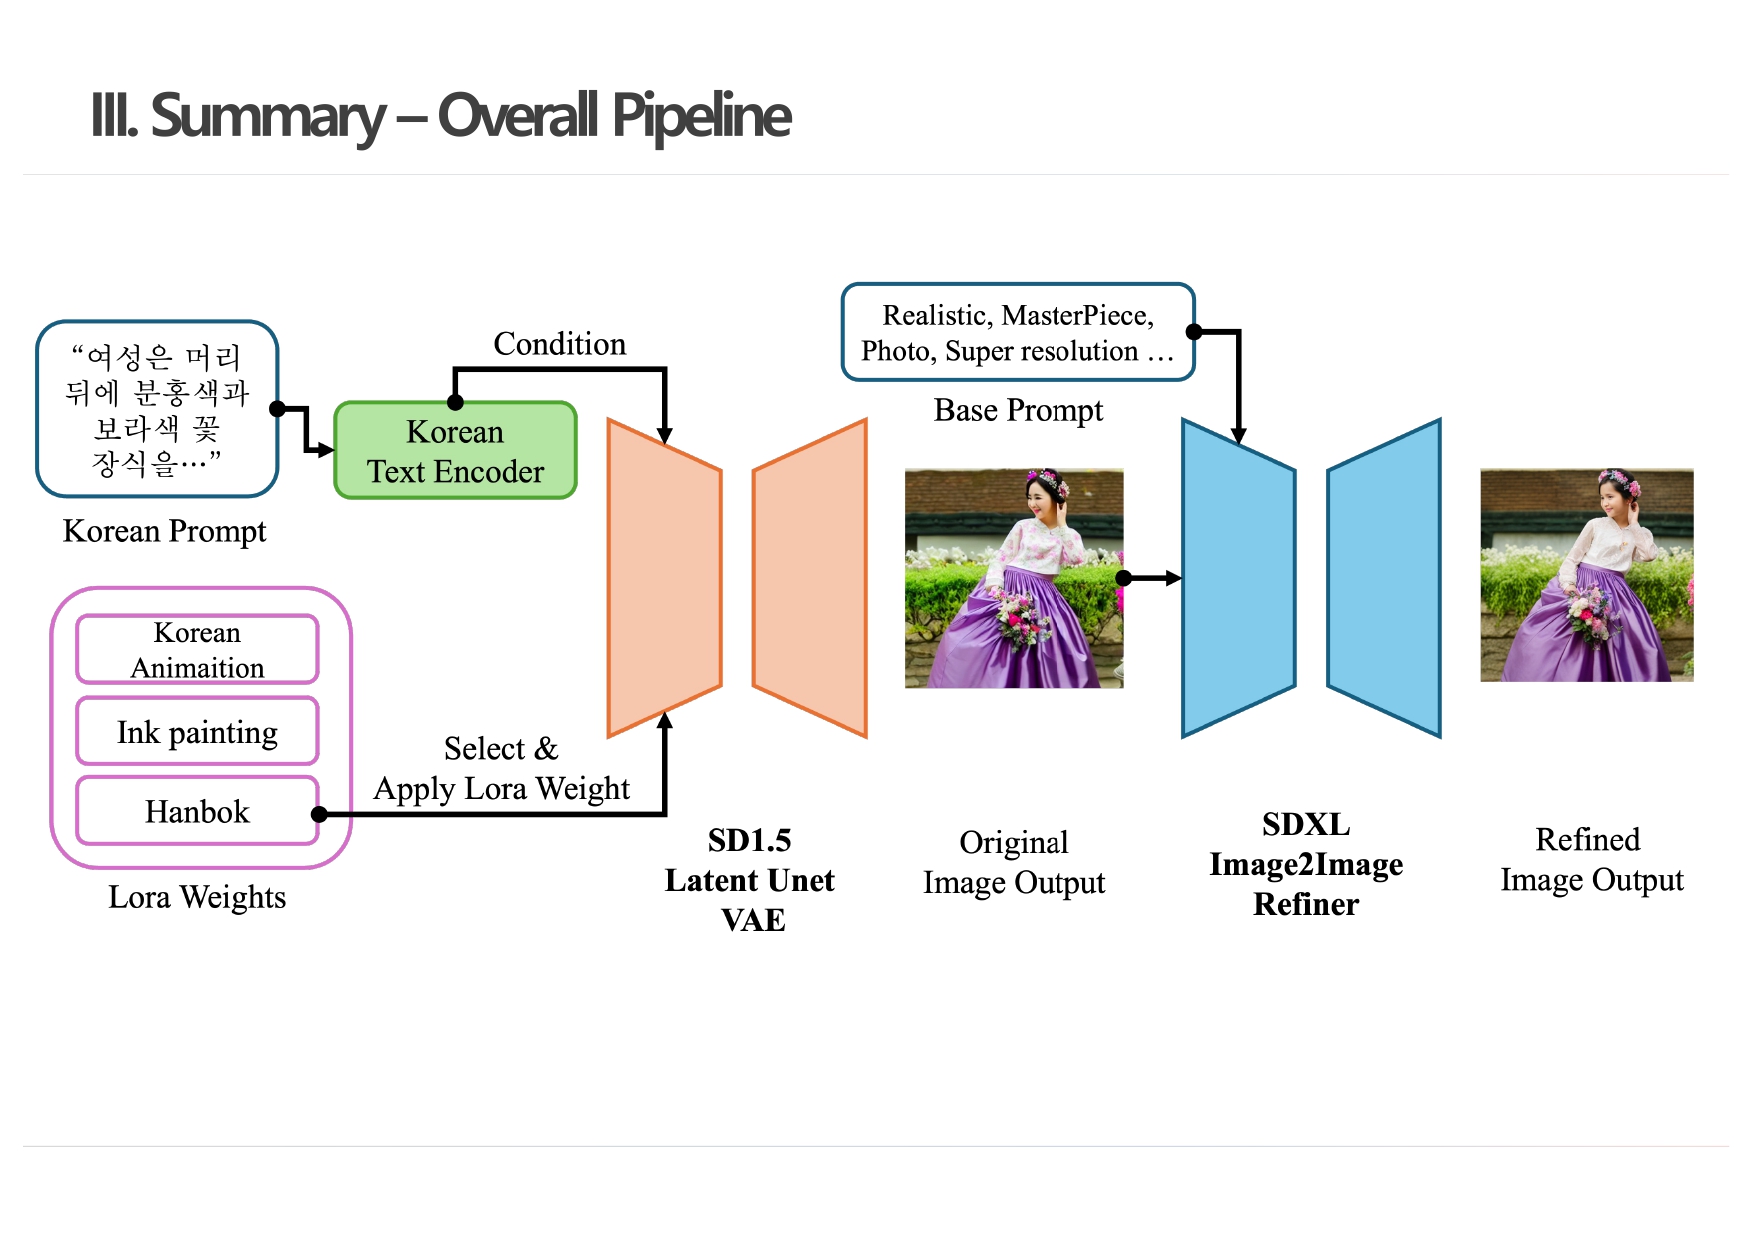
Our pipeline takes the generator from the Stable Diffusion 1.5 model and the image created based on the Korean Text Encoder and feeds it back into the Image Refiner in the SDXL model. We use a Base Prompt such as ¡°Realistic, Masterpiece,¡± etc. as the Text Condition for the SDXL model's Image Refiner, and output the final image after passing through the SDXL model's Refiner. | |
| [Go to Next Slide] |