 |
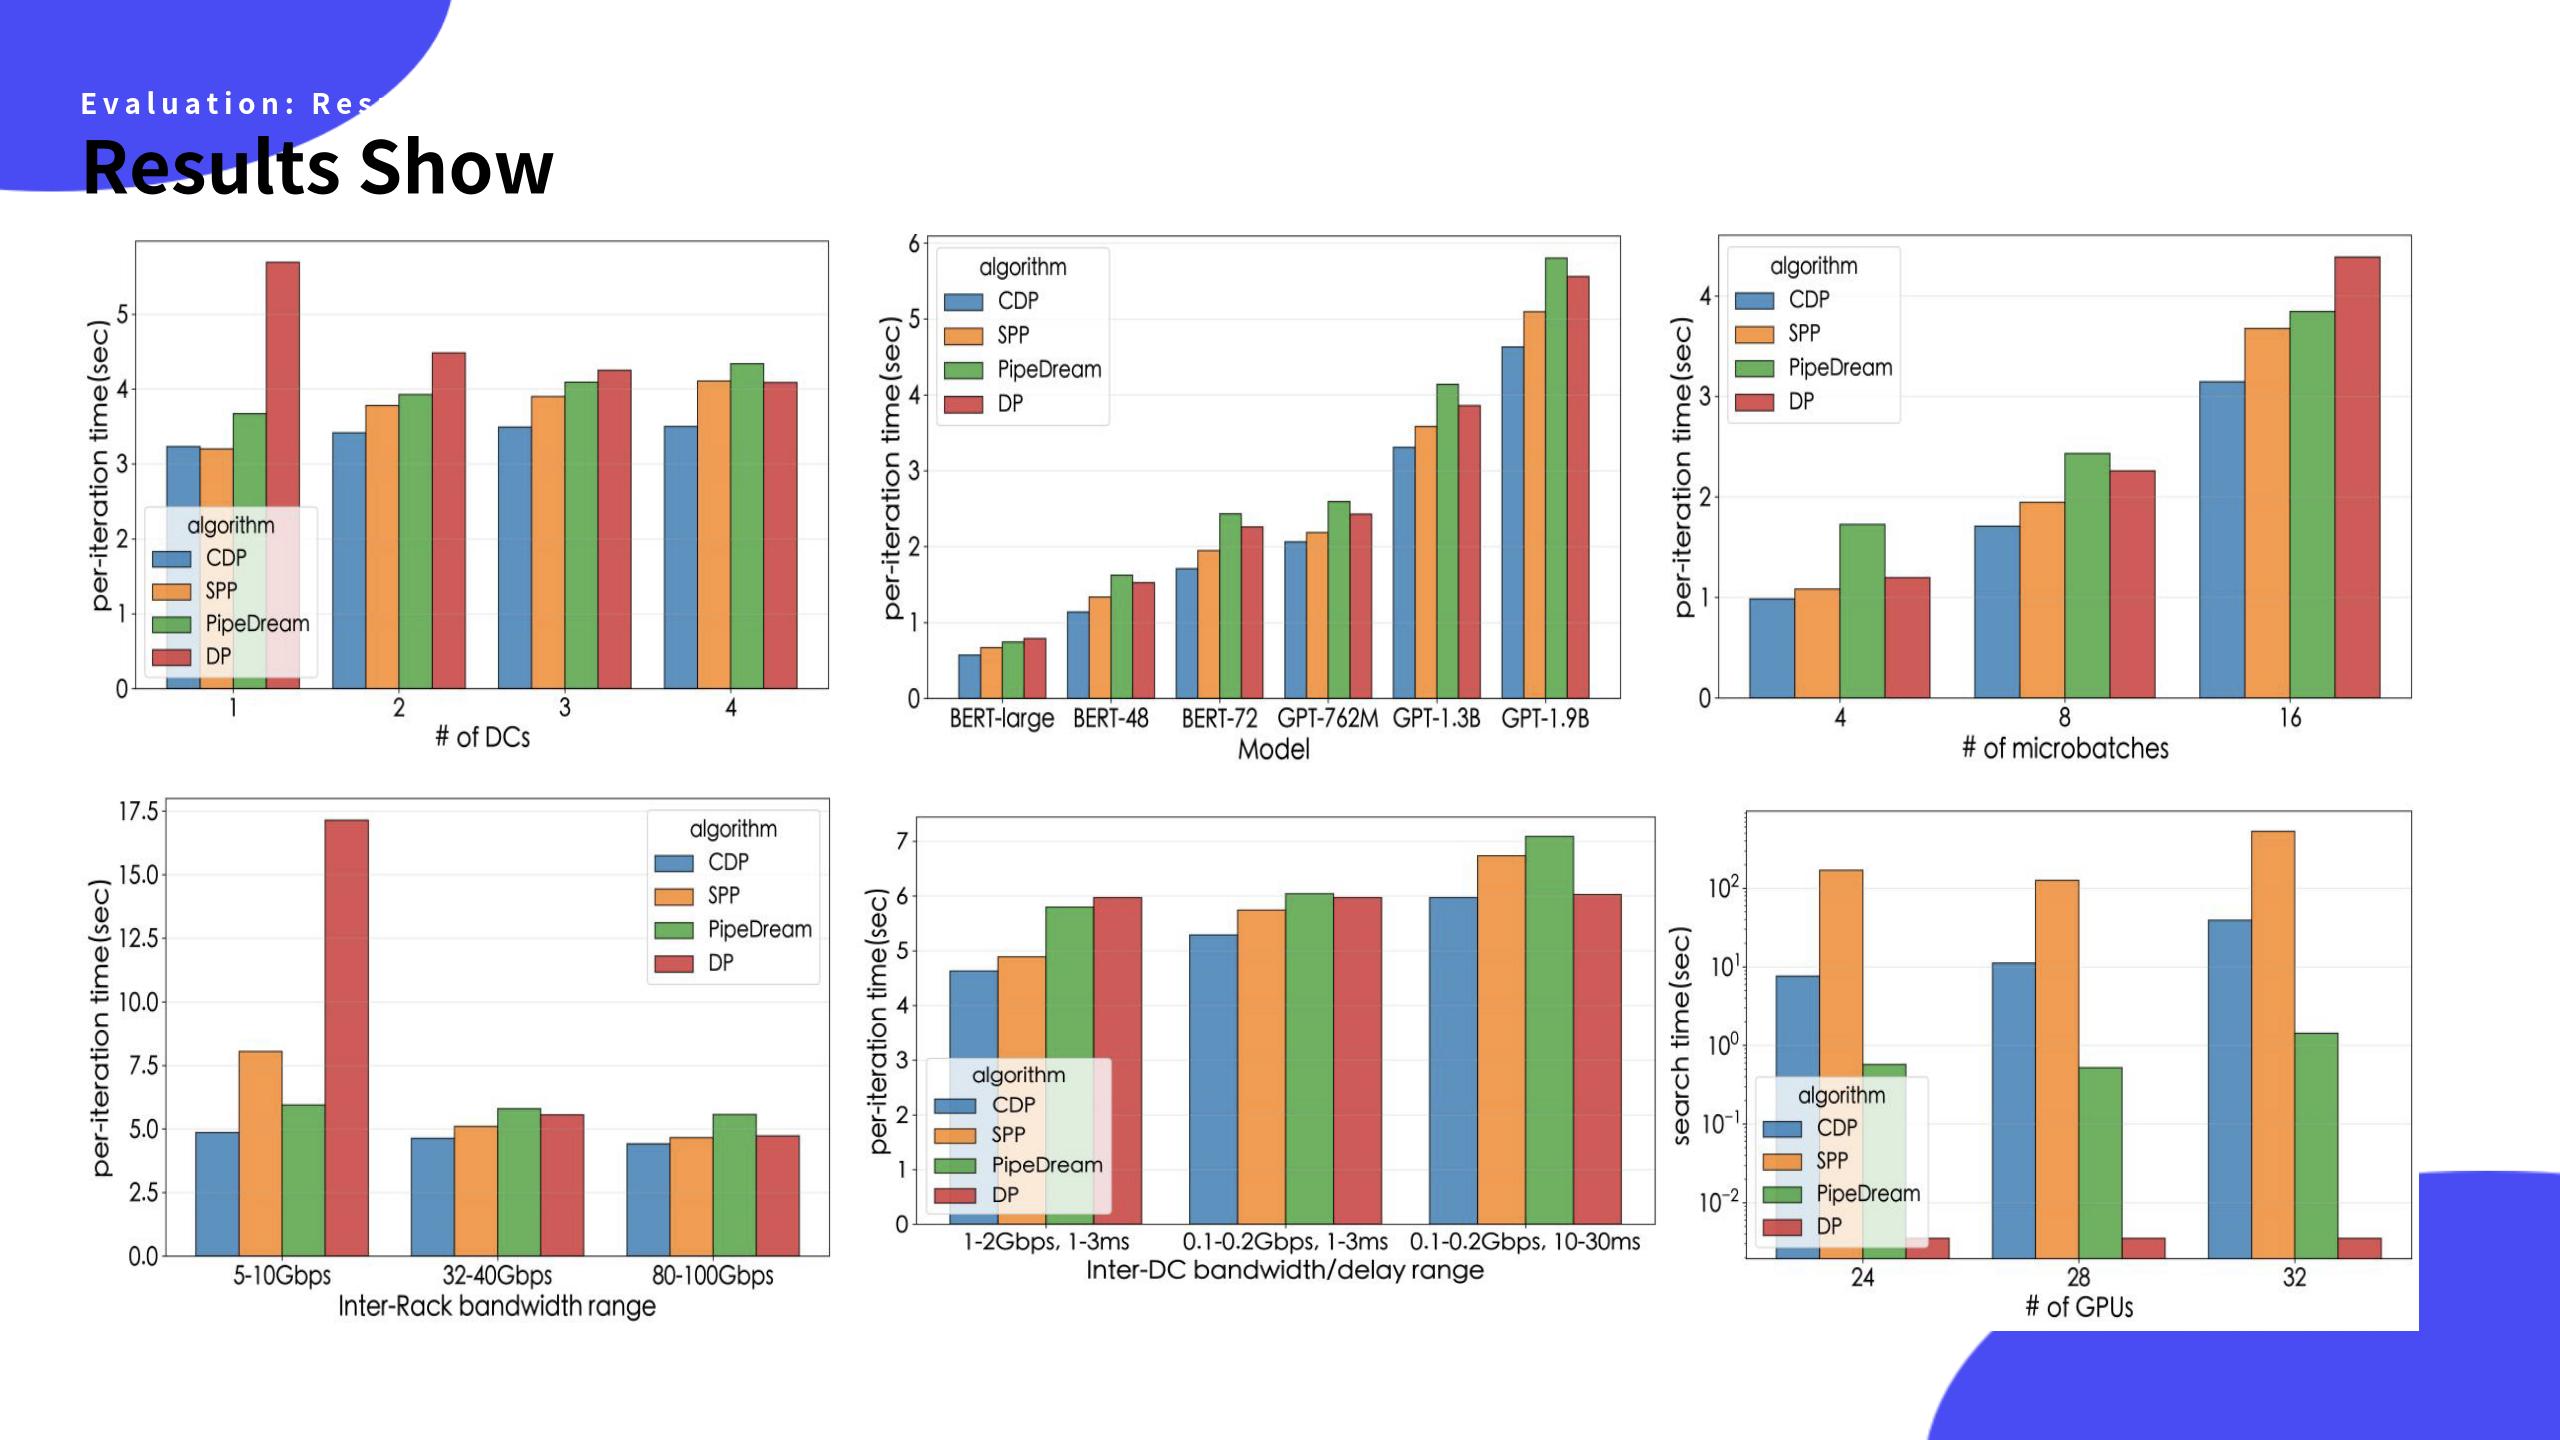
Our results show that CDynP consistently outperforms baselines. For example, when scaling from one to four DCs, CDynP limited the iteration time increase to just 8.3%, compared to 16% or more for others.As seen in Figure 1, CDynP adapts better to DC scaling. Similarly, for larger models like GPT-1.9B, it reduced training time by 10.1% over SPP by optimizing stage counts and bubble overhead.Figure 2 highlights this model-scale adaptability.CDynP also excels under network variations. For instance, with degraded inter-DC bandwidth, it maintained the slowest increase in iteration time.Figure 4 shows CDynPs stability across bandwidth levels. In terms of algorithm efficiency, CDynP achieved a search time of 39.27 seconds—13.4 times faster than SPP—due to its chain-based approach.Figure 6 illustrates this speed advantage. |
 IEEE/ICACT20260329 Slide.17
[Big Slide]
[YouTube]