 |
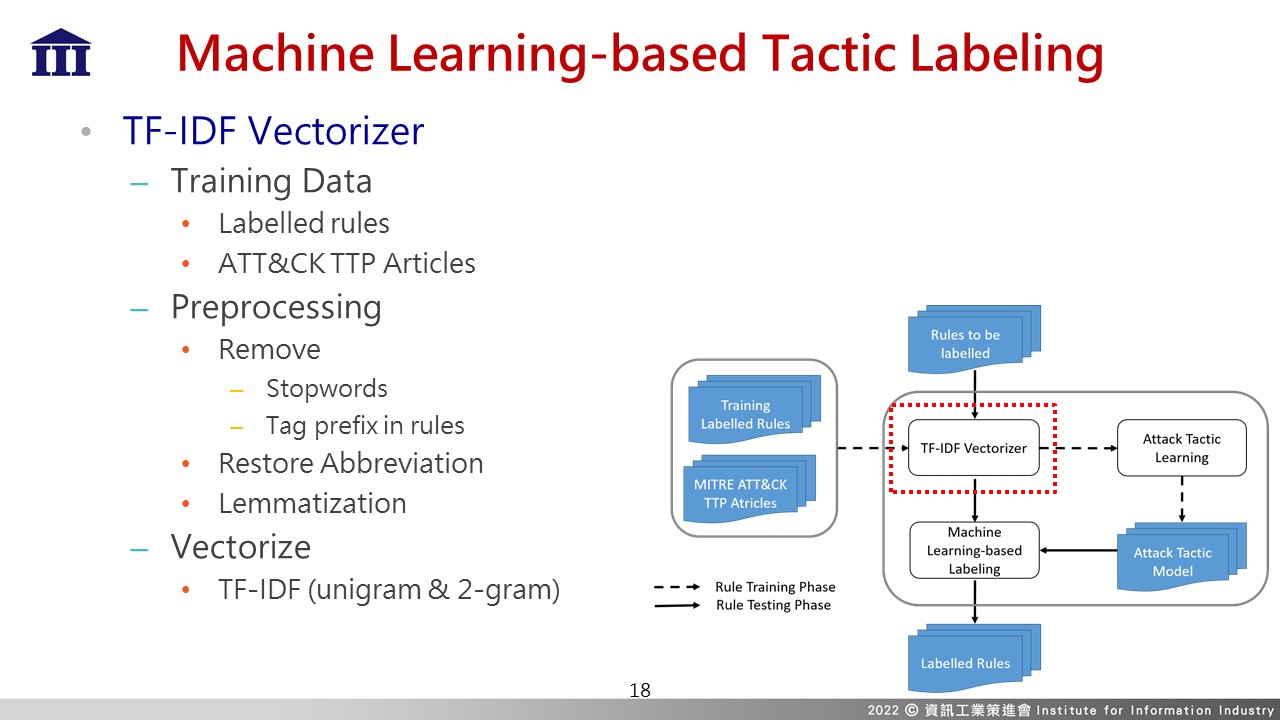
TF-IDF Vectorizer in Machine learning-based labeling includes the training phase and testing phase. In the training phase, training dataset is composed of two sources. One is MITRE textual data, the same as the one in similarity-based labeling. The other one is the labeled result from similarity-based labeling. In the testing phase, the terms in unlabeled Suricata rules will be converted into the feature vector for machine learning methods to identify tactics.
กก
In this function, the ways for preprocessing is the same as the ways used in similarity-based labeling that is removing stopwords and the tag prefix in messages field, restoring the abbreviations and lemmatizing each vocabulary. By doing so, we reduce the influence of irrelevant noise for the prediction model.
กก
After the preprocessing, we still use the original unigram and combine it with 2-gram to retain the semantic and contextual information. |
 IEEE/ICACT20220038 Slide.18
[Big Slide]