 |
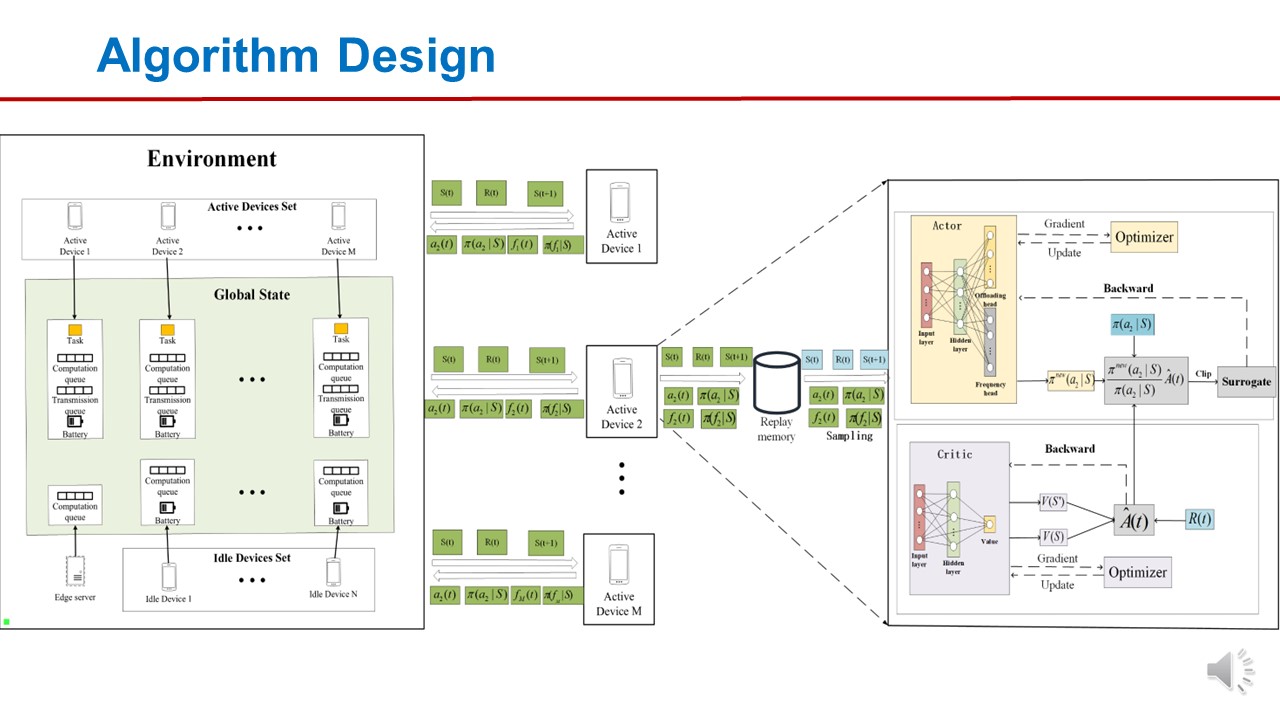
The figure shows the multi-agent reinforcement learning network architecture, and the local observation is integrated into the global observation through communication between devices, which is used as network input for calculation.
The device makes decisions based on the input, and saves the transition into the replay memory for the subsequent network update stage. When the network is updated, the transition is sampled randomly, the gradient is calculated according to the policy gradient formula, and it is back-propagated to the neural network for update.
|
 IEEE/ICACT20230243 Slide.18
[Big Slide]
[YouTube]