 |
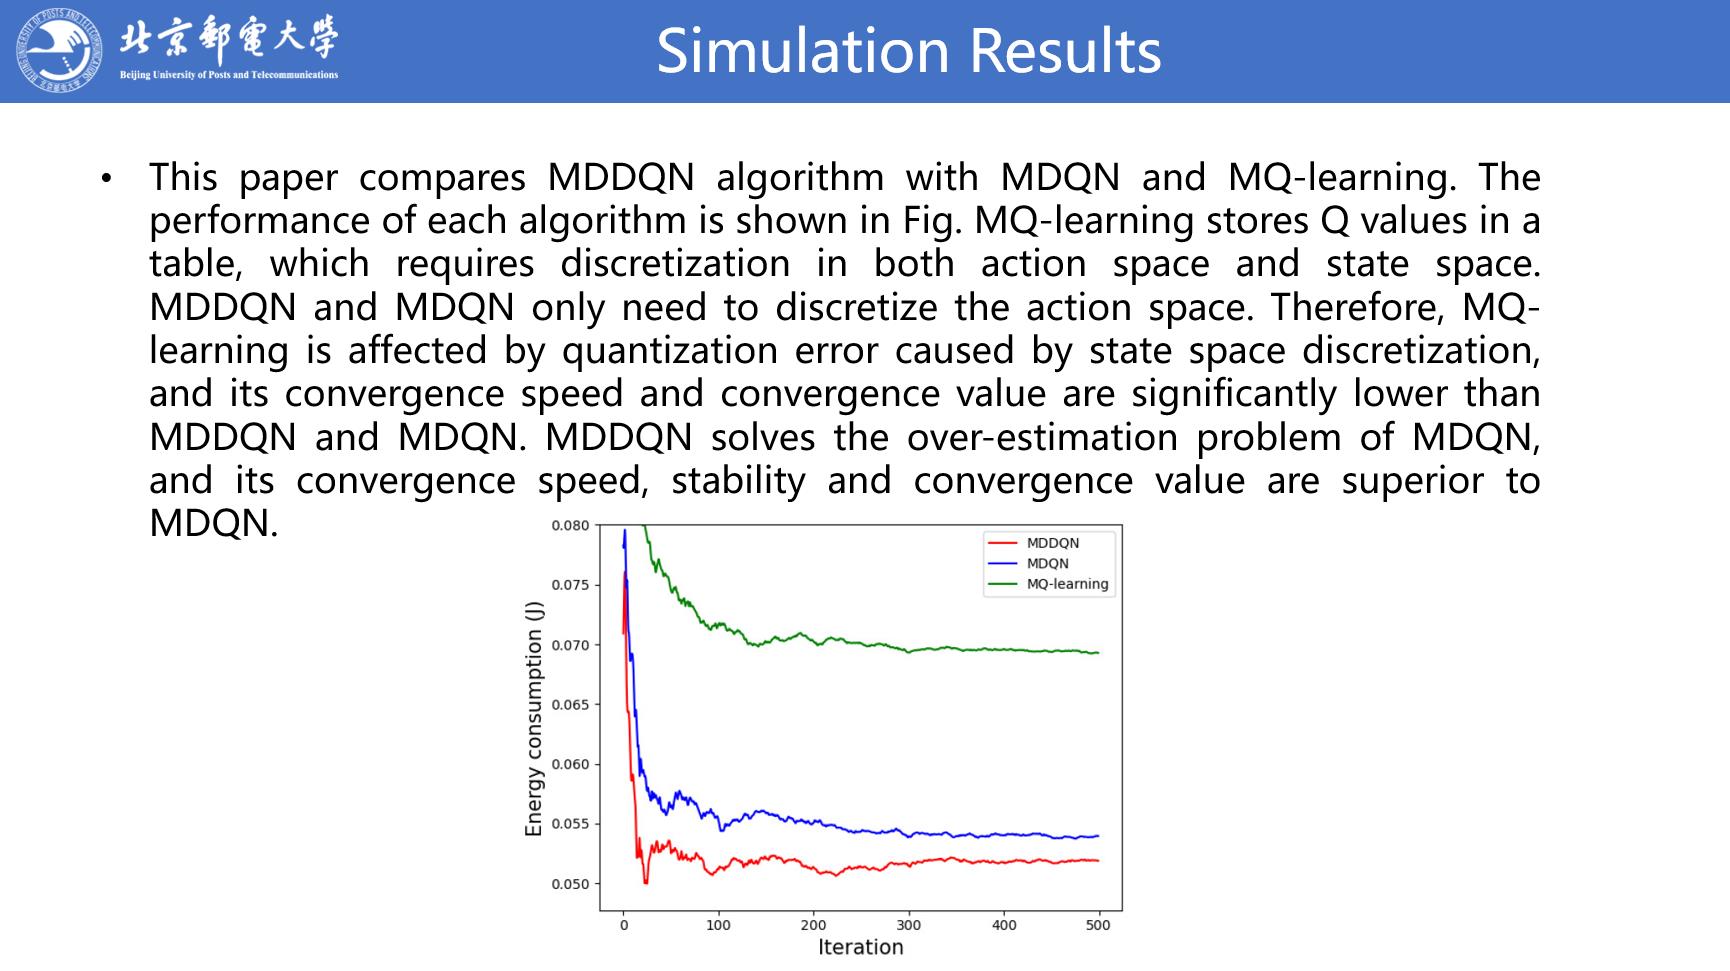
This paper compares MDDQN algorithm with MDQN and MQ-learning. The performance of each algorithm is shown in Fig. MQ-learning stores Q values in a table, which requires discretization in both action space and state space. MDDQN and MDQN only need to discretize the action space. Therefore, MQ-learning is affected by quantization error caused by state space discretization, and its convergence speed and convergence value are significantly lower than MDDQN and MDQN. MDDQN solves the over-estimation problem of MDQN, and its convergence speed, stability and convergence value are superior to MDQN.
|
 IEEE/ICACT20230164 Slide.19
[Big Slide]