 |
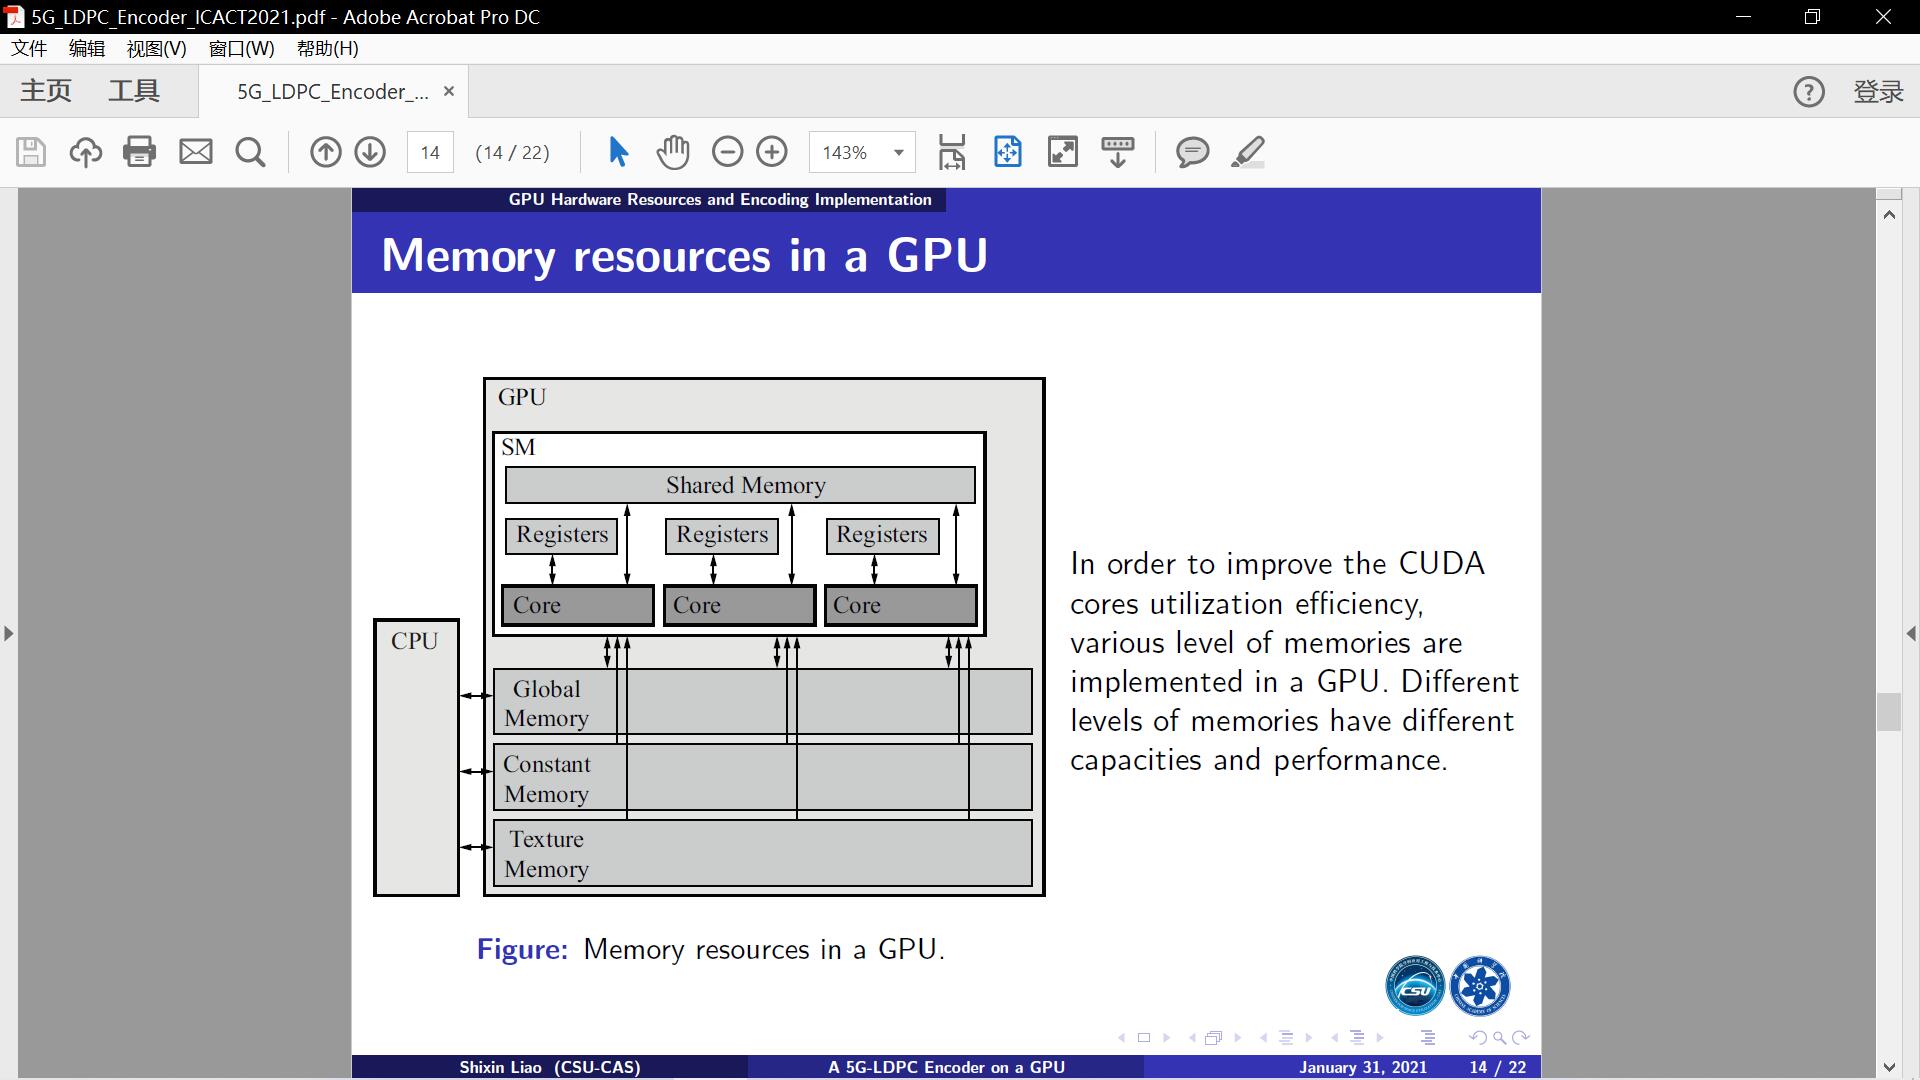
In order to improve the CUDA cores utilization efficiency, various level of memories are implemented in a GPU. Different levels of memories have different capacities and performance. The global memory has the largest capacity but the largest access latency compared to the constant and texture memories. Both constant and texture memories can be read and written by CPU but is read only for GPU. The second level of memories is the shared memory in an SM. All CUDA cores within an SM can access the shared memory simultaneously. Shared memory is faster than the global memory and slower than the constant memory. The third level of memories consists of warp-private registers. They can be accessed by all CUDA cores within a warp.
|
 IEEE/ICACT20210136 Slide.27
[Big Slide]