ICACT20210136 Slide.35
[Big slide for presentation] |
Chrome Text-to-Speach Click!! |
 |
That's the end of my presentation. Thank you! Welcome any comments or questions. My e-mail address: liaoshixin19@csu.ac.cn.
|
|
ICACT20210136 Slide.34
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
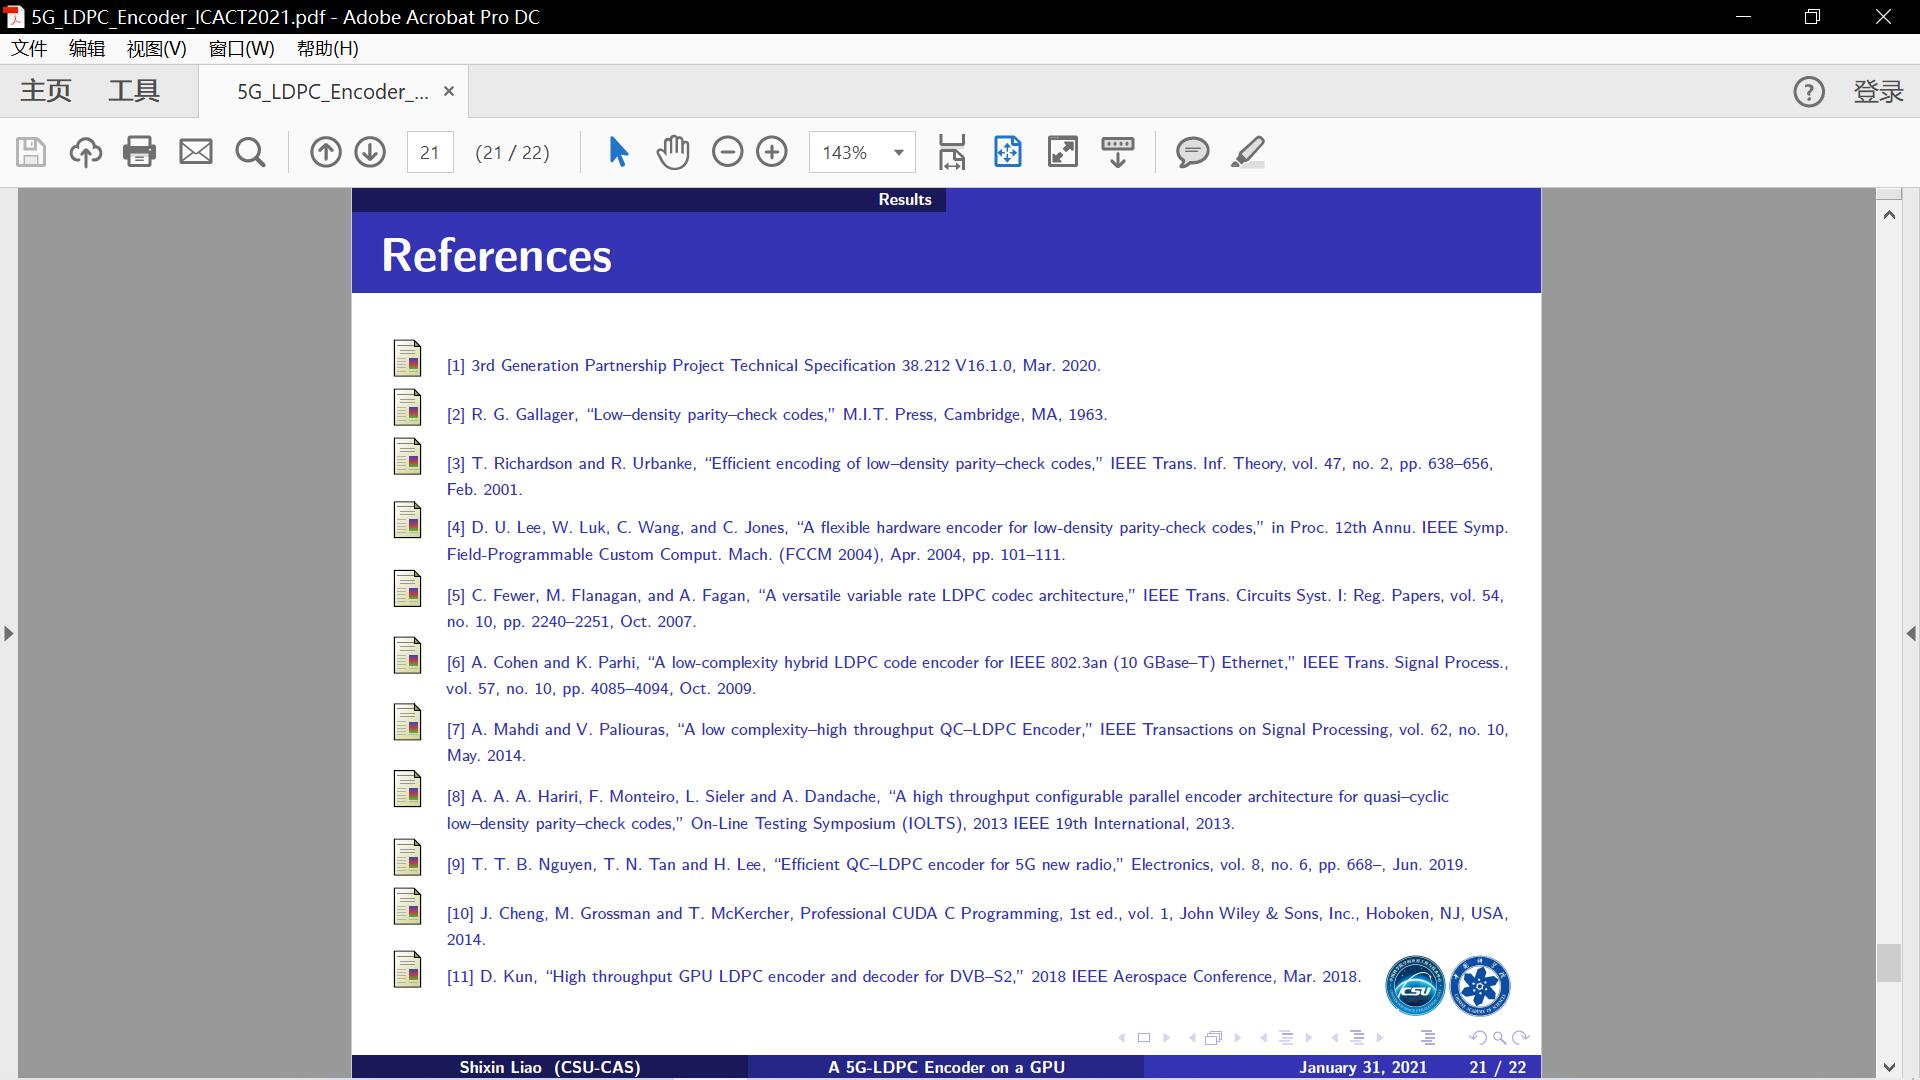 |
References.
|
|
ICACT20210136 Slide.33
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
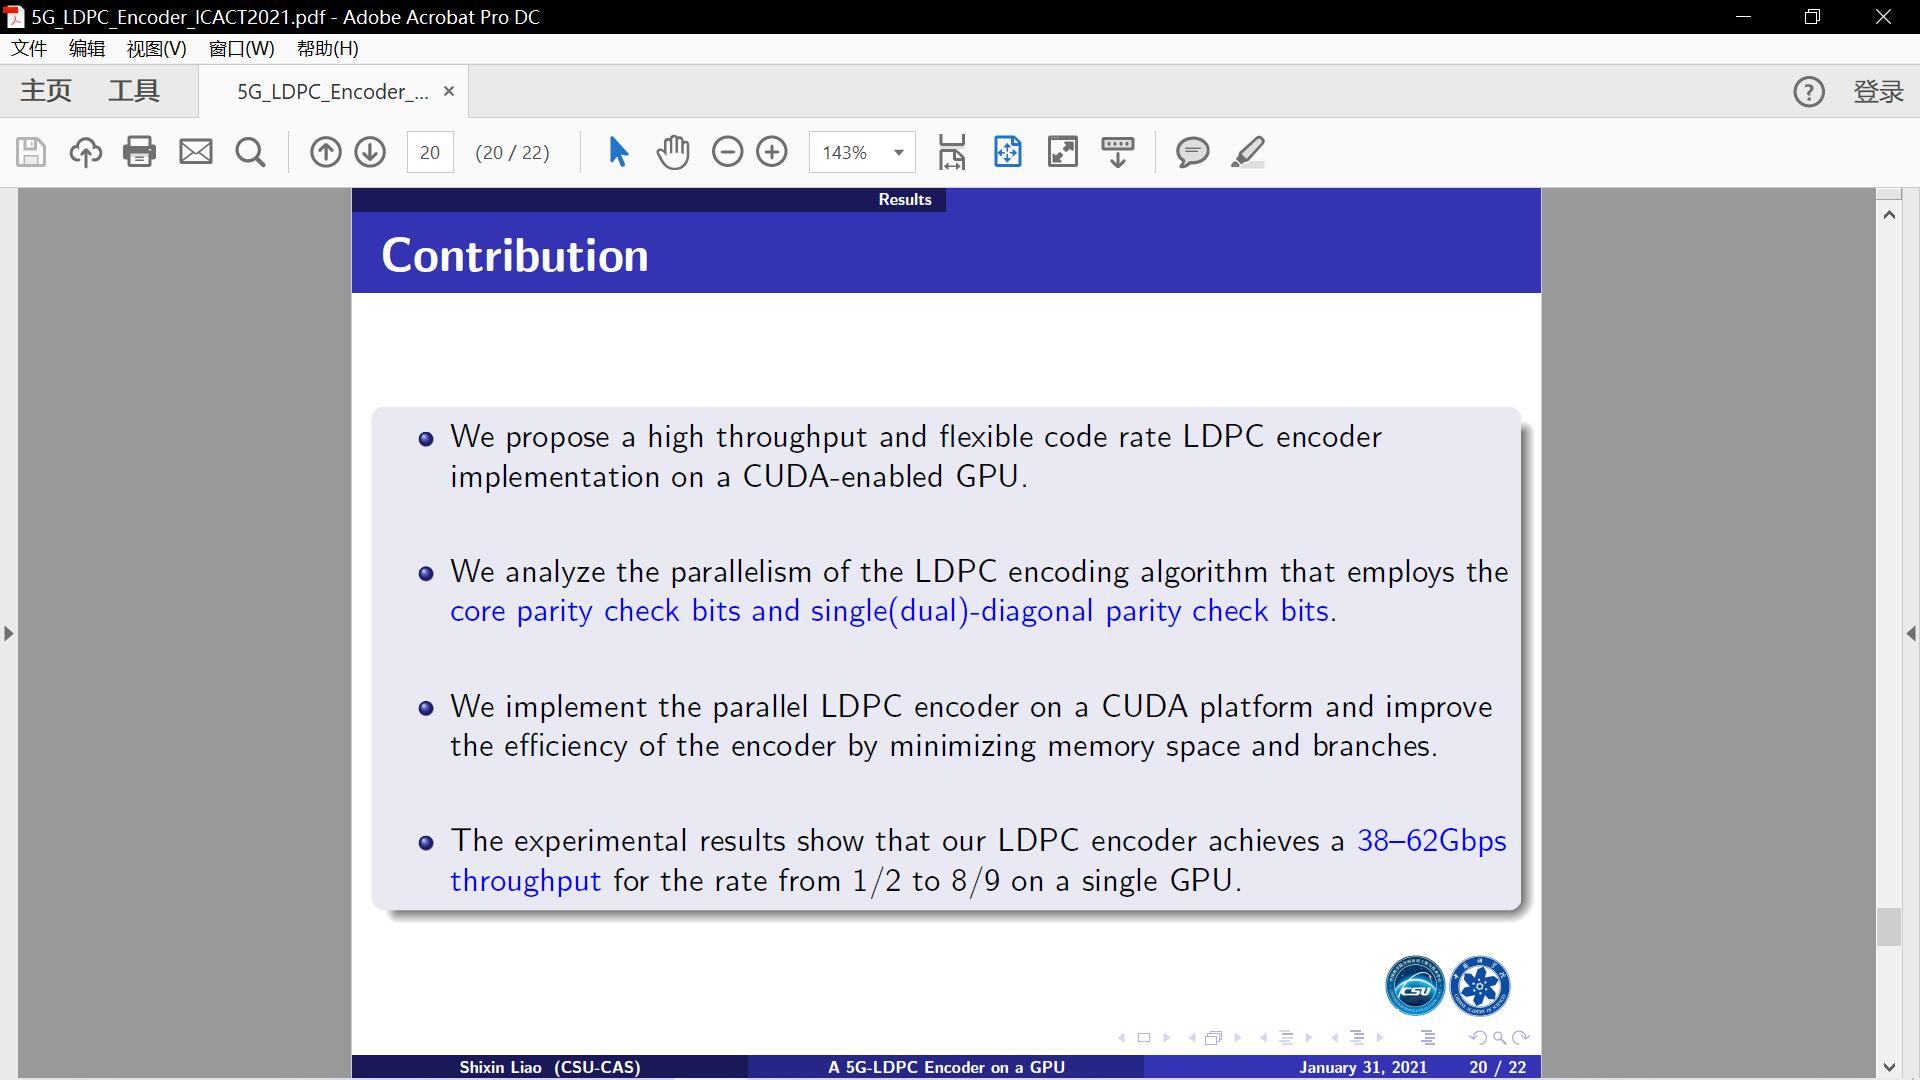 |
In conclusion, we propose a high throughput and flexible code rate LDPC encoder implementation on a CUDA-enabled GPU.
We analyze the parallelism of the LDPC encoding algorithm that employs the core parity check bits and single(dual)-diagonal parity check bits. We implement the parallel LDPC encoder on a CUDA platform and improve the efficiency of the encoder by minimizing memory space and branches. The experimental results show that our LDPC encoder achieves a 38-62Gbps throughput for the rate from 1/2 to 8/9 on a single GPU.
|
|
ICACT20210136 Slide.32
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
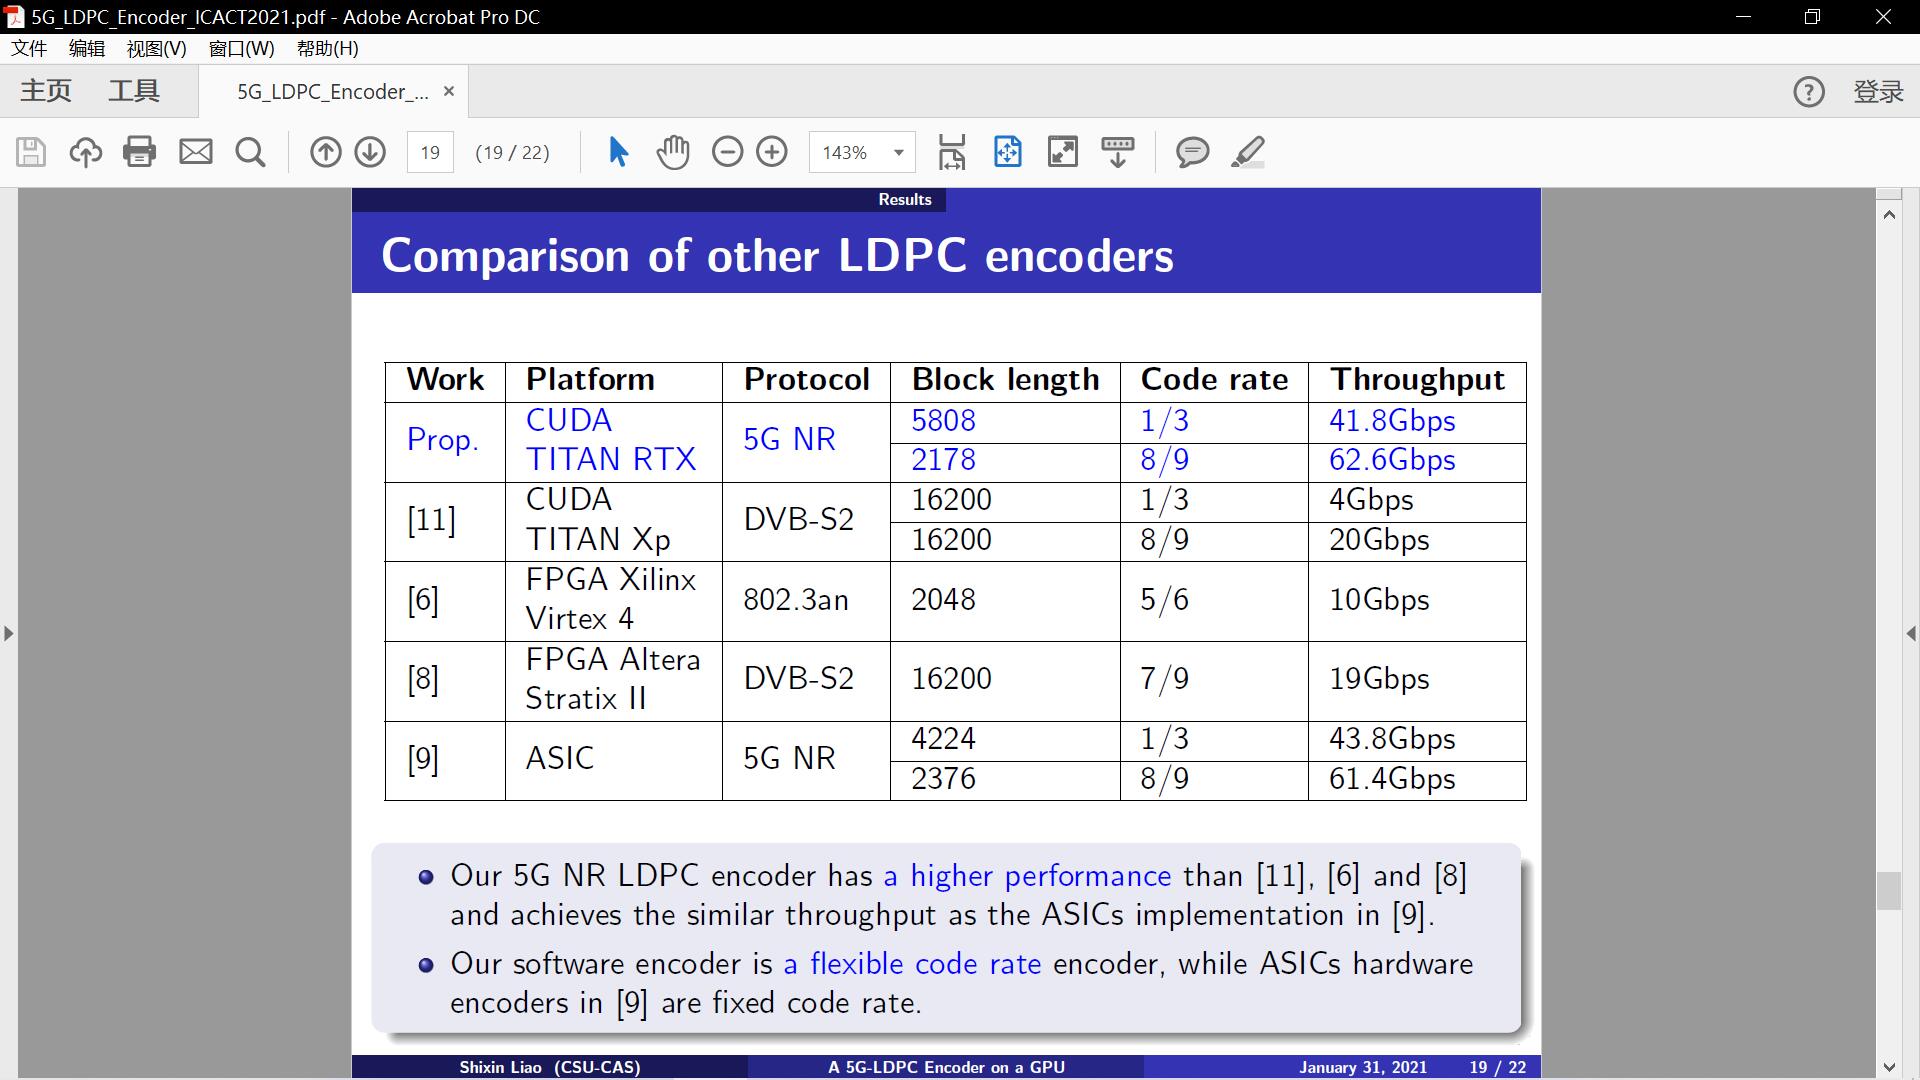 |
This table compares the performances of our implementation with other implementations. It can be seen from Table II that compared with the implementation on FPGAs and CUDAs, our implementation of the 5G NR LDPC encoder has a higher performance and achieves the similar throughput as the expensive hardware implementation in [9]. Moreover, our software encoder is a flexible code rate encoder, while ASICs hardware encoders are fixed code rate. As a result, our proposed implementation achieves a high performance and flexibility of the LDPC encoding at a reasonable cost.
|
|
ICACT20210136 Slide.31
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
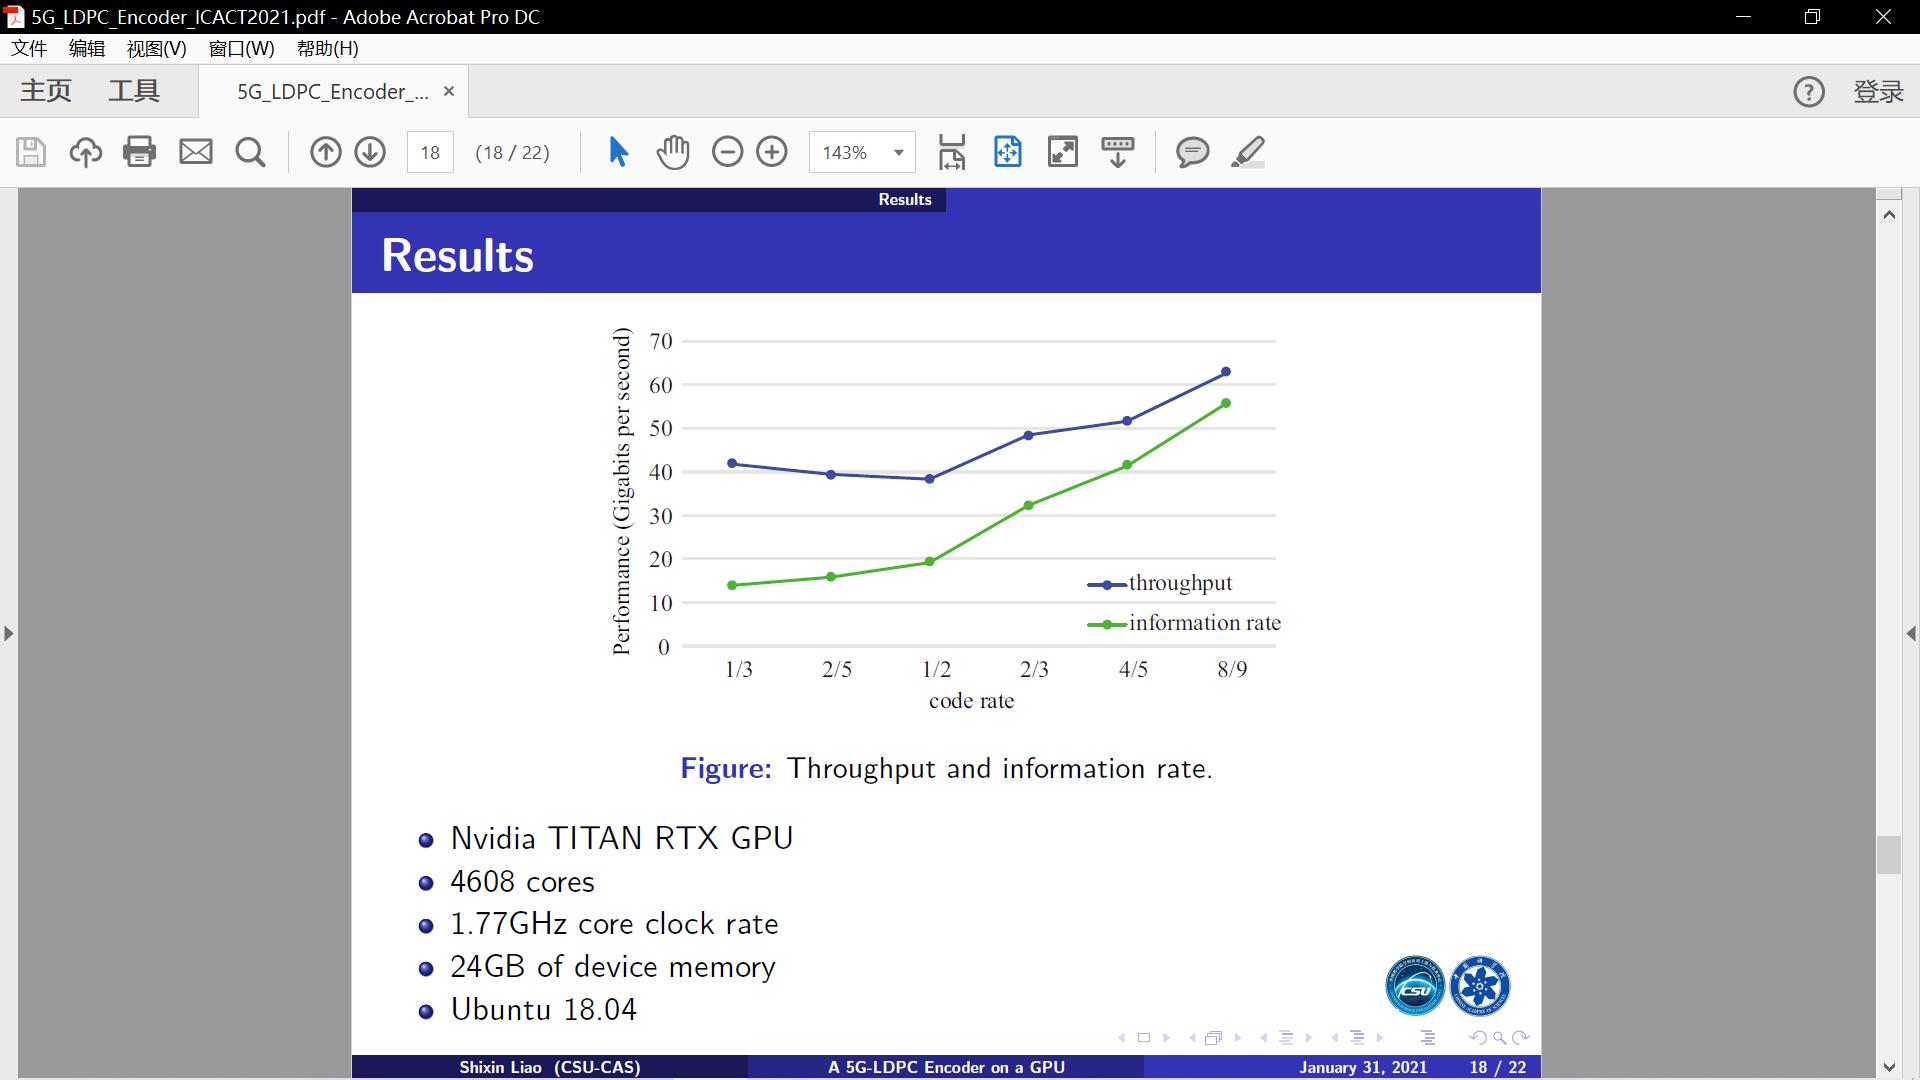 |
We implemented the parallel LDPC encoding algorithm on a Nvidia TITAN RTX GPU with 4608 cores, 1.77GHz core clock rate and 24GB of device memory. Our program is built on top of an Ubuntu 18.04 Linux OS with Nvidia CUDA driver 440.33 and CUDA toolkit release 10.2.
In our experiments, Z is set to 88, K is set to 1936 and the code rate is range from 1/3 to 8/9. We choose BG1 as the base graph to construct the parity check matrix H so that blockSize of calcPc function from 42 to 0 corresponds to the code rate from 1/3 to 8/9.
The throughput of the encoder is defined as the number of codeword bits that the encoder can process within the duration of the kernel functions. The information rate is defined as the number of information bits that the encoder can process within the same time. Thie figure shows the Gigabits per second throughput and information rate of our proposed implementation with K = 1936.
|
|
ICACT20210136 Slide.30
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
 |
Results.
|
|
ICACT20210136 Slide.29
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
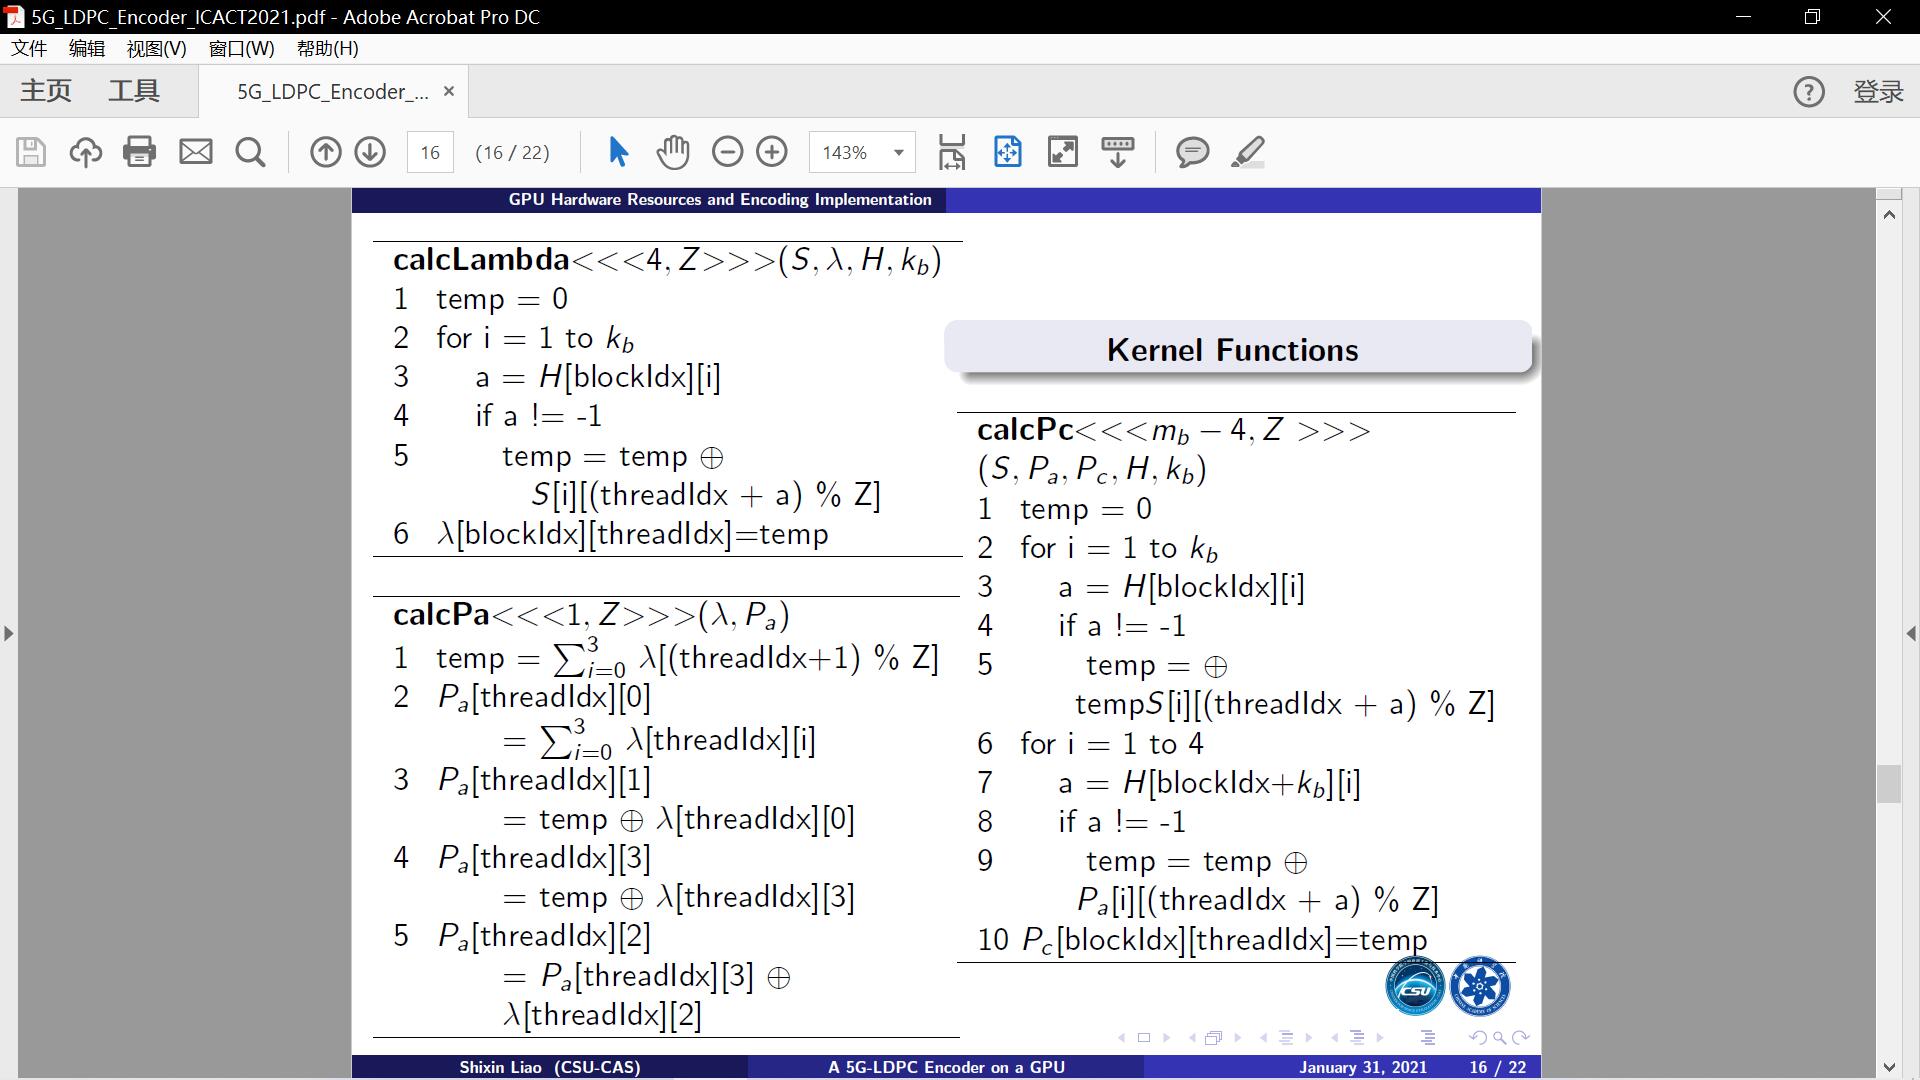 |
We use “<<>>” to indicate that gridSize blockSize threads are launched in the following pseudocode. Inside the kernel function, the index of each thread is (blockIdx; threadIdx). To improve the readability of the pseudocode, we use two–dimensional arrays to locate bits in vectors H, S, lambda, Pa and Pc.
|
|
ICACT20210136 Slide.28
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
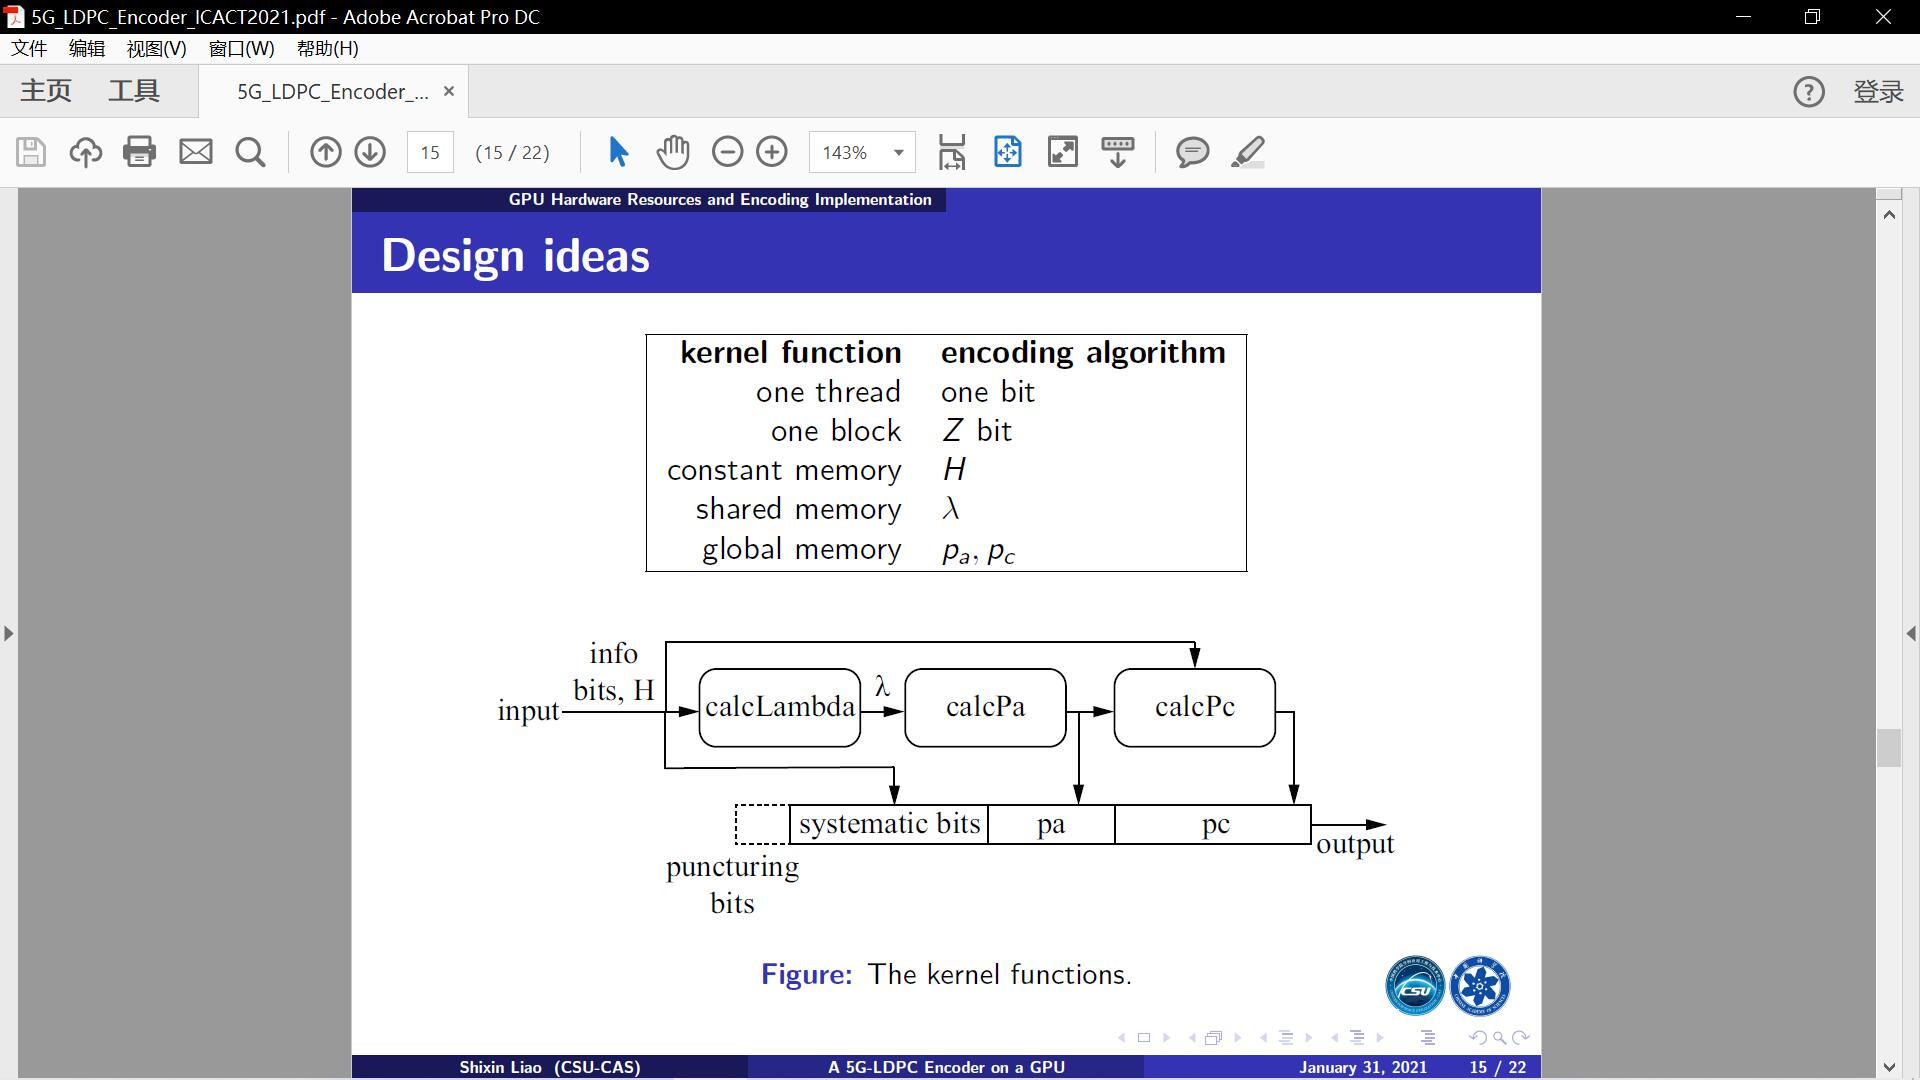 |
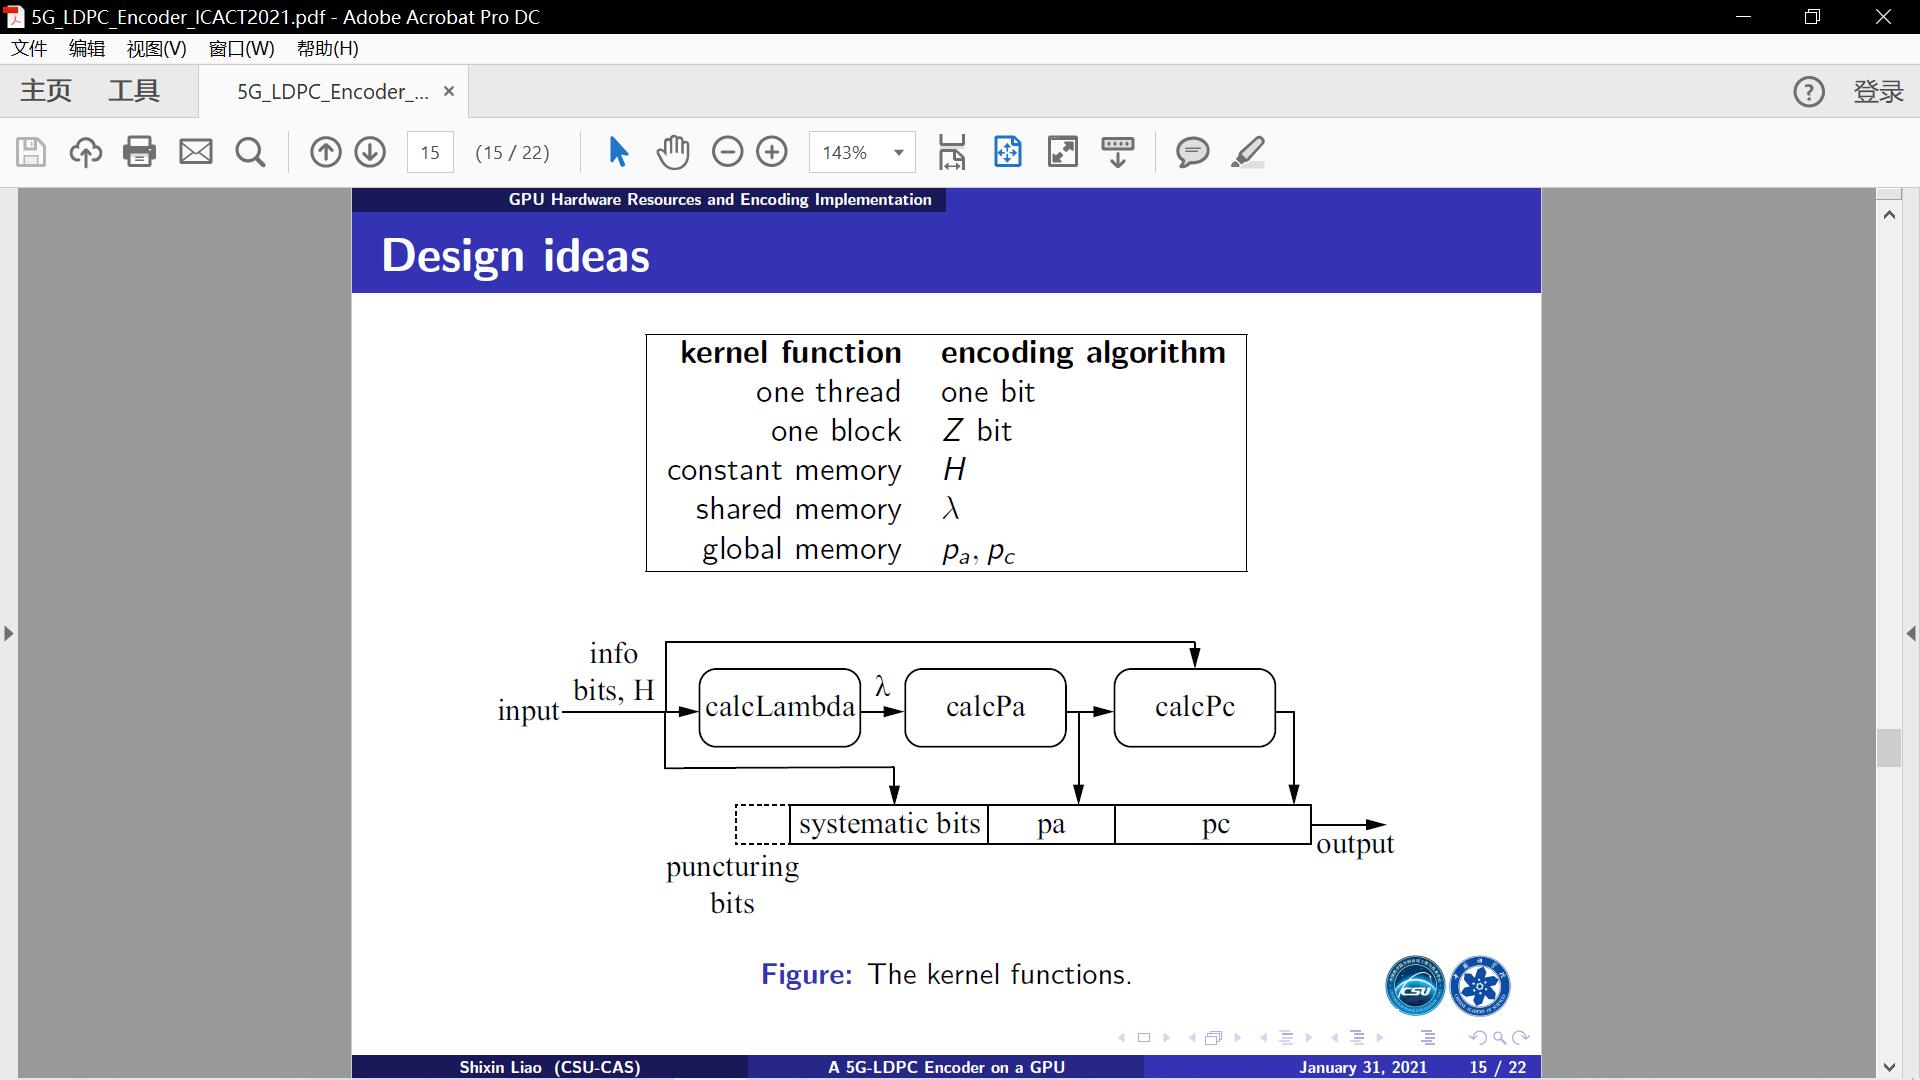
In our implementation, we assign one thread for each parity bit. The procedure is shown as the figure. In this procedure, the encoding step is executed on the GPU cores by calling kernel functions. We call three kernel functions, calcLambda, calcPa and calcPc, to calculate parity bits.
|
|
ICACT20210136 Slide.27
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
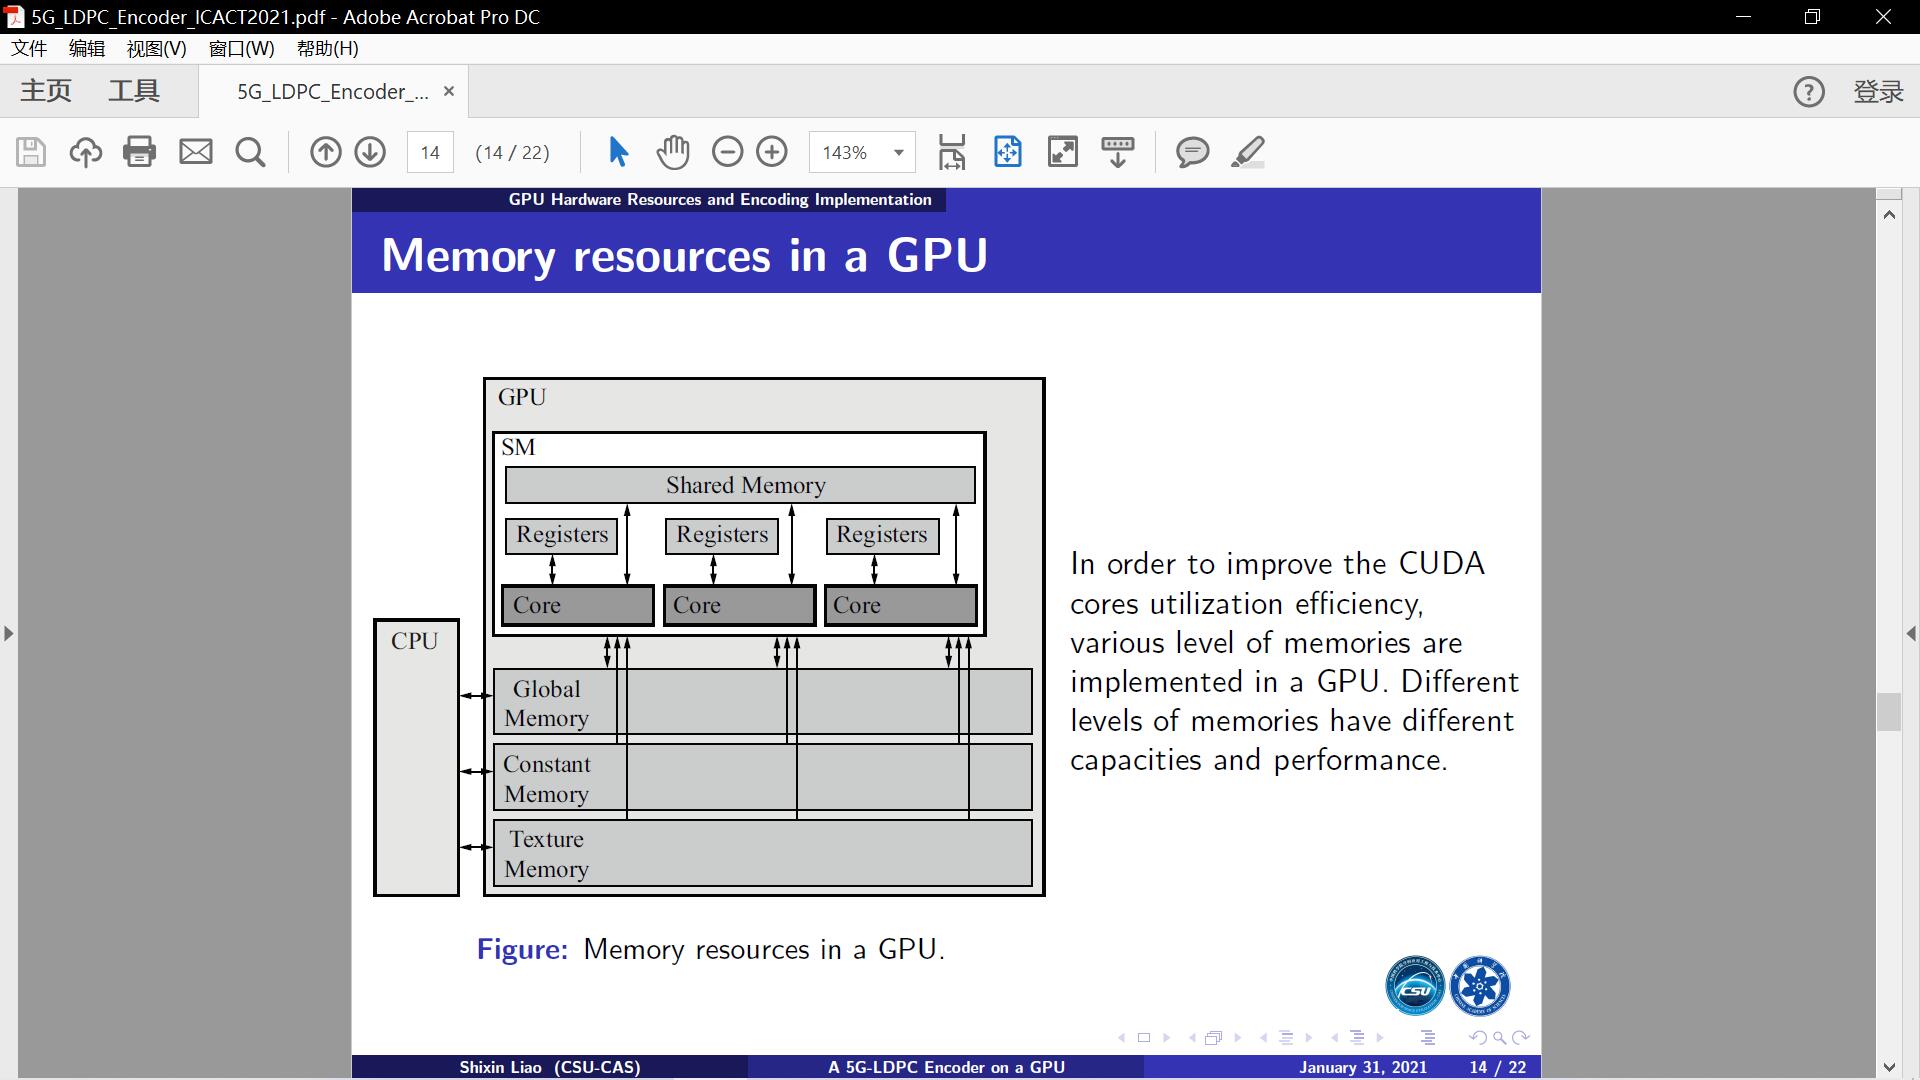 |
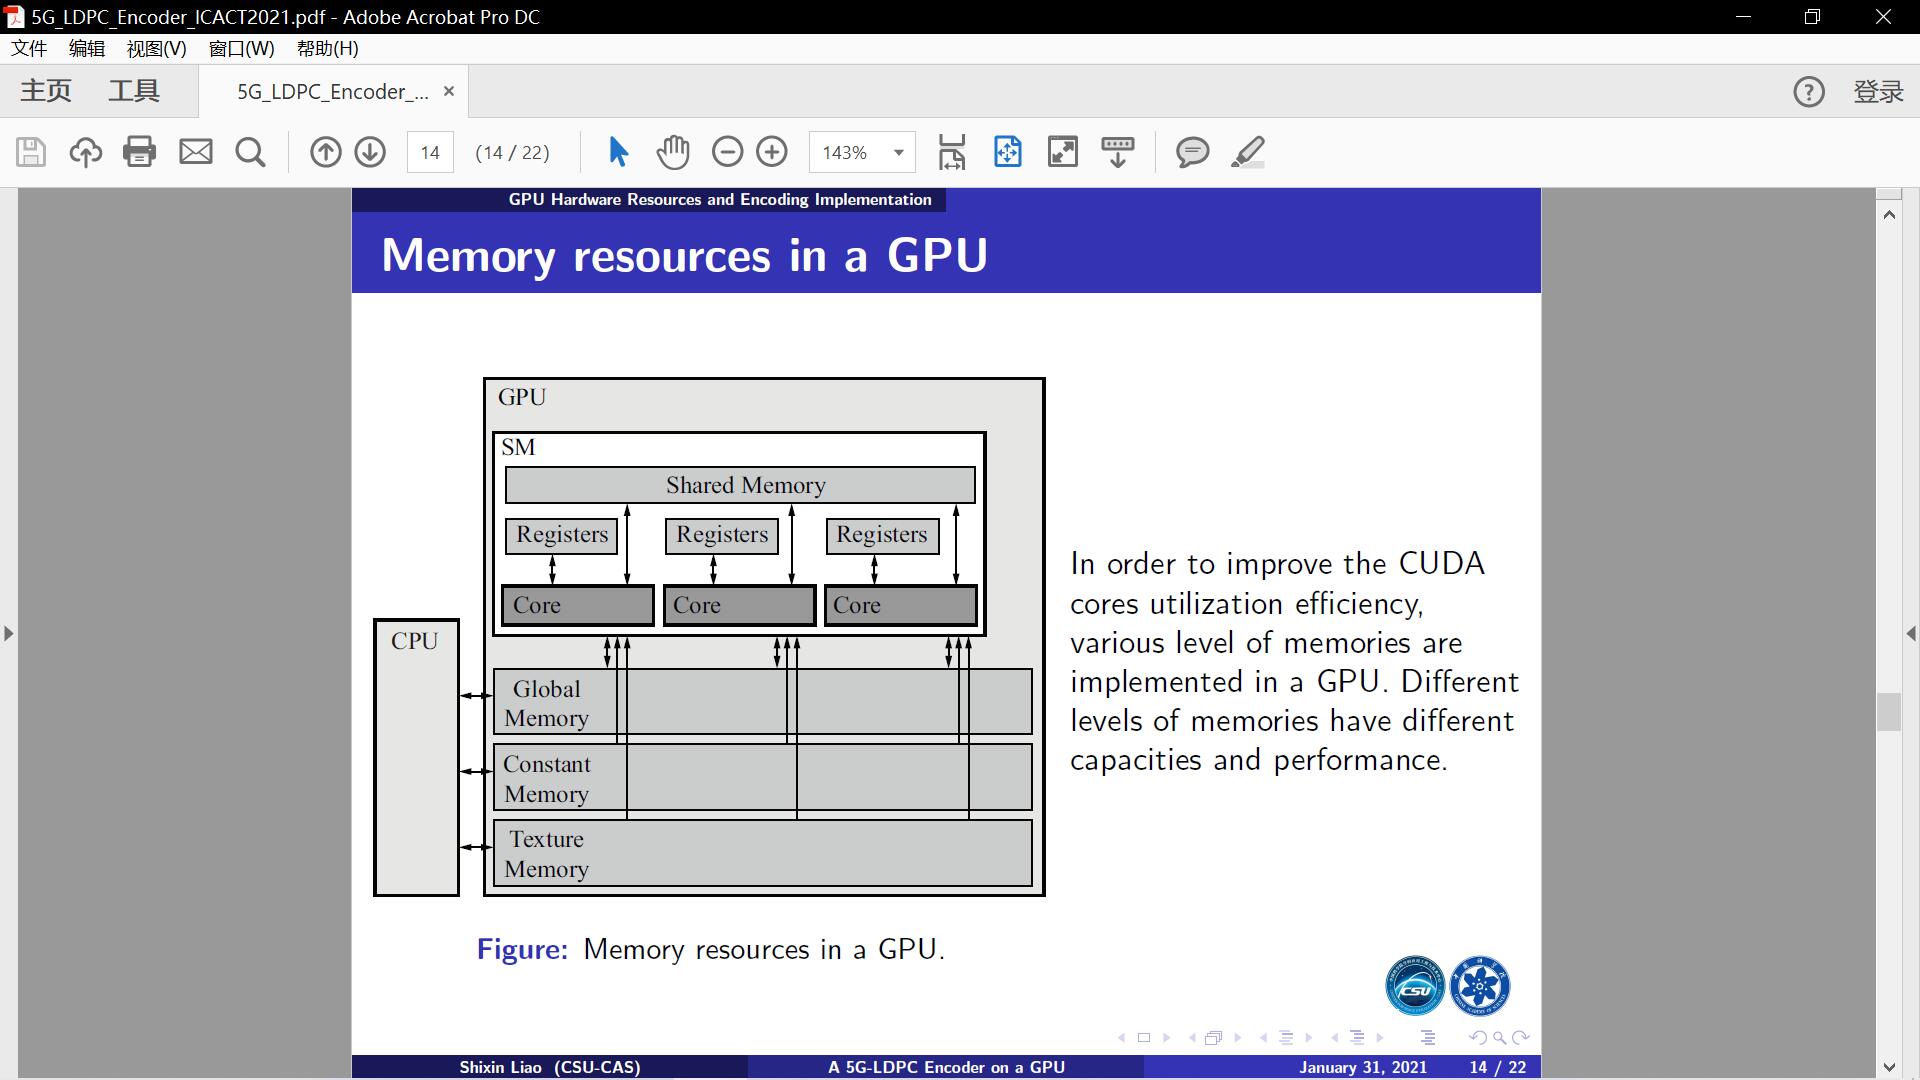
In order to improve the CUDA cores utilization efficiency, various level of memories are implemented in a GPU. Different levels of memories have different capacities and performance. The global memory has the largest capacity but the largest access latency compared to the constant and texture memories. Both constant and texture memories can be read and written by CPU but is read only for GPU. The second level of memories is the shared memory in an SM. All CUDA cores within an SM can access the shared memory simultaneously. Shared memory is faster than the global memory and slower than the constant memory. The third level of memories consists of warp-private registers. They can be accessed by all CUDA cores within a warp.
|
|
ICACT20210136 Slide.26
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
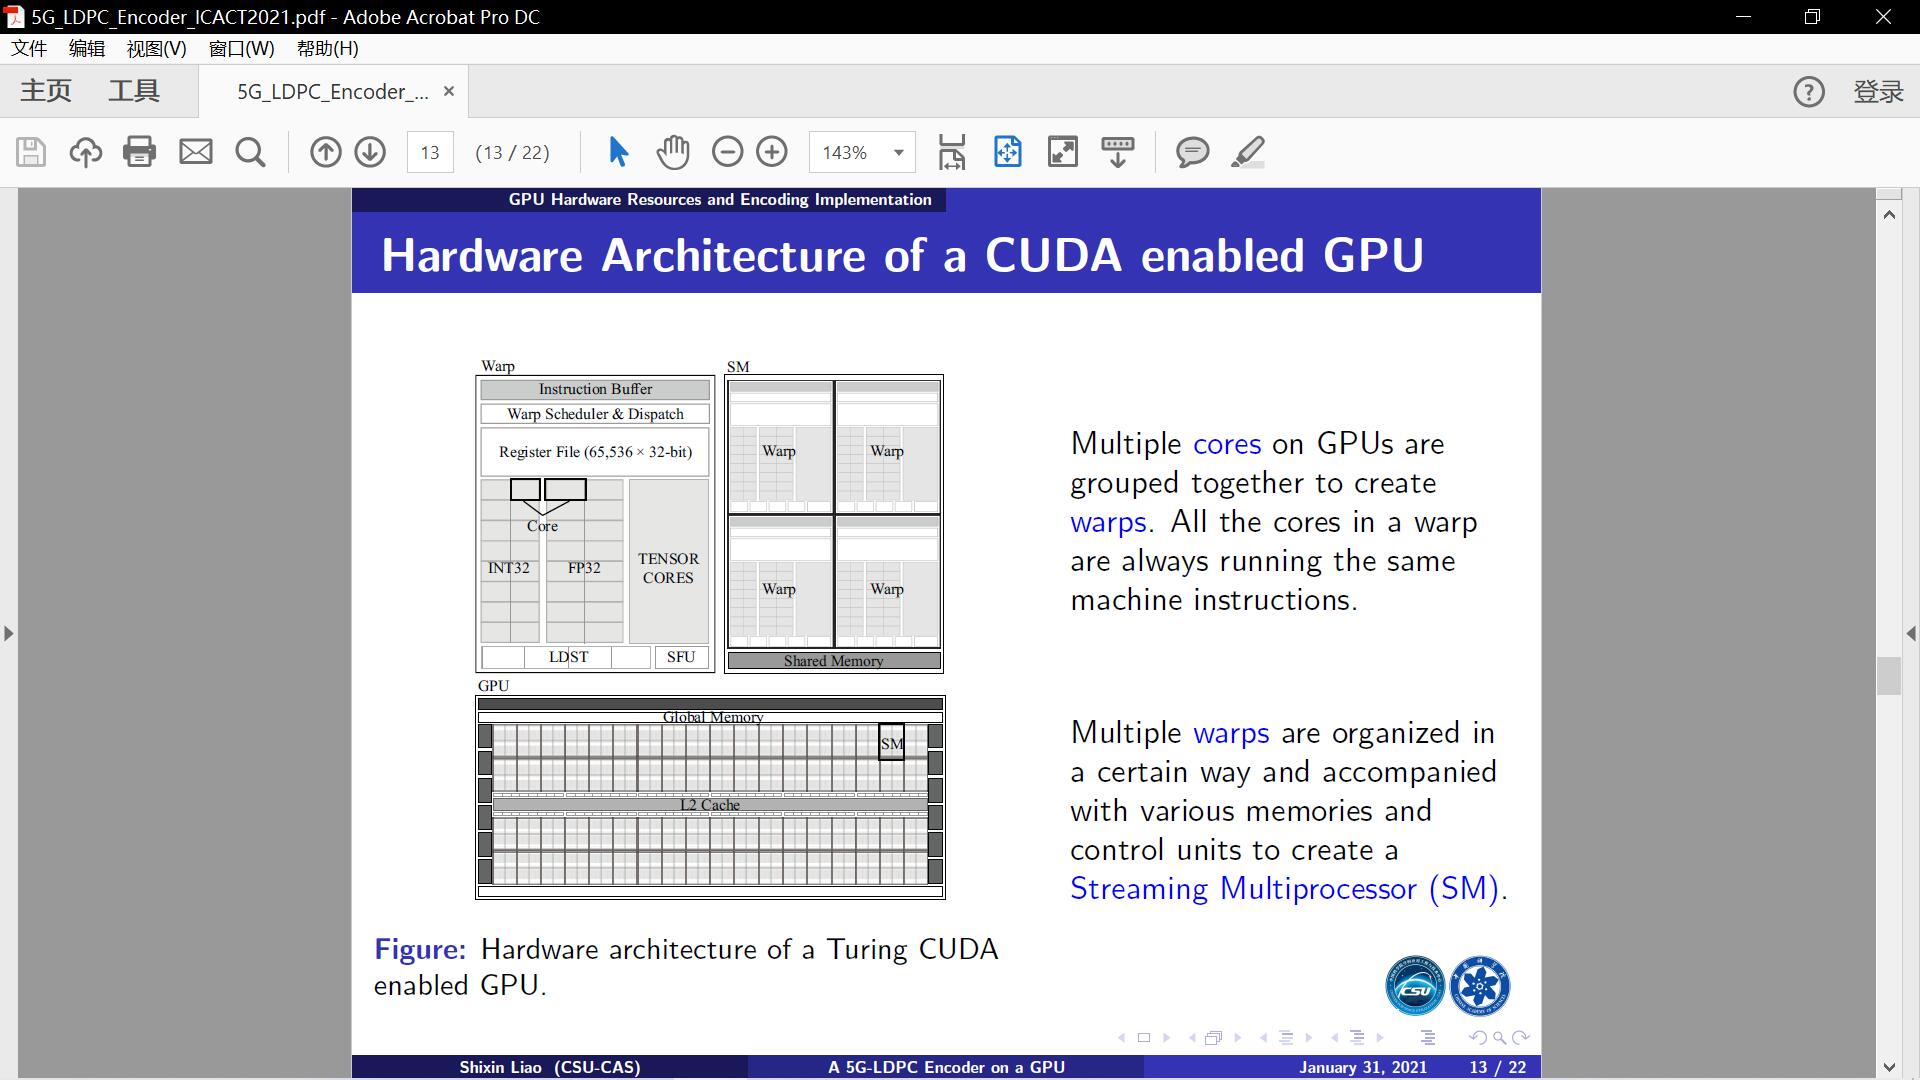 |
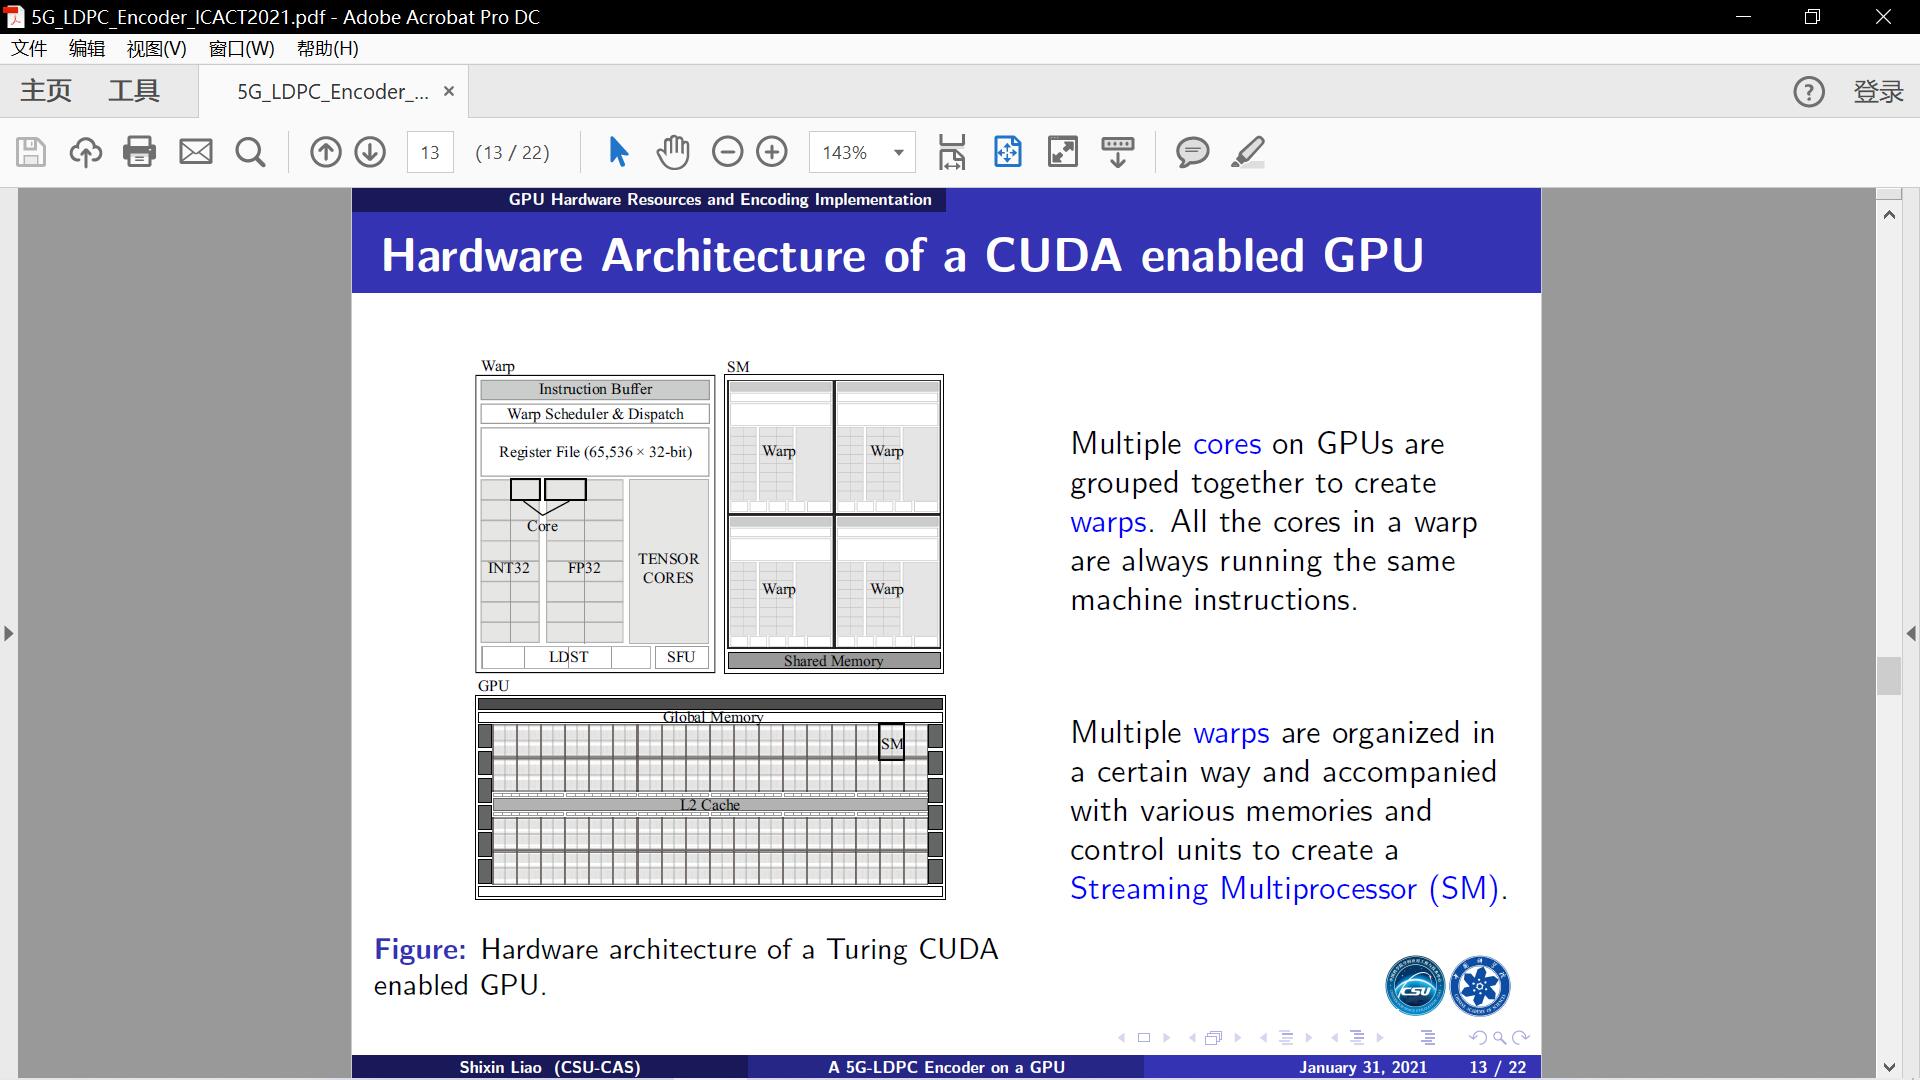
The basic computation resources on a CUDA enabled GPU are called CUDA cores, each of which can execute one integer or floating-point instruction per clock cycle. 32 CUDA cores are put together and accompanied with various memories and control units to generate a warp, which can execute the same instruction simultaneously. Multiple warps are organized in a certain way and accompanied with various memories and control units to create a Streaming Multiprocessor (SM). Usually, a GPU consists of multiple SMs and therefore hundreds or thousands of CUDA cores. In every clock cycle, all the CUDA cores can execute instructions in parallel. This is the foundation that highly parallel computing can be conducted on a GPU.
|
|
ICACT20210136 Slide.25
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
 |
GPU Hardware Resources and Encoding Implementation.
|
|
ICACT20210136 Slide.24
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
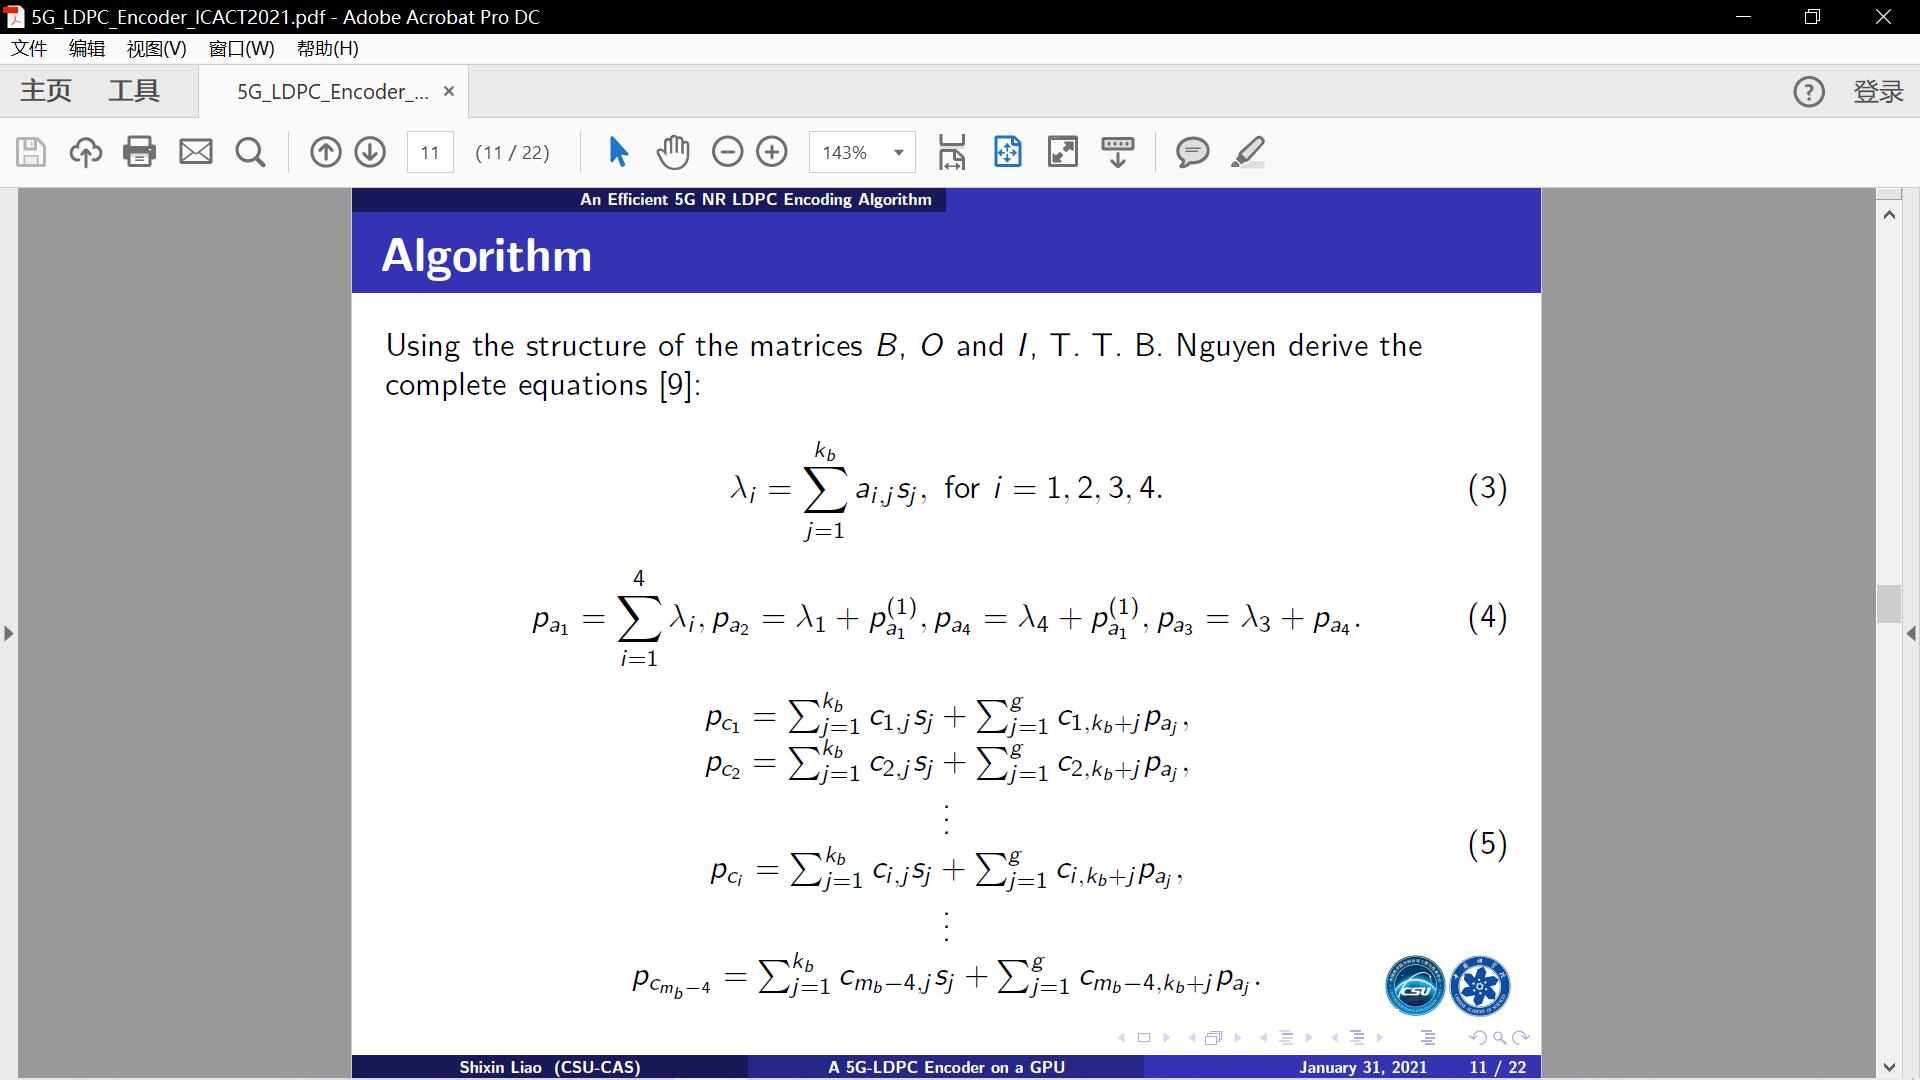 |
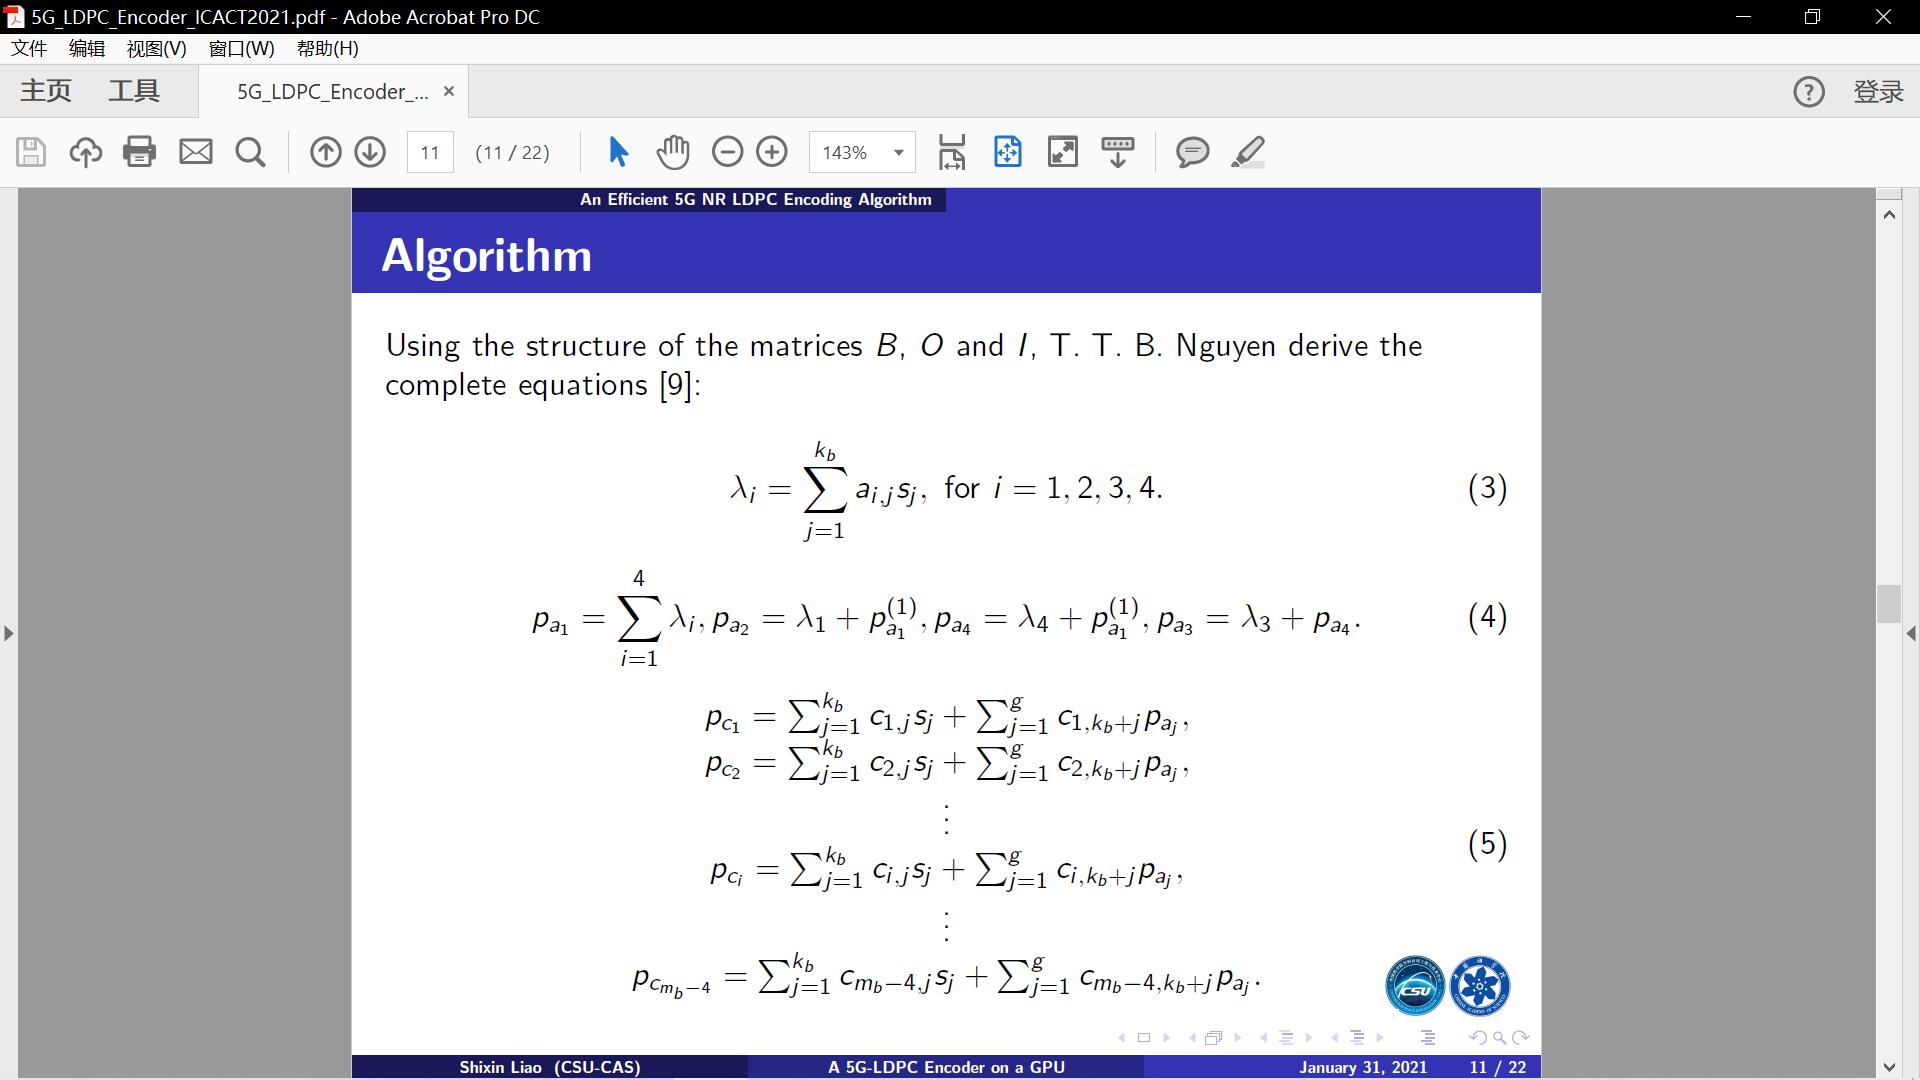
Using the structure of the matrices B, O and I , T. T. B. Nguyen derive the complete equations. It can be seen that lambda can be calculated first, then p_a and p_c can be calculated. Note that all the bits in p_c can be calculated in parallel.
|
|
ICACT20210136 Slide.23
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
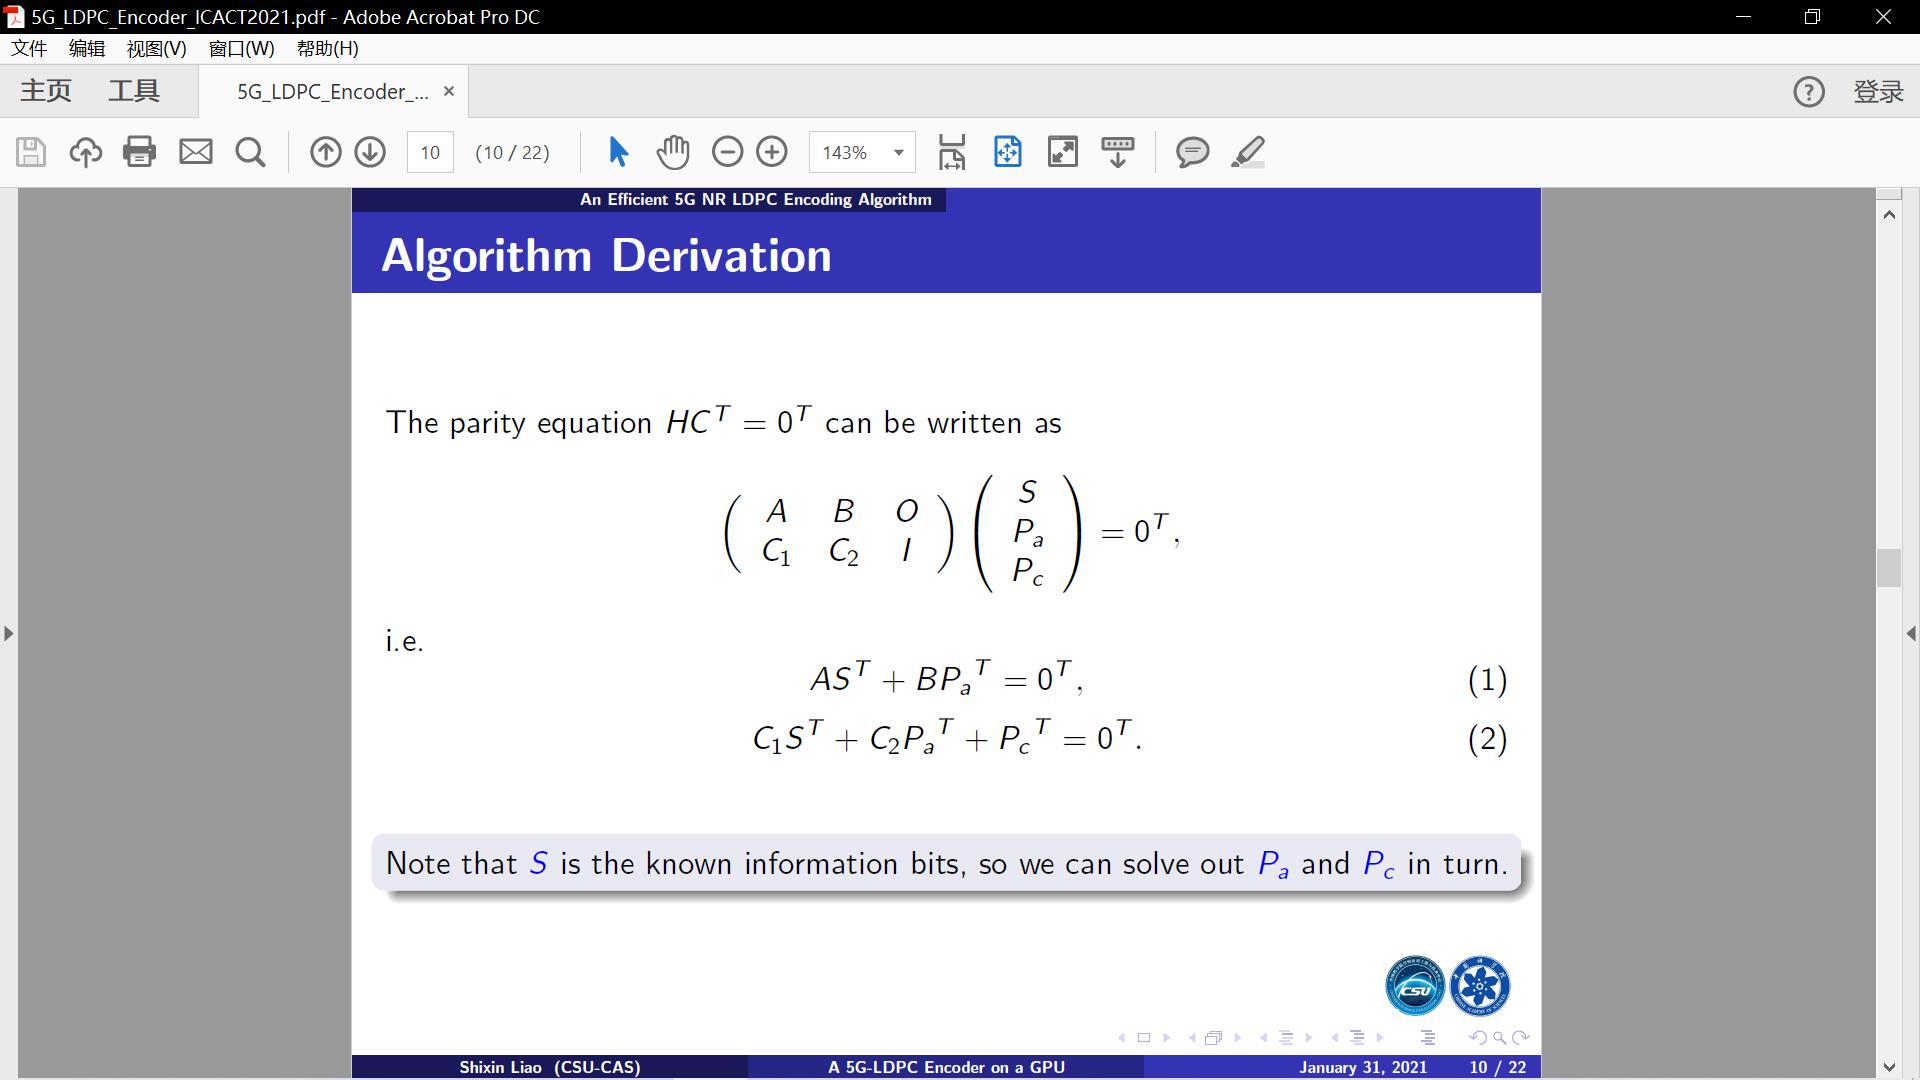 |
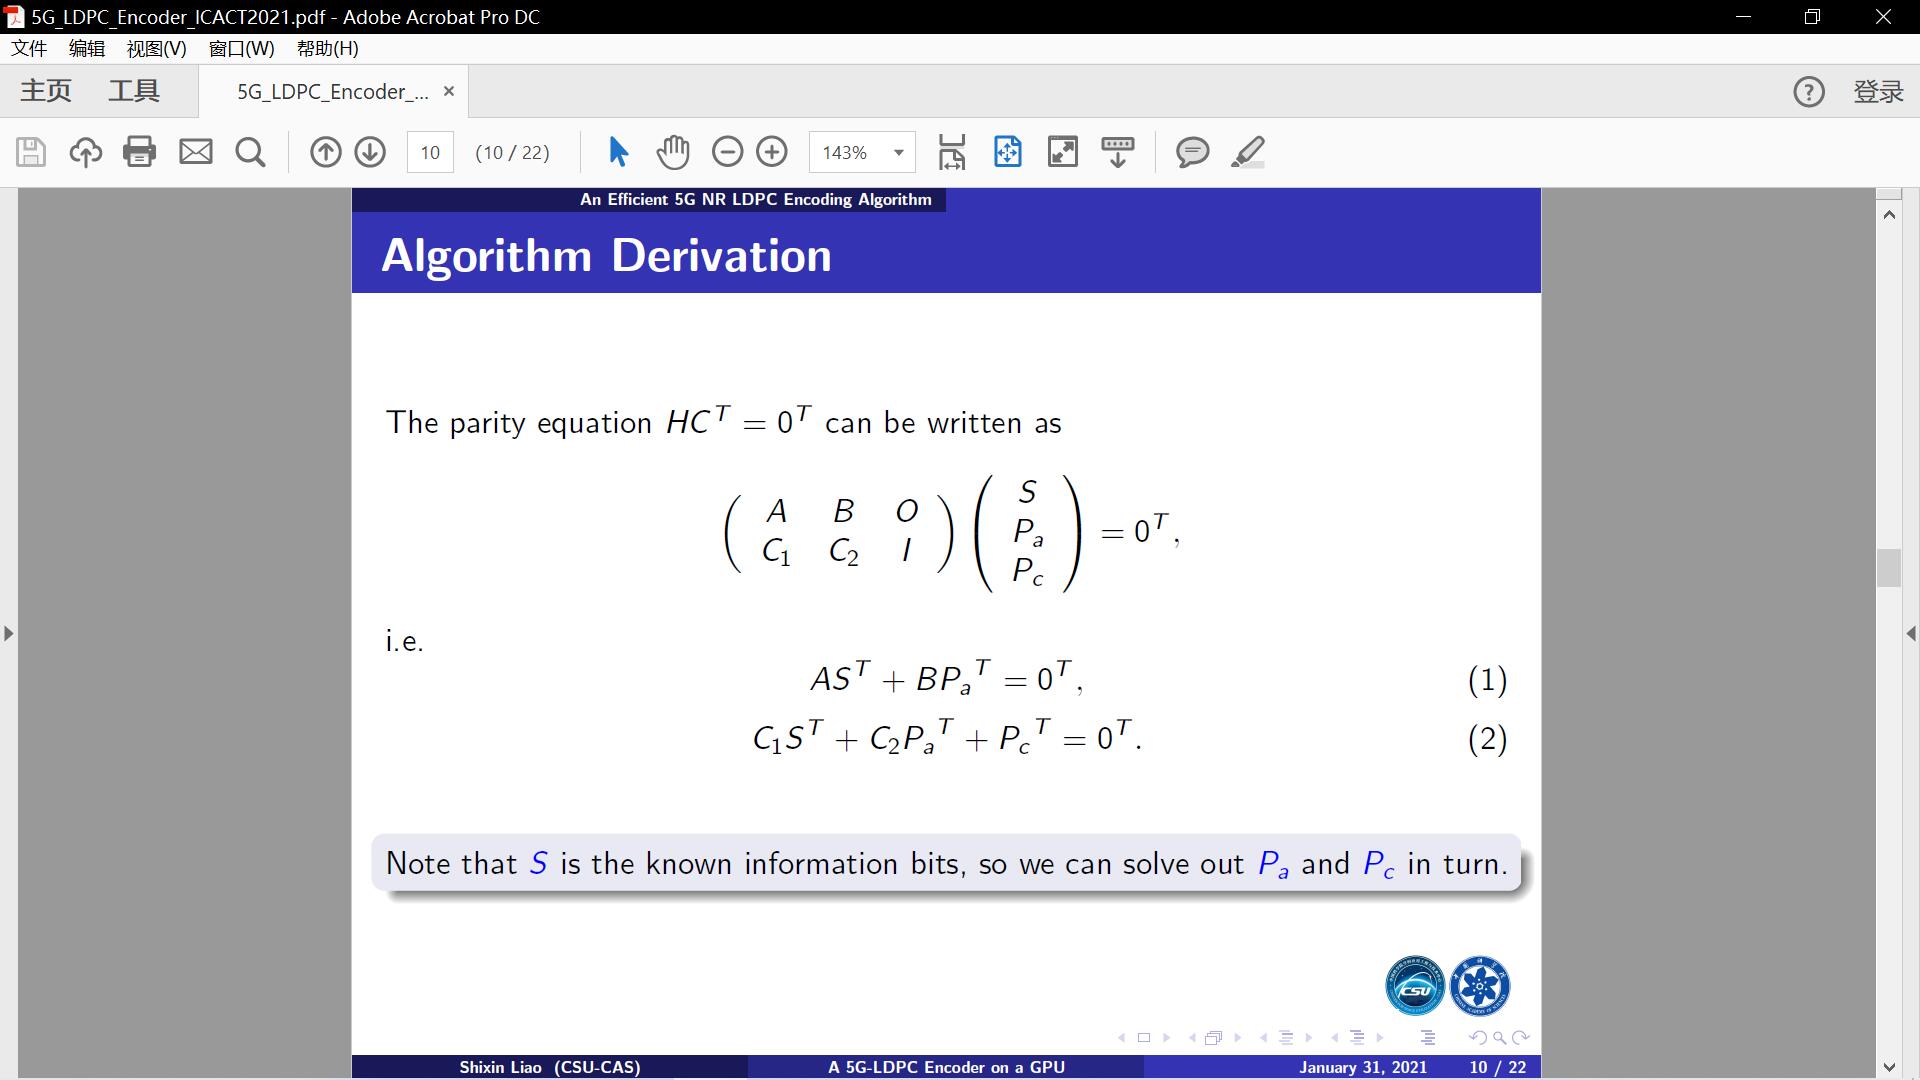
To match the three columns of H, divide the vector C into three parts.
|
|
ICACT20210136 Slide.22
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
 |
An Efficient 5G NR LDPC Encoding Algorithm.
|
|
ICACT20210136 Slide.21
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
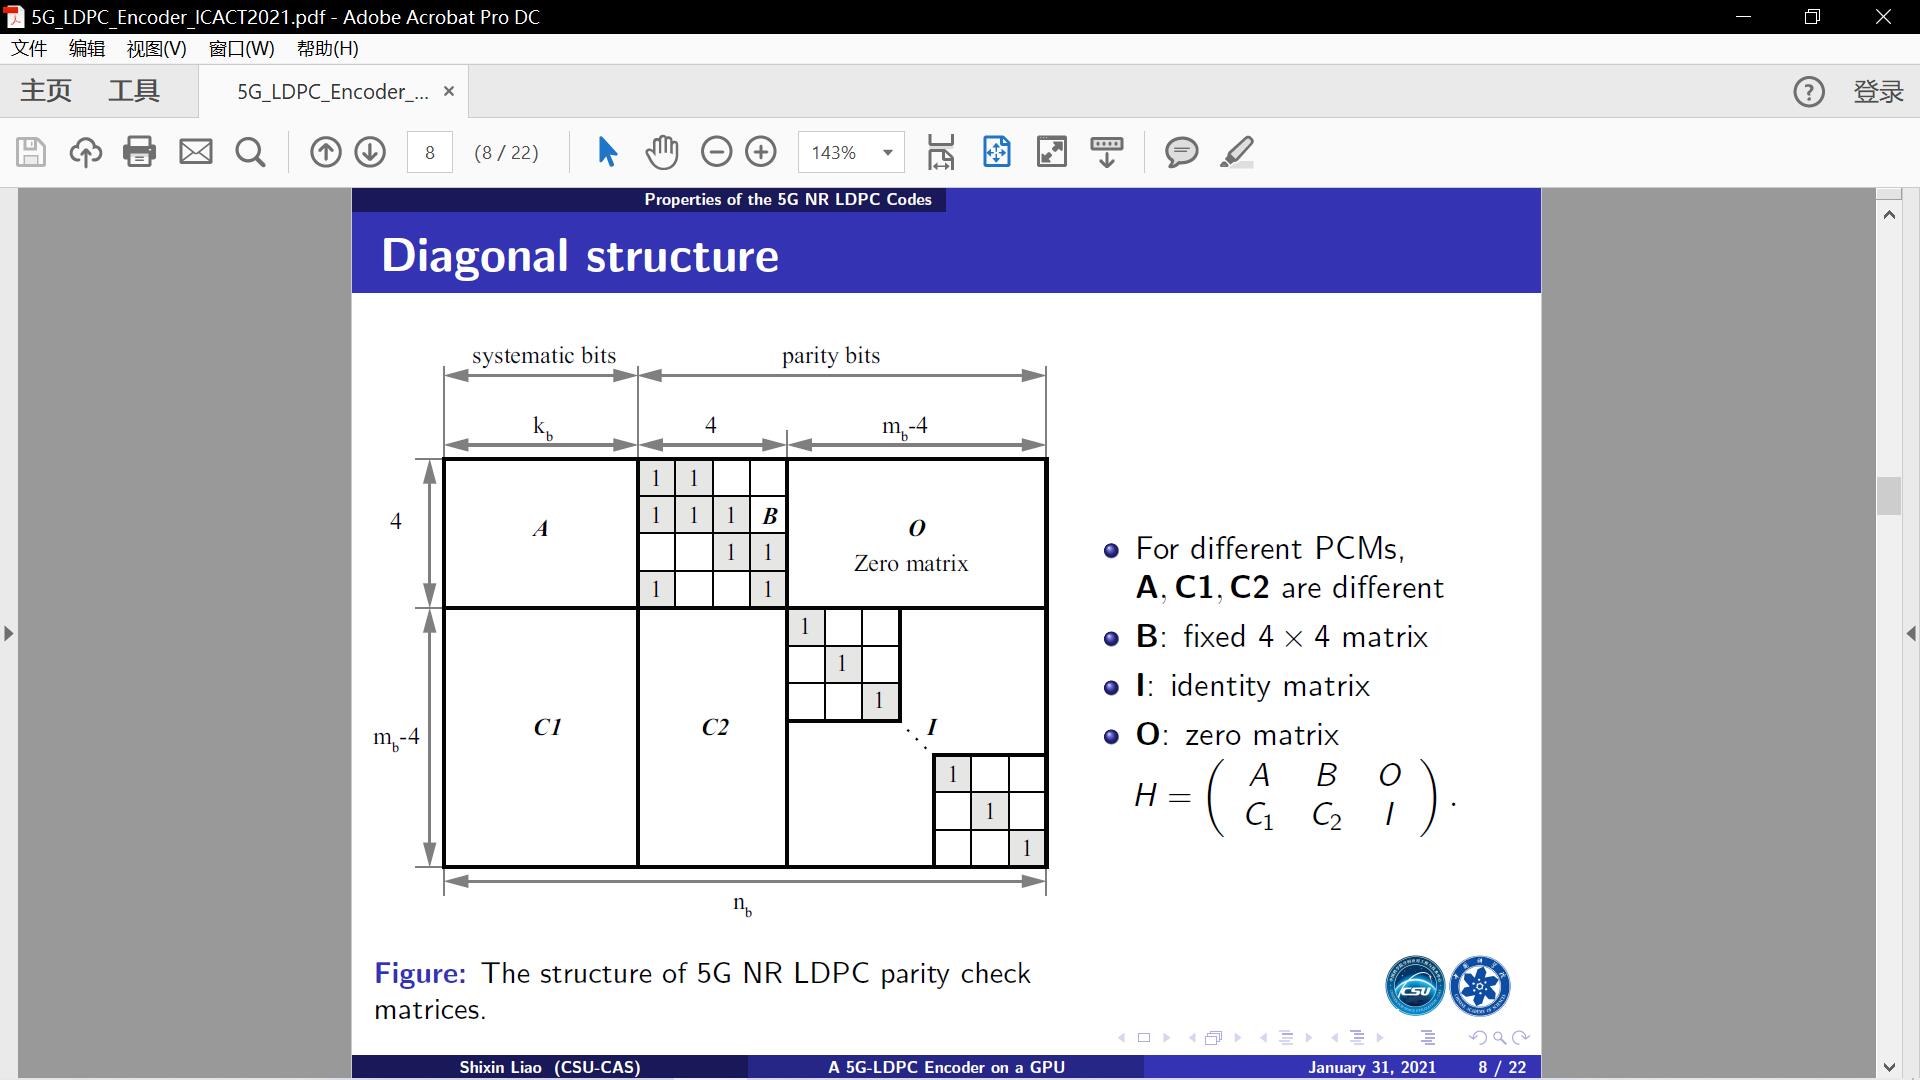 |
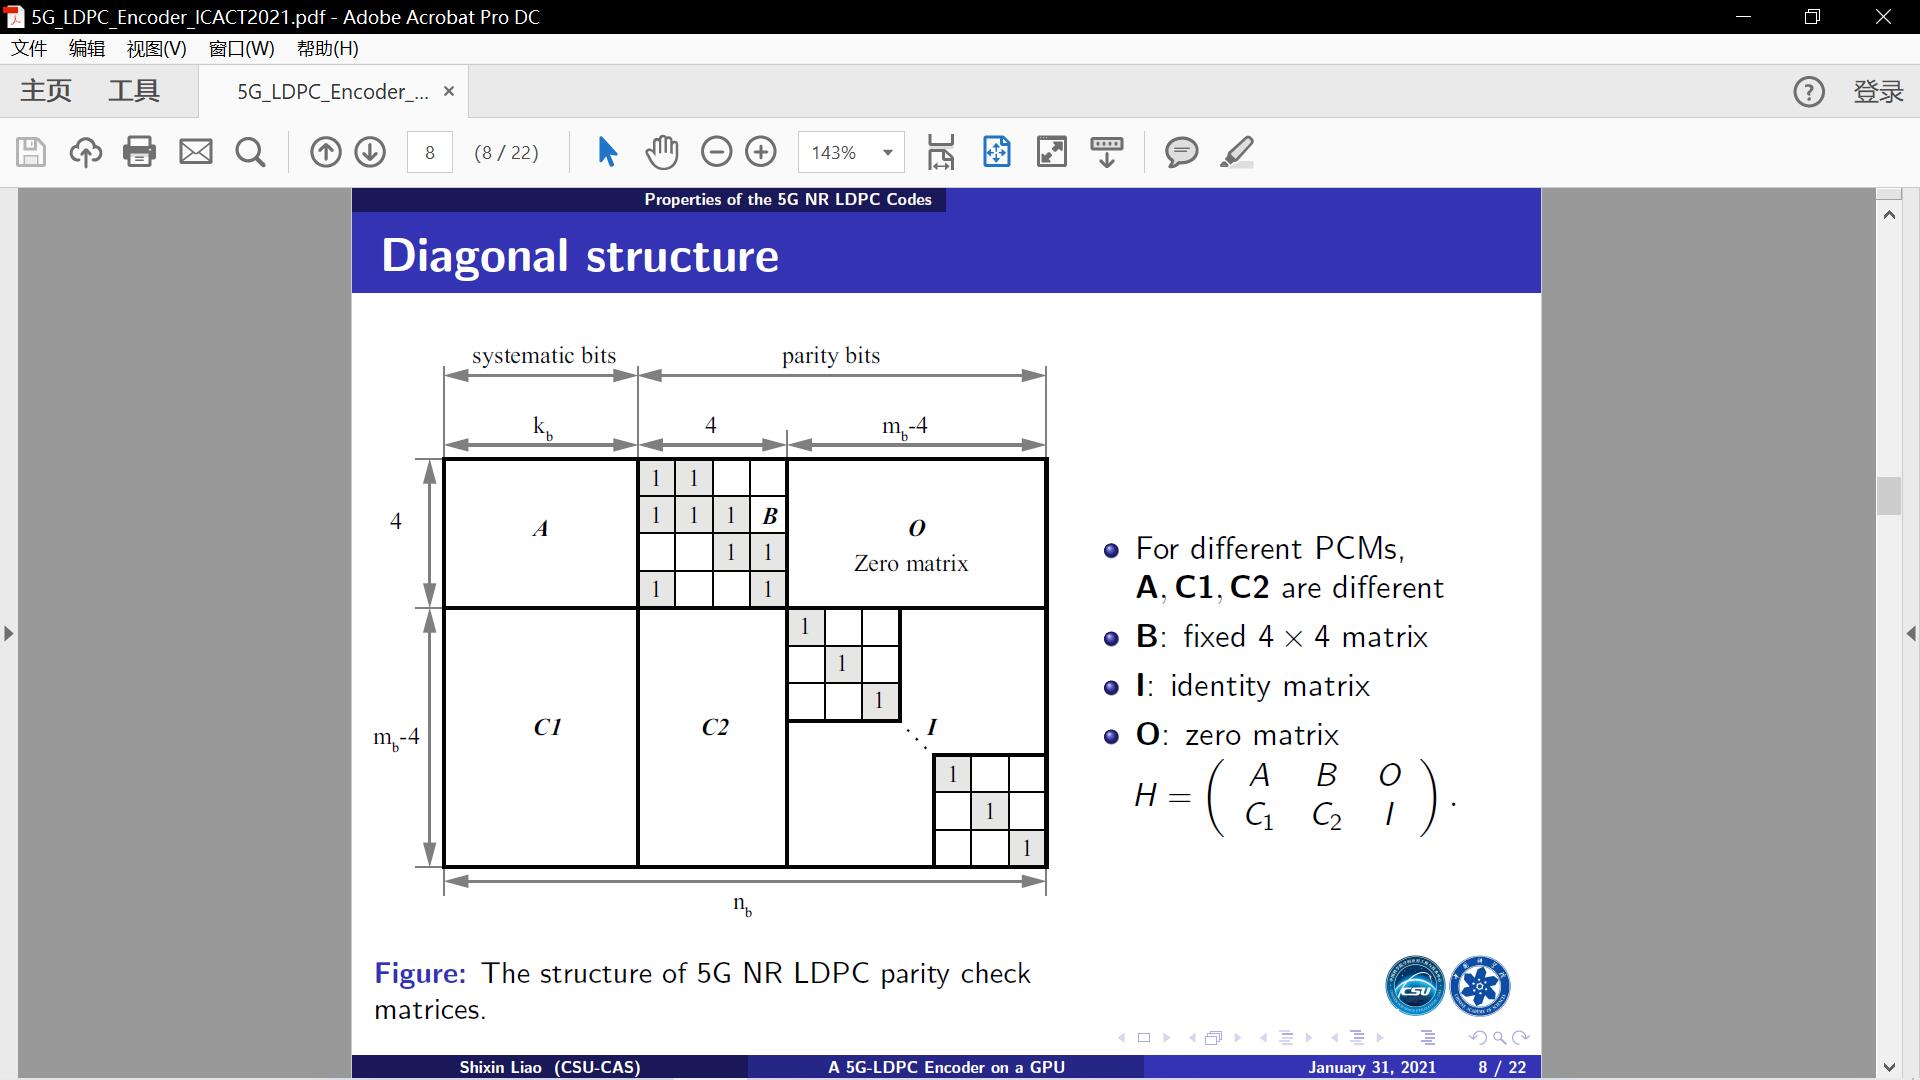
The third nice property of the 5G NR LDPC codes is that their parity check matrices or equivalently base matrices have good structure suitable for simple and parallel encoding. The dual-diagonal parity check sub-matrix B and the identity sub-matrix I can be exploited to encode 5G NR LDPC codes efficiently. From the above, the 5G NR LDPC codes have systematic, quasi-cyclic and the (dual) diagonal structure properties favorable for encoding with high throughput. The systematic property reduces the amount of the bits calculated. The QC property ensures the bits in each set can be calculated simultaneously. The (dual) diagonal structure property makes most sets of Z bits can be calculated simultaneously. Therefore, the 5G NR LDPC encoding algorithm has high potential parallelism.
|
|
ICACT20210136 Slide.20
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
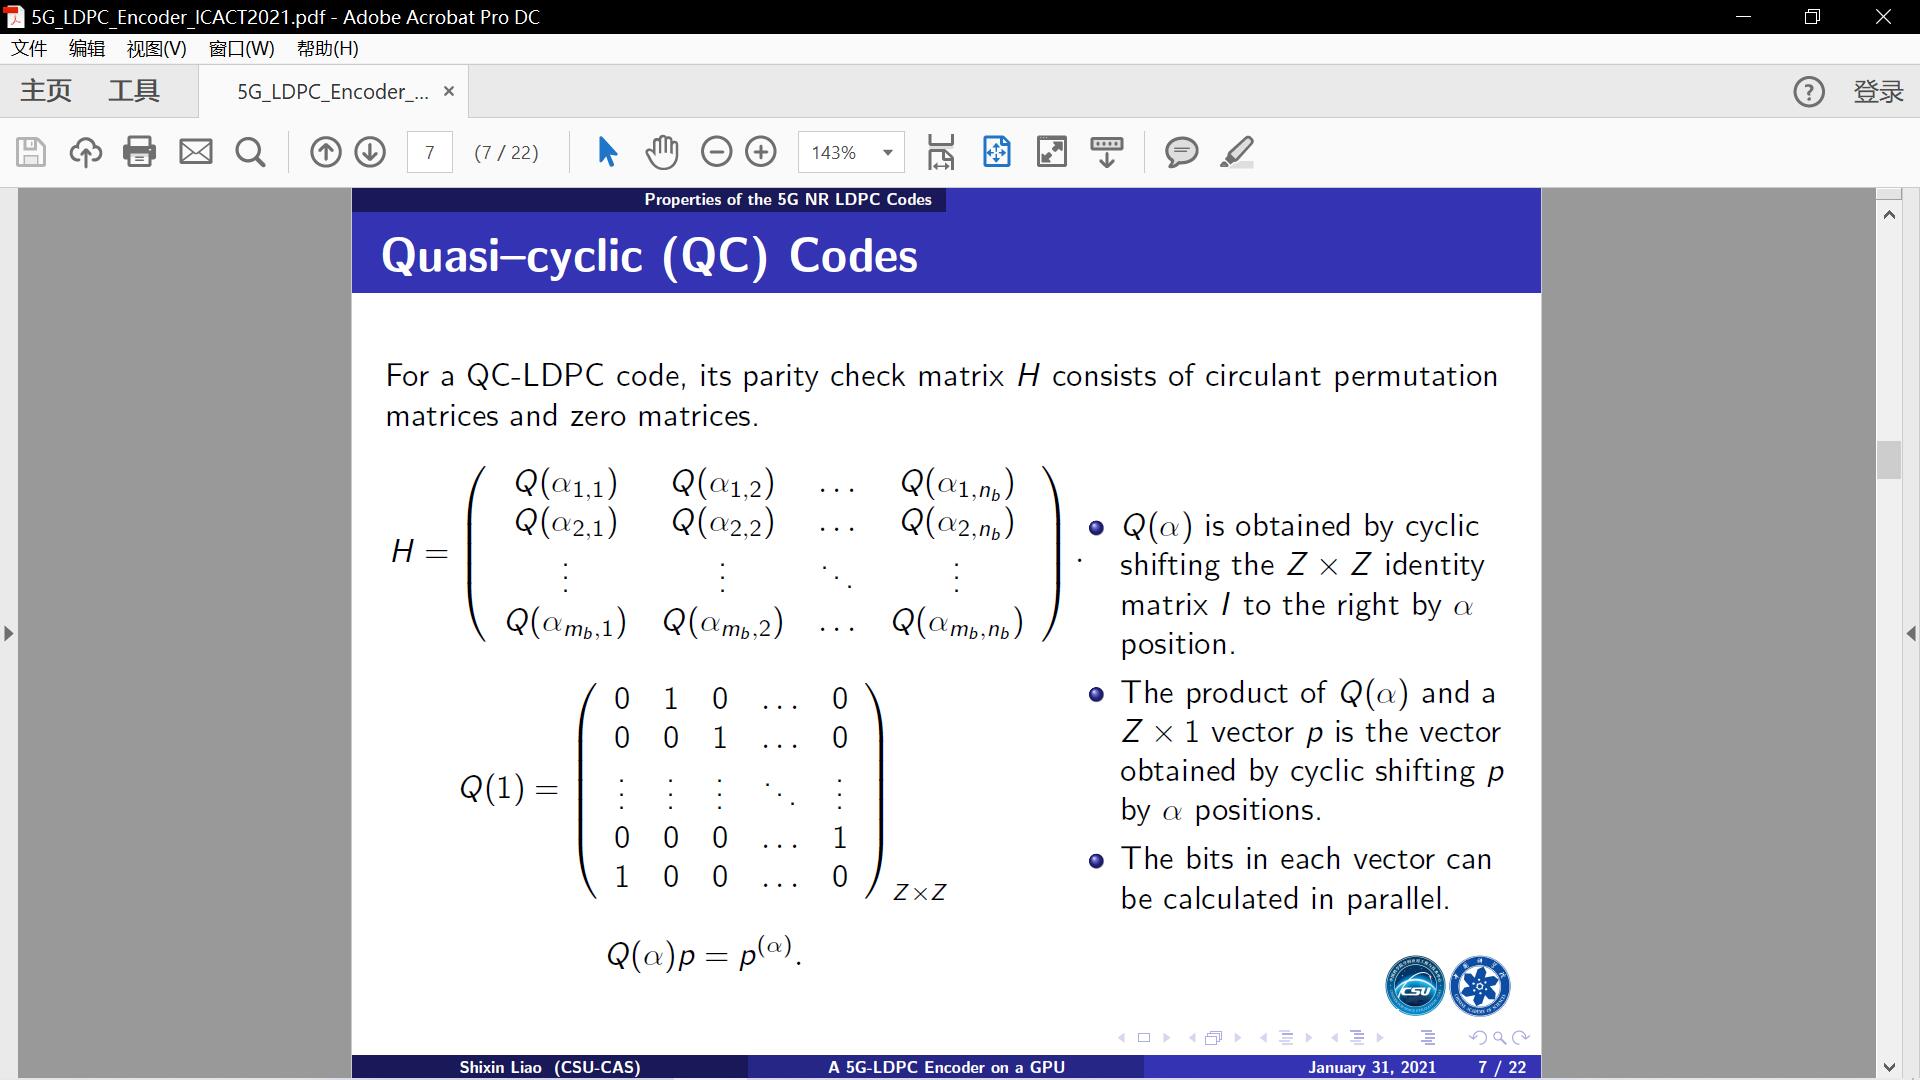 |
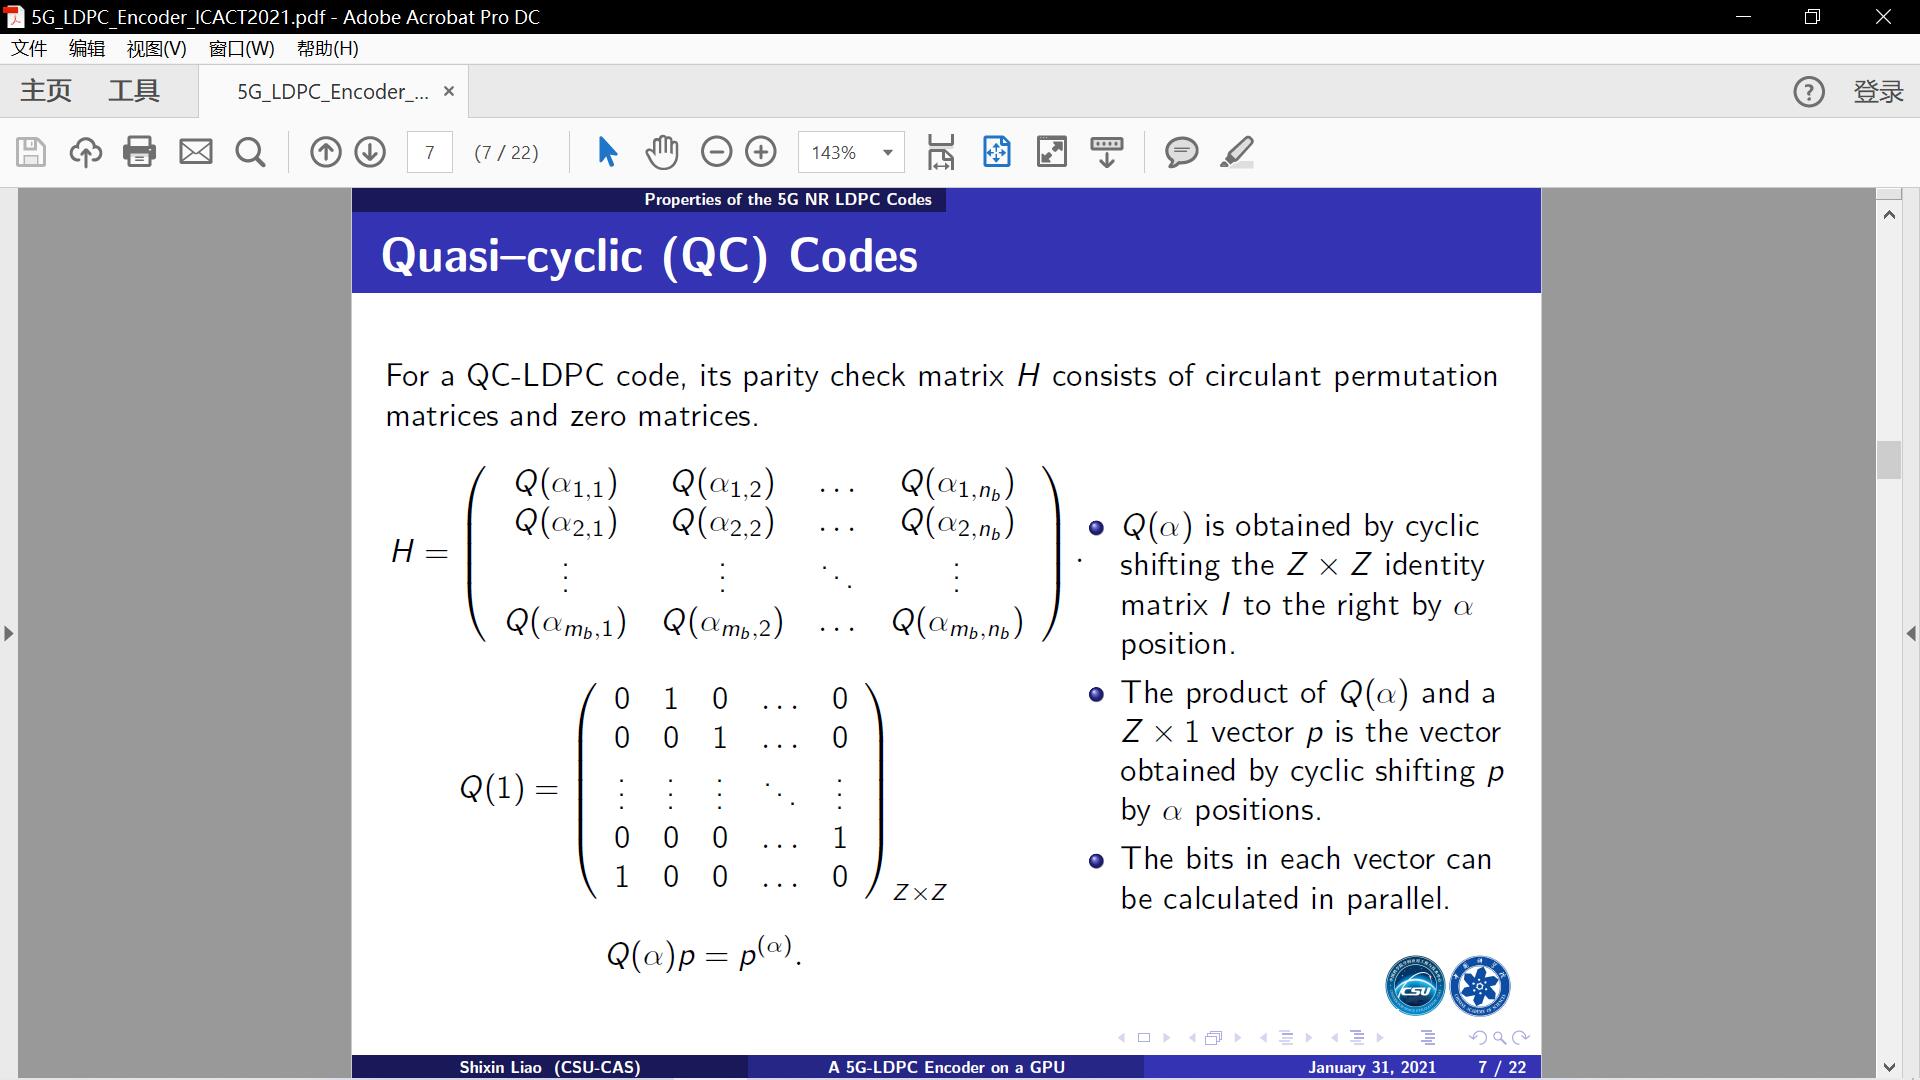
For a QC-LDPC code, its parity check matrix H consists of circulant permutation matrices and zero matrices. Let Z be the size of the circulant permutation matrix. Q(alpha) is obtained by cyclic shifting the Z*Z identity matrix I to the right by alpha position. The product of Q(alpha) and a Z*1 vector p is the vector obtained by cyclic shifting p by alpha positions. The bits in each vector can be calculated in parallel.
|
|
ICACT20210136 Slide.19
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
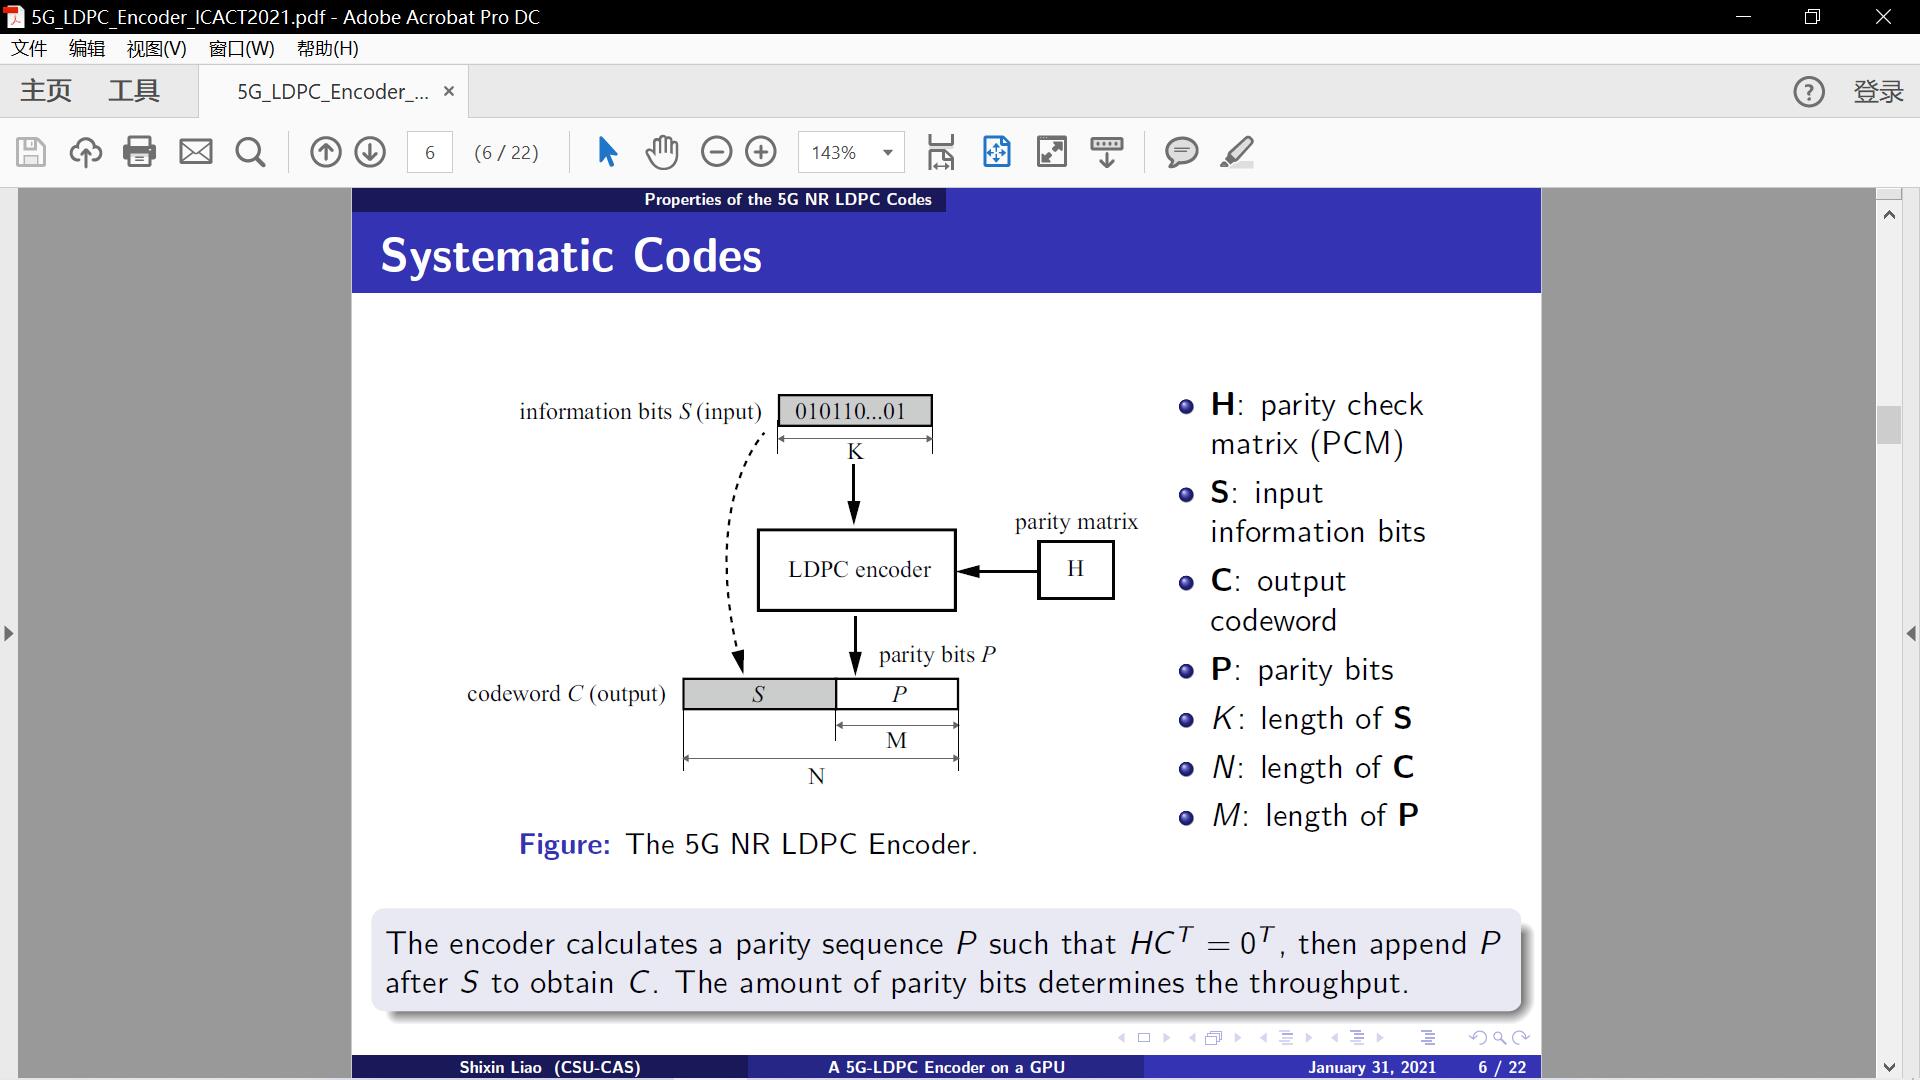 |
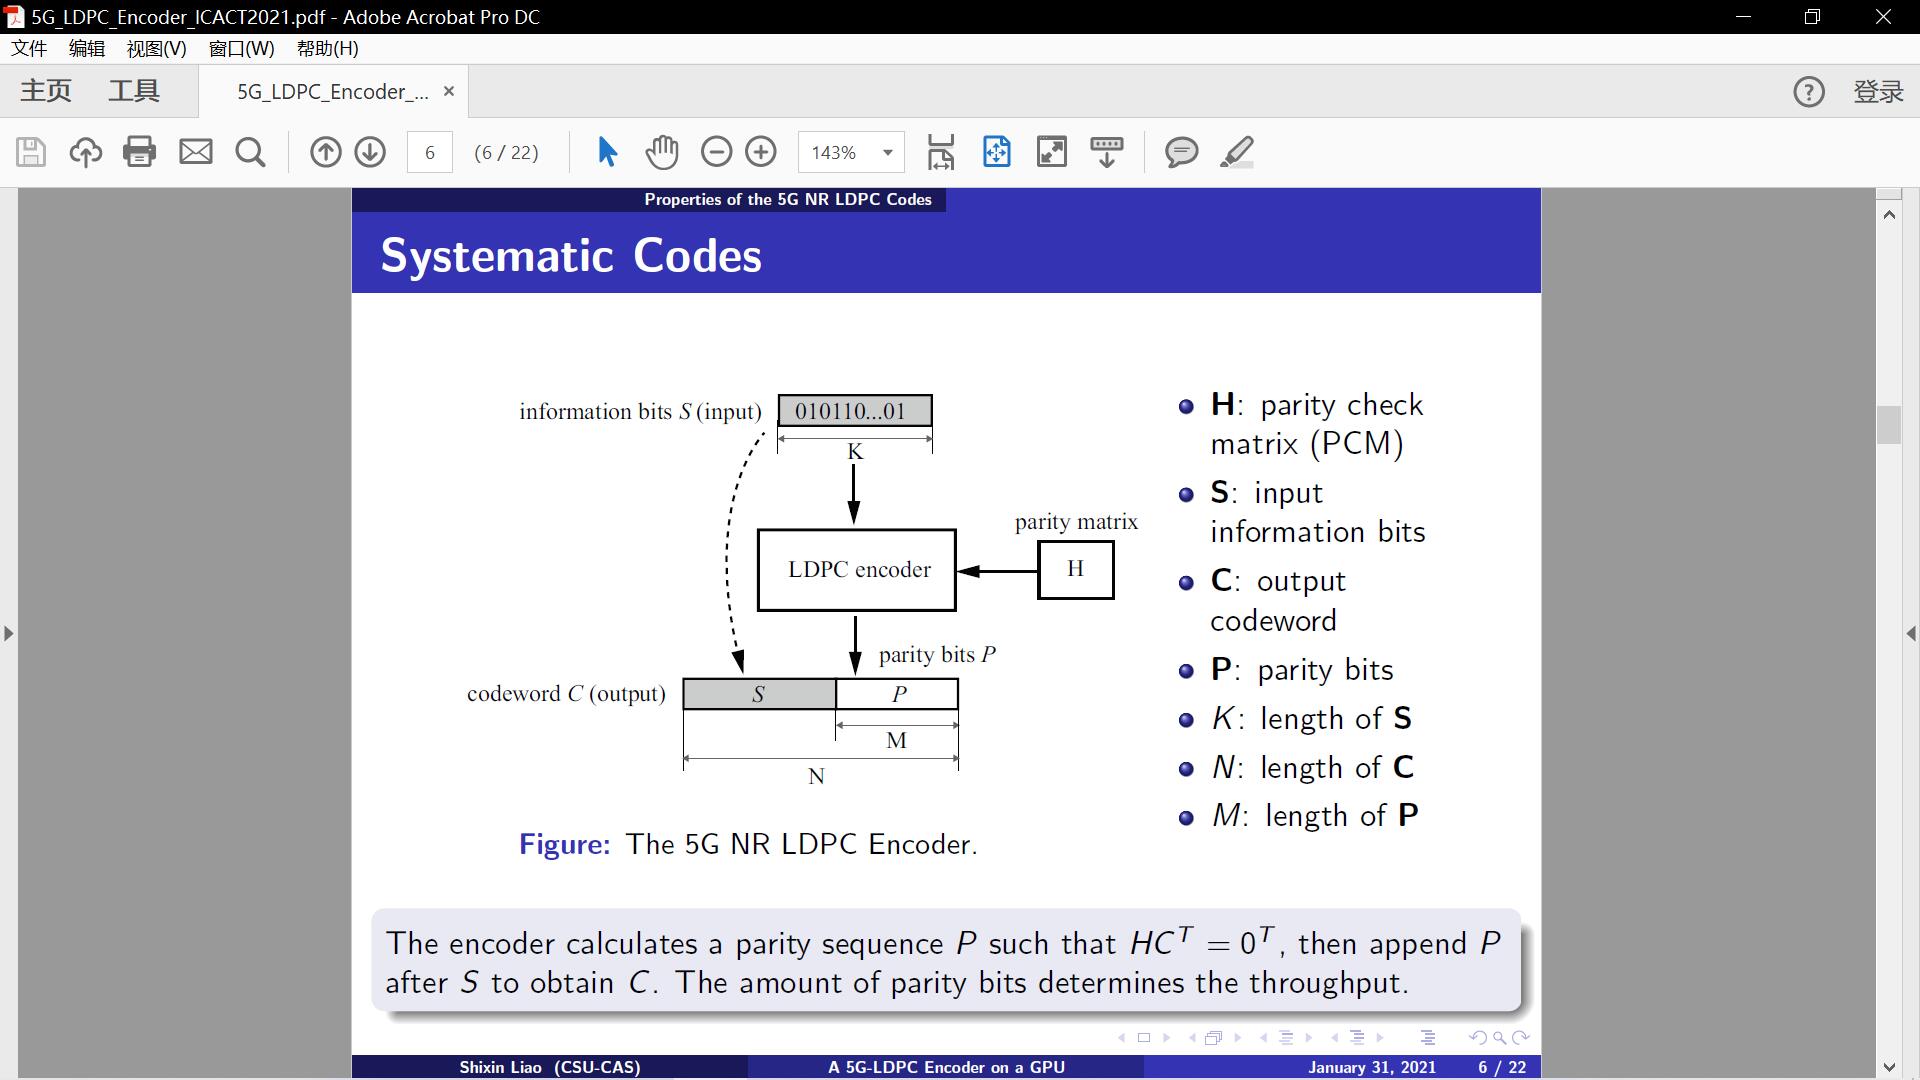
The 5G NR LDPC codes have a few nice properties for high throughput parallel encoding. First of all, the 5G NR LDPC codes are systematic codes. For an encoder of systematic codes, the input is an information sequence S and the output is a codeword sequence C. The encoder calculates a parity sequence P according to S and the parity check matrix H. The output codeword C is a combination of S and P.
|
|
ICACT20210136 Slide.18
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
 |
Properties of the 5G NR LDPC Codes.
|
|
ICACT20210136 Slide.17
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
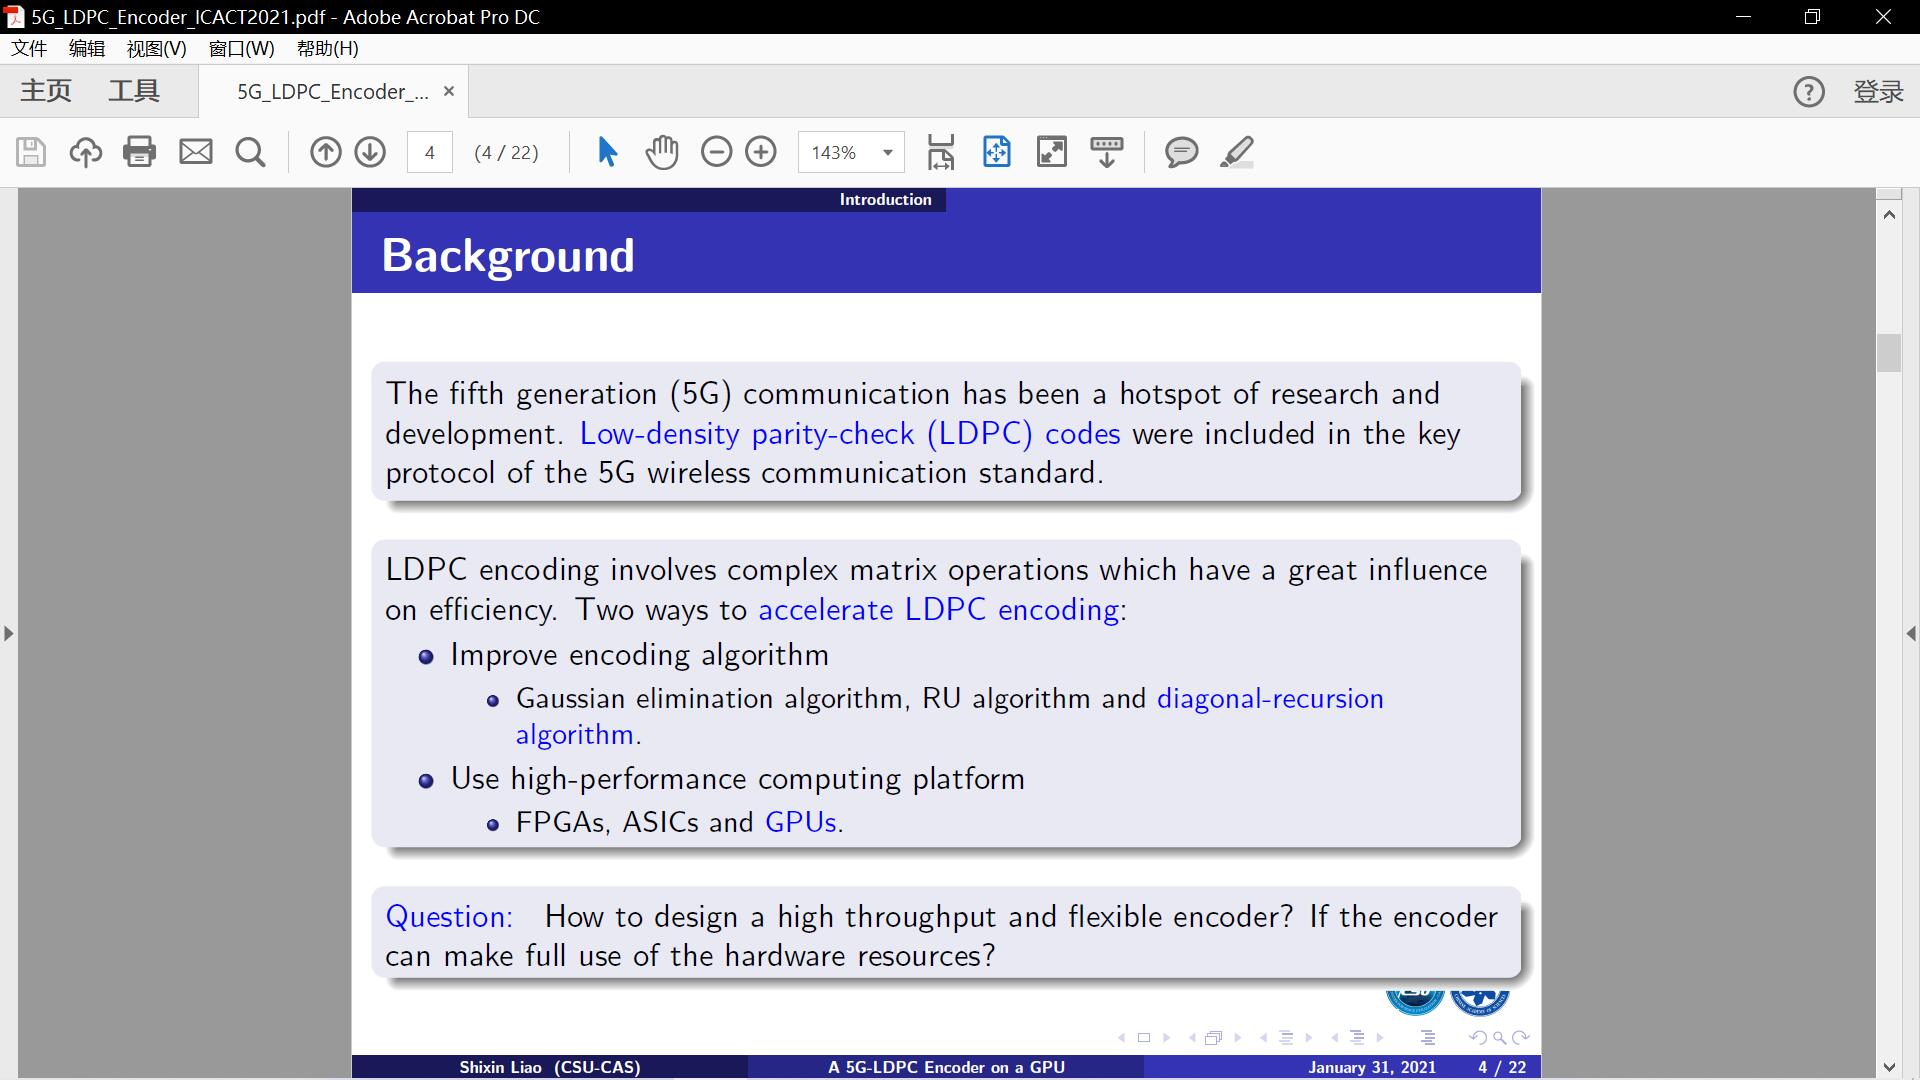 |
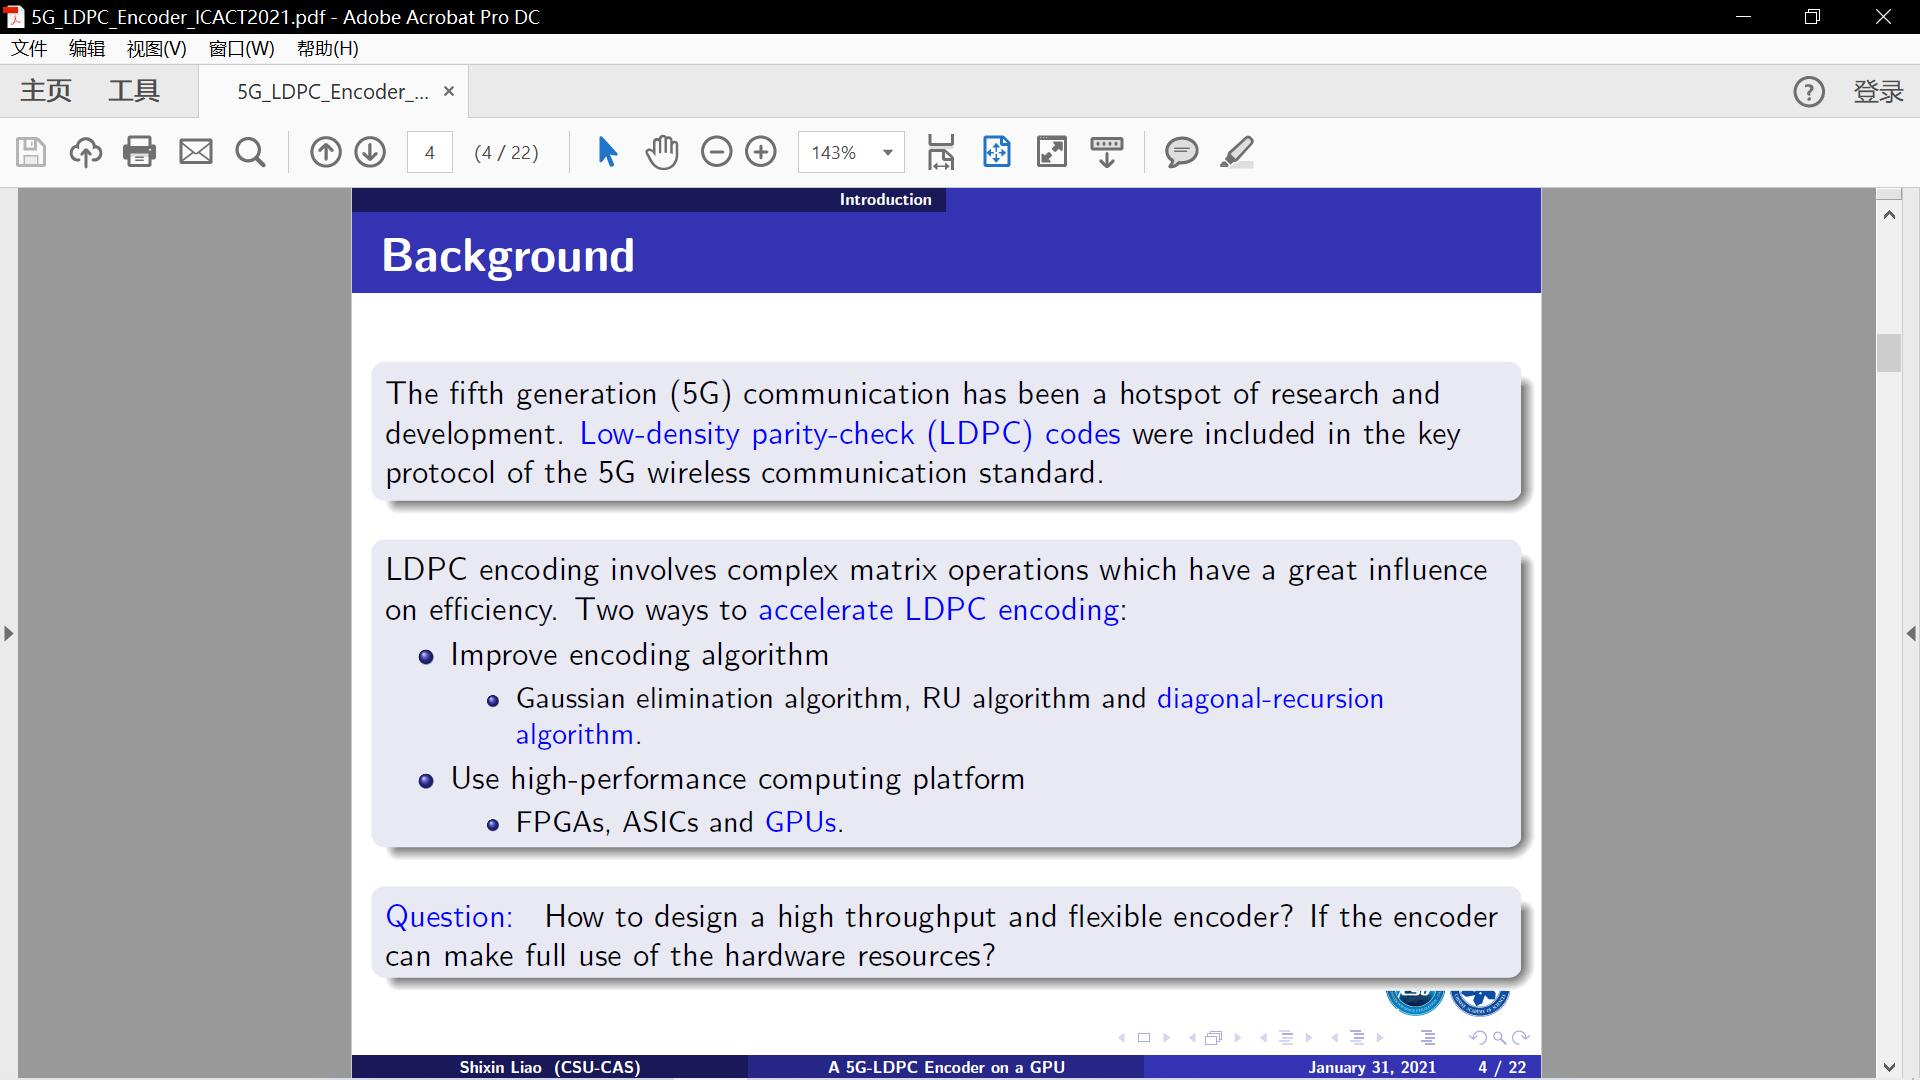
The fifth generation (5G) communication has been a hotspot of research and development. Low-density parity-check (LDPC) codes were included in the key protocol of the 5G wireless communication standard. LDPC codes can achieve the error correction capabilities close to Shannon limit. However, LDPC encoding involves complex matrix operations which have a great influence on efficiency. To meet the throughput requirement for the 5G wireless communication standard, high performance LDPC encoder must be explored. In the past decade, researchers and engineers try to accelerate LDPC encoding by improving encoding algorithm and using high-performance computing platform. So, the question is, if we can design an encoder exploiting the properties of LDPC codes and the properties of the hardware?
|
|
ICACT20210136 Slide.16
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
 |
Hello everyone. It’s great to be here with you today! Let me briefly introduce myself. I am Shixin Liao, a student of University of Chinese Academy of Sciences. I’m working and studying in the Key Laboratory of Space Utilization. Today, I’d like to talk to you about high throughput and flexible rate 5G NR LDPC encoder on a single GPU (Graphics Processing Unit).
|
|
ICACT20210136 Slide.15
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.14
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.13
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.12
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.11
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.10
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.09
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.08
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.07
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.06
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.05
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.04
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.03
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.02
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |
|
ICACT20210136 Slide.01
[Big slide for presentation]
|
Chrome Text-to-Speach Click!! |