 ICACT20240477 Slide.15
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Thank you for giving me this opportunity.
|
|
ICACT20240477 Slide.14
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
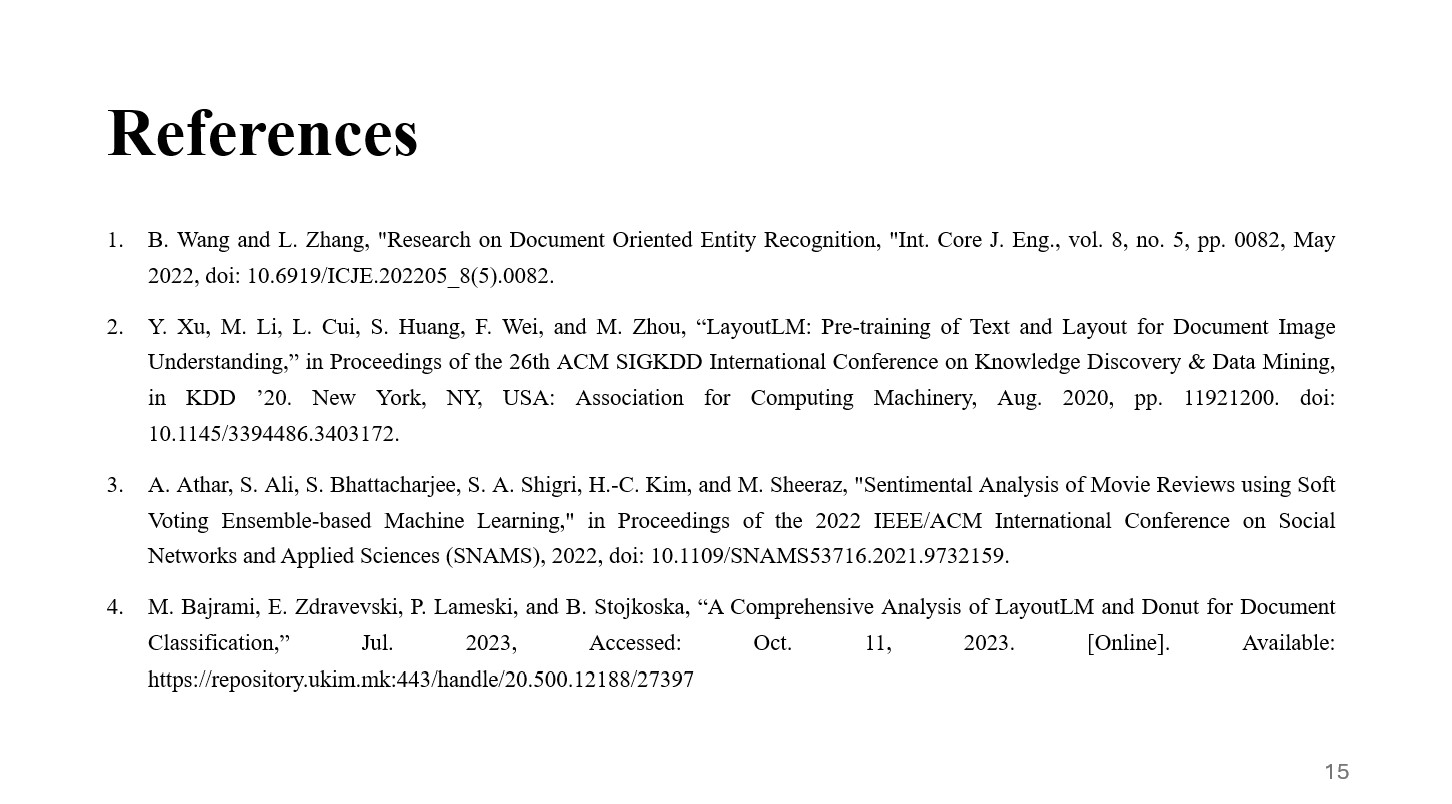 |
These are some references of the paper.
|
|
ICACT20240477 Slide.13
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
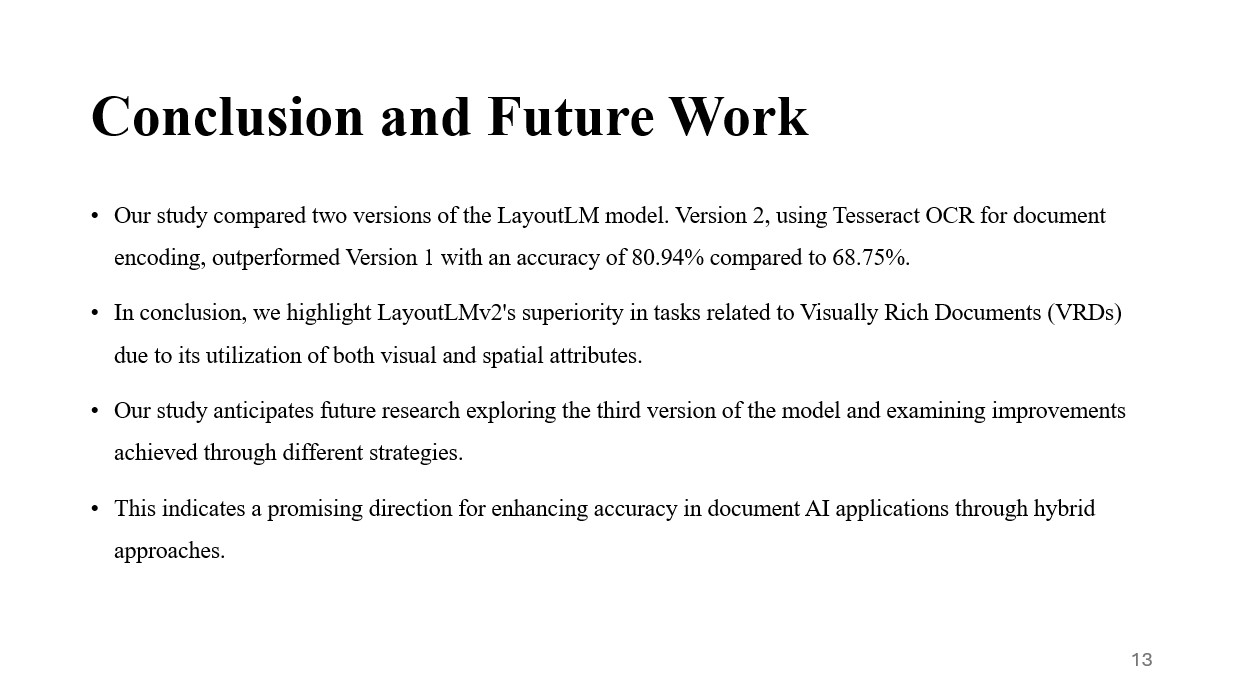 |
In our study, two versions of the LayoutLM model were examined. Version 2 exceeded Version 1 with an accuracy of 80.94% compared to 68.75%, utilizing Tesseract OCR for document encoding. Finally, we demonstrate how LayoutLMv2's use of both visual and spatial features makes it the best option for jobs involving Visually Rich Documents (VRDs). Future research on the third iteration of the model and its enhancements through various ways is anticipated by our study. This suggests a viable path for using hybrid techniques to improve accuracy in document AI applications.
|
|
ICACT20240477 Slide.12
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
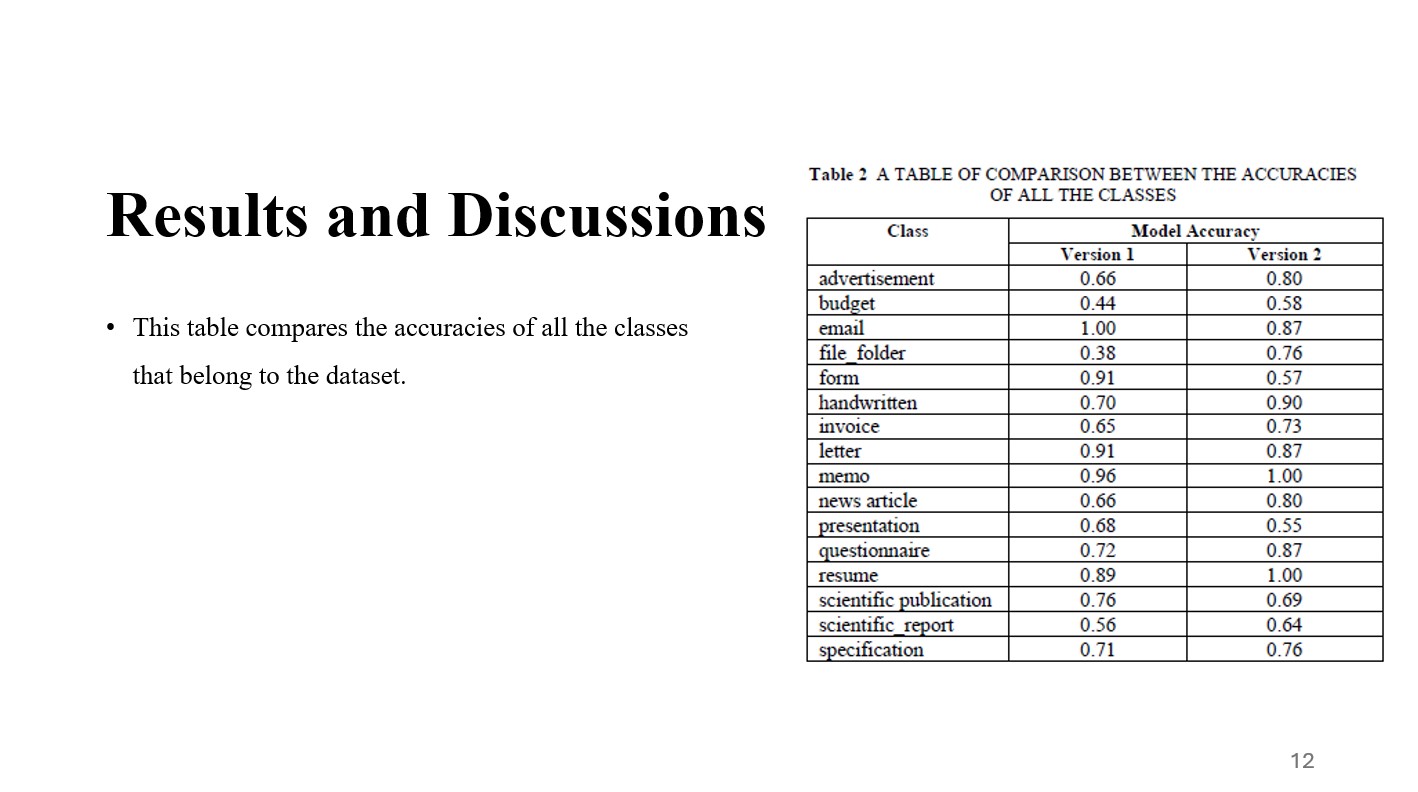 |
This table compares the accuracies of all the classes that belong to the dataset.
|
|
ICACT20240477 Slide.11
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
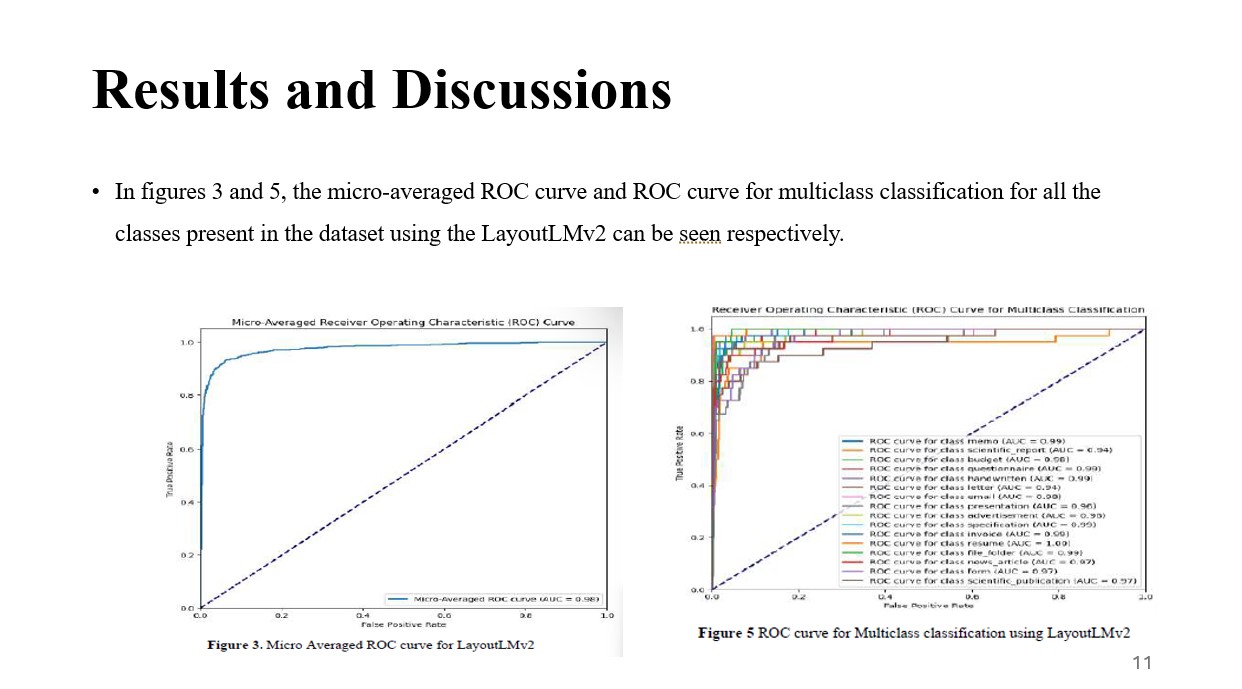 |
In figures 3 and 5, the micro-averaged ROC curve and ROC curve for multiclass classification for all the classes present in the dataset using the LayoutLMv2 can be seen respectively.
|
|
ICACT20240477 Slide.10
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
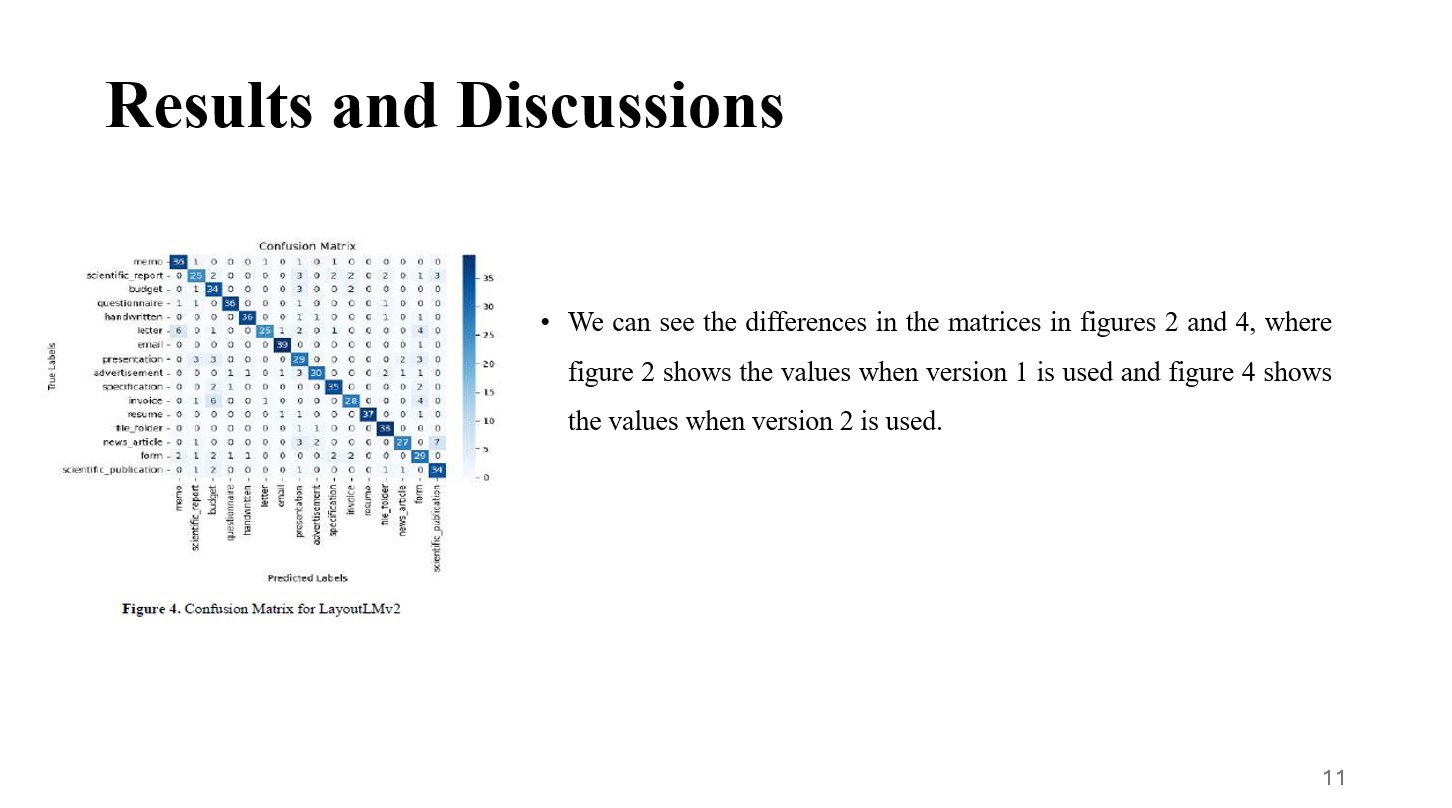 |
Figure 4 shows the confusion matrix when version 2 is employed.
|
|
ICACT20240477 Slide.09
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
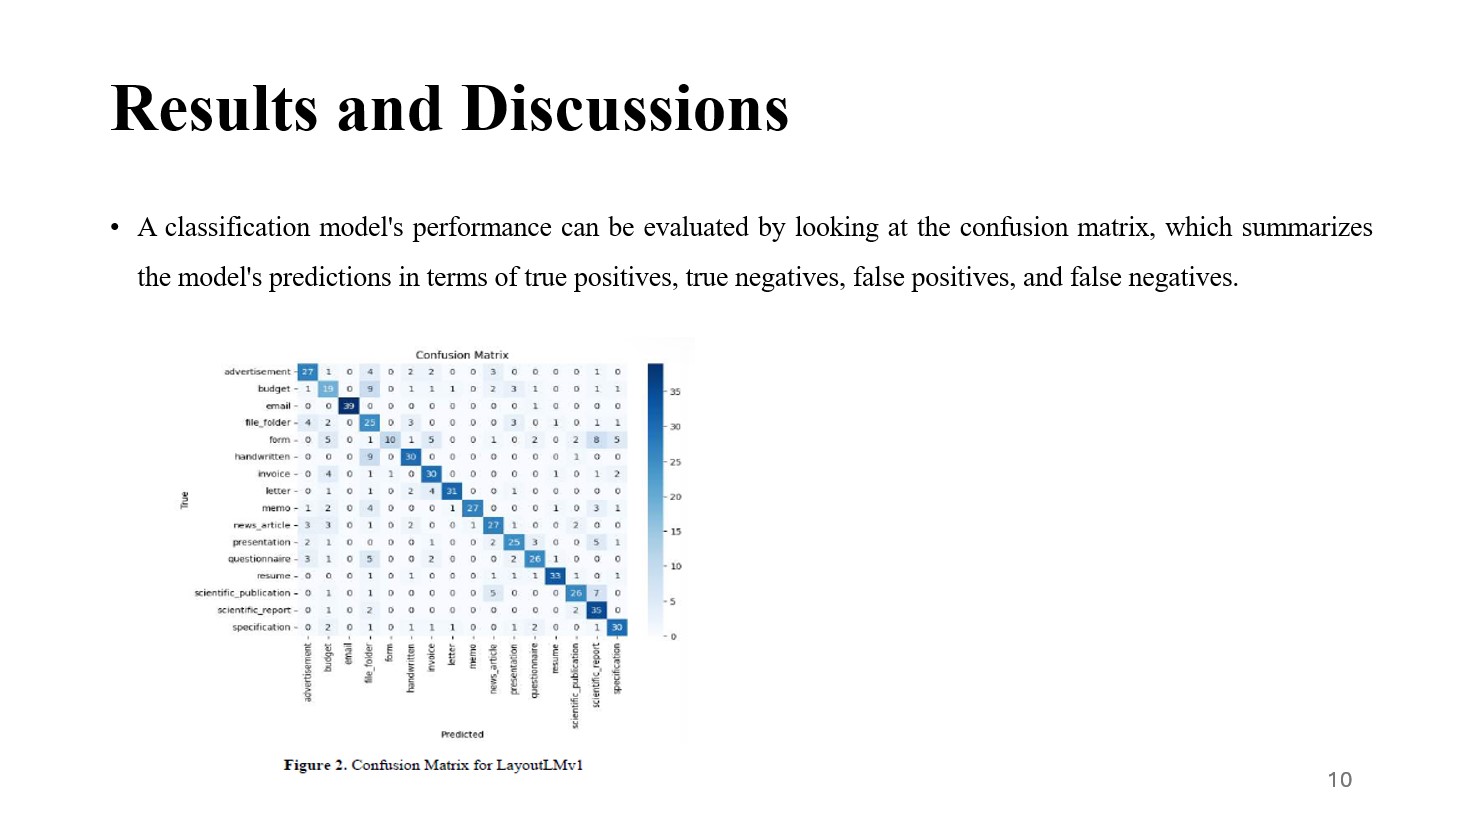 |
A classification model's performance can be evaluated by looking at the confusion matrix, which summarizes the model's predictions in terms of true positives, true negatives, false positives, and false negatives.
Figure 2 shows the values when version 1 is employed.
|
|
ICACT20240477 Slide.08
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
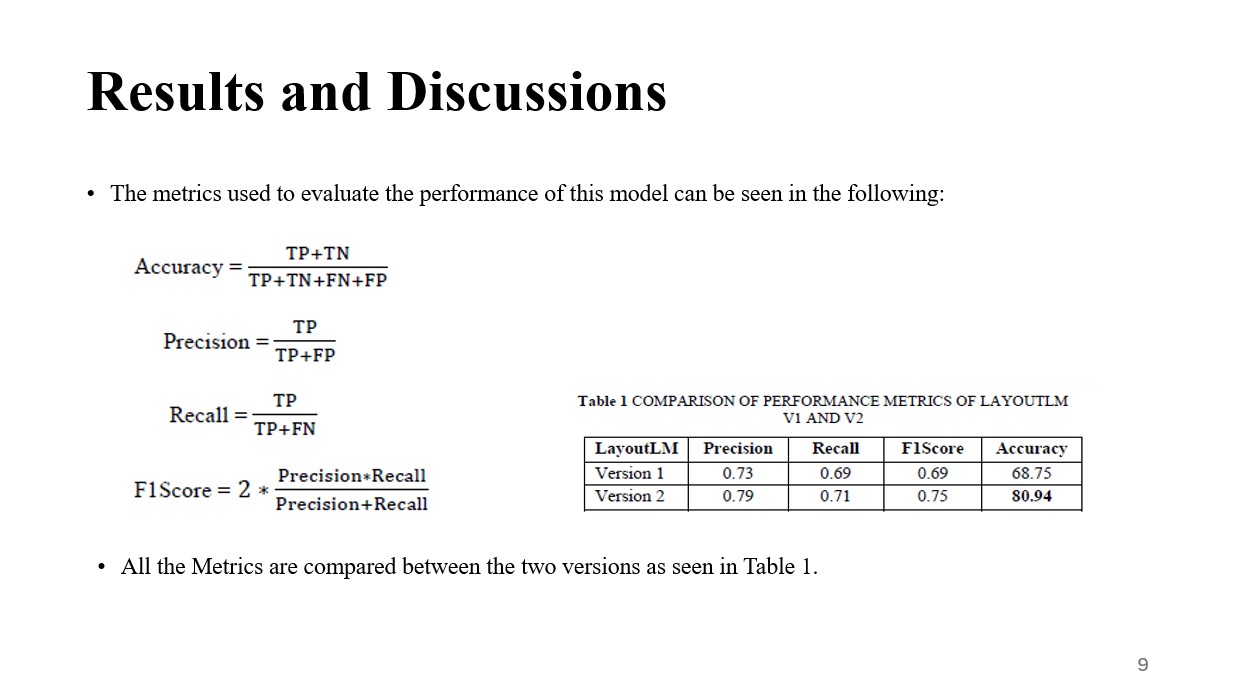 |
The metrics used to evaluate the performance of this model can be seen in the following:
Accuracy, Precision, recall and F1 score
All the Metrics are compared between the two versions as seen in Table 1.
|
|
ICACT20240477 Slide.07
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
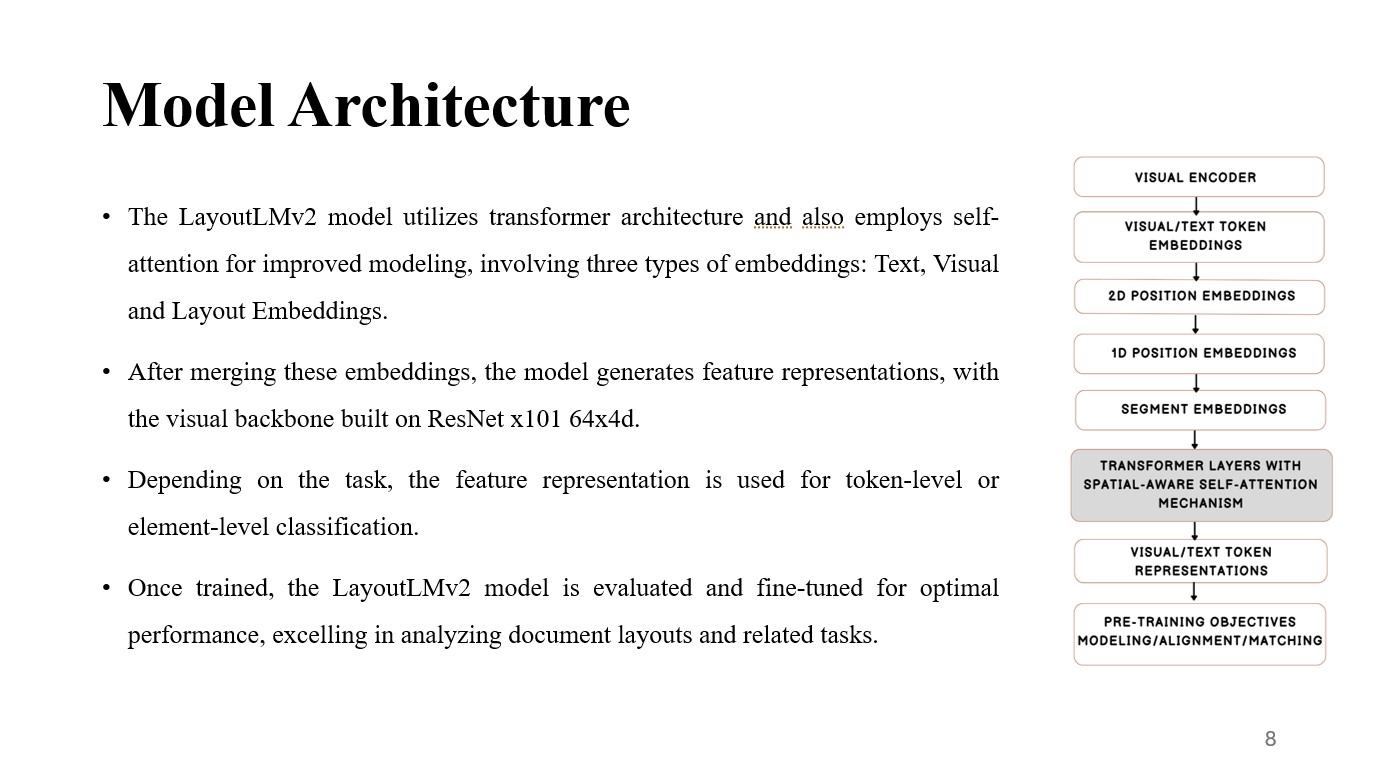 |
The LayoutLMv2 model, which involves three different forms of embeddings—text, visual, and layout—uses transformer architecture in addition to self-attention for enhanced modeling.
Following the merging of these embeddings, the model produces feature representations, with ResNet x101 64x4d serving as the visual foundation.
The feature representation is used for either element-level or token-level categorization, depending on the job.
The LayoutLMv2 model, which is excellent at evaluating document layouts and associated tasks, is assessed after training and adjusted for maximum performance.
|
|
ICACT20240477 Slide.06
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Using truncation for lengthier inputs, padding for uniform input length, and label indexing via dictionaries (idx2label and label2idx) for the numerical representation of class labels, we employed a variety of Hugging Face Transformers Libraries.
While the model architecture is the same in all versions, LayoutLMv2 leverages visual information early in the training process by integrating Tesseract OCR and visual embeddings during pre-training.
|
|
ICACT20240477 Slide.05
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Data Description: The RVL-CDIP dataset is publicly accessible and consists of document pictures used for testing various models, including those for document classification, information retrieval, and question-answering systems.
It contributed to the training of several models. However, because to technological limitations, only a tiny portion of the dataset is used in this research.
Data Preparation: Text from pictures is converted into machine-readable English using Tesseract OCR in the research for the LayoutLMv2 model, which incorporates text image alignments and matching jobs with an attention mechanism.
|
|
ICACT20240477 Slide.04
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Numerous strategies, such as deep learning methods like CNNs, RNNs, RNTNs, and RCNNs, have been investigated.
A hybrid technique for structured document interpretation called Layout Transformer (LiLT) model is covered in a research. To extract text bounding boxes and contents from input document pictures, LiLT uses commercial OCR engines.
Another research that compared LayoutLM to Donut found that LayoutLM performed better in picture categorization on a variety of datasets.
Subsequent investigations explore the integration of textual and visual input into a single classification task, attaining great performance using the publicly available dataset RVL-CDIP.
|
|
ICACT20240477 Slide.03
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
In modern data-centric processes, data digitization and information extraction are essential.
Information extraction is made difficult by the abundance of unstructured document data generated by business activities.
Scanned photographs and digital documents—which include a range of categories such contracts, industry reports, and purchasing—are the paper's primary focus.
The Layout language model tackles the difficulty of extracting meaningful information from complicated document layouts. It is developed for Natural Language Processing (NLP) and text recognition in complex layouts.
For uses including comprehension of texts and providing answers to visual queries in addition to classification.
|
|
ICACT20240477 Slide.02
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
The paper presents the application of the LayoutLM model to automatically extract information from complexly organized texts and examines the significance of effective information retrieval in many fields.
A subset of the RVL-CDIP dataset, including 400,000 photos arranged into 16 classes with a cap of 200 images per class, is the subject of this study.
There are three sets of the dataset: training, validation, and testing. The papers are categorized using LayoutLMv2 and version 1, with accuracy rates of 80.94% and 68.75%, respectively.
The study shows how well LayoutLM analyzes and comprehends a variety of document forms and contents.
|
|
ICACT20240477 Slide.01
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Contents of this presentation consists of:
Abstract of the paper
Introduction about the study
Discussion of some of the related works to this study
The proposed Methodology
The architecture of the model
Results and discussions
Conclusion and future works
|
|
ICACT20240477 Slide.00
[Big slide for presentation]
[YouTube] |
Chrome Text-to-Speach Click!! |
 |
Hello Everyone! My name is Kounen Fathima, and today I will be presenting to you my study, which is titled "Enhancing Multiclass Document Classification with LayoutLM: A Comparative Study of V1 and 2".
|
















