 ICACT20210125 Slide.01
[Big Slide]
[YouTube] |
Chrome  Click!! |
 |
Today, we would like to present the research: Automatic Vocabulary Grouping and Deep Combination for News Credibility and Reliability Evaluation Corresponding to Specific Language.
Today's presenter is Ming Shen Jian, from Taiwan, National Formosa University |
| ICACT20210125 Slide.02
[Big Slide]
[YouTube] |
Chrome Click!! |
 |
It is today's online
The first I try to introduce about why we do this research
Second, the related work, about the news identification
especially for the fake news identification
How to analysis the online web service or online web news
The third is the proposed system about how to collect, identify and classify the news.
Fourth section shows the implementation of the proposed system and corresponding results.
|
| ICACT20210125 Slide.03
[Big Slide]
[YouTube] |
Chrome Click!! |
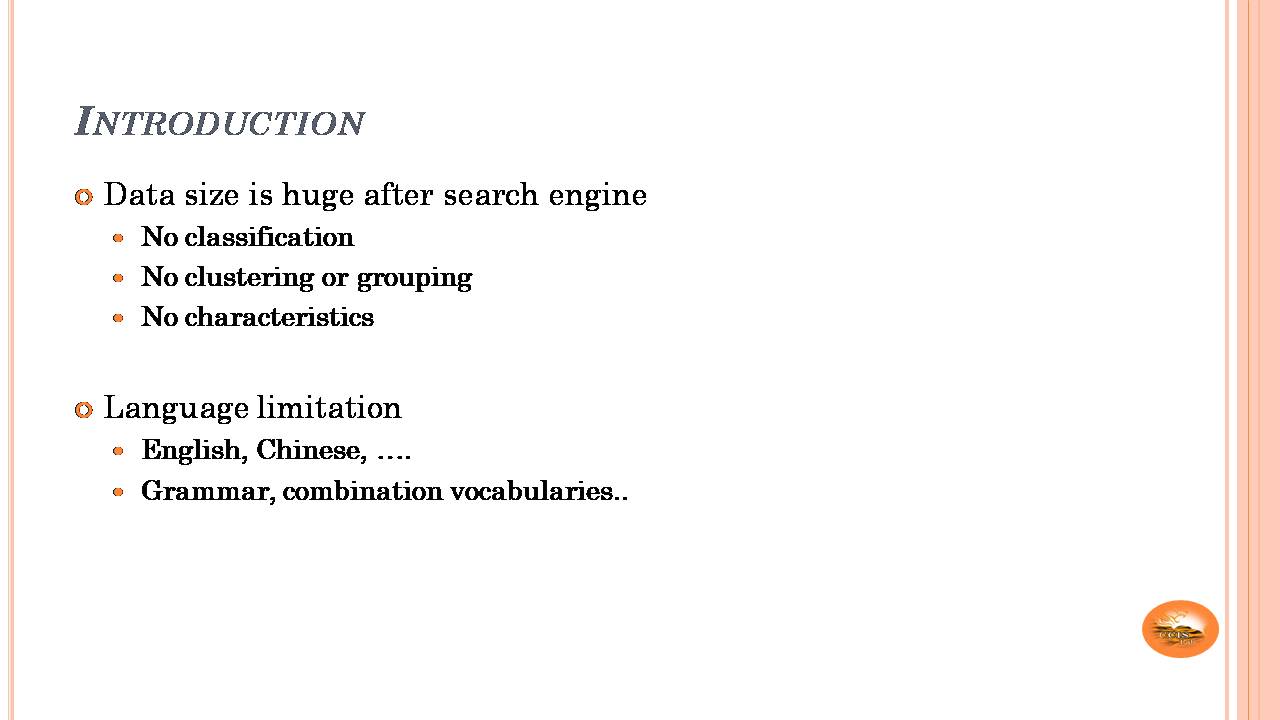 |
There are so many different content provided and broacasted through the Internet
So no matter the news is true or fake, the data size is very huge.
If you used a search engine by searching some special keywords, the response of the data size is huge
The corresponding with pages
Second the key word is not given enough, the data will be various and not classified.
More Program based on Java or different programming languages could separate the English words.
But different languages such as Japanese, Chinese, Korean, etc. cannot use the same method to divide the sentence into independent vocabularies. |
| ICACT20210125 Slide.04
[Big Slide]
[YouTube] |
Chrome Click!! |
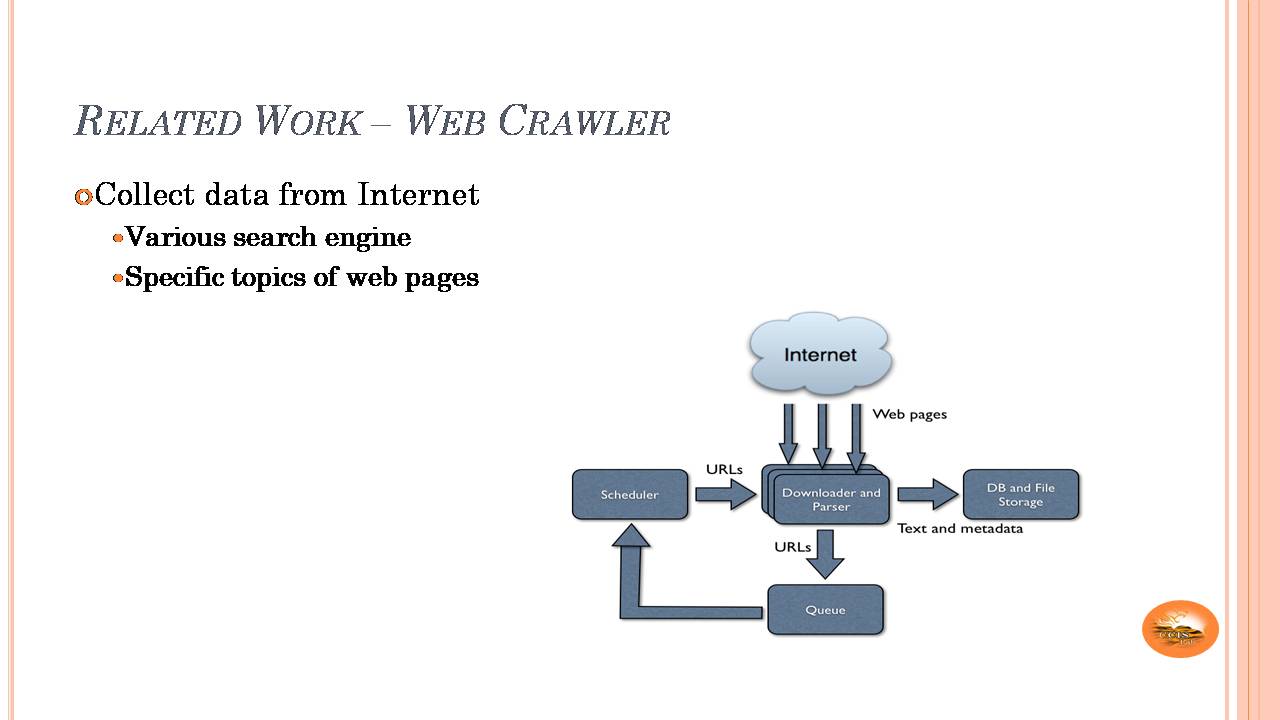 |
How to use the web crawler when collects data from internet or search engine
Information collected from web pages with some specific conditions or according to some key words.
Some information are collected from the third party flase news proved center |
| ICACT20210125 Slide.05
[Big Slide]
[YouTube] |
Chrome Click!! |
 |
In this research
By using the HBase which is the nosql type database, variable length data can be recorded.
That is not a relevance database.
The HDFS file system is also proposed for distributed file storage.
Hadoop or MapReduce was proposed for distributing tasks for parallel processing and Merging reports from distributed node
|
| ICACT20210125 Slide.06
[Big Slide]
[YouTube] |
Chrome Click!! |
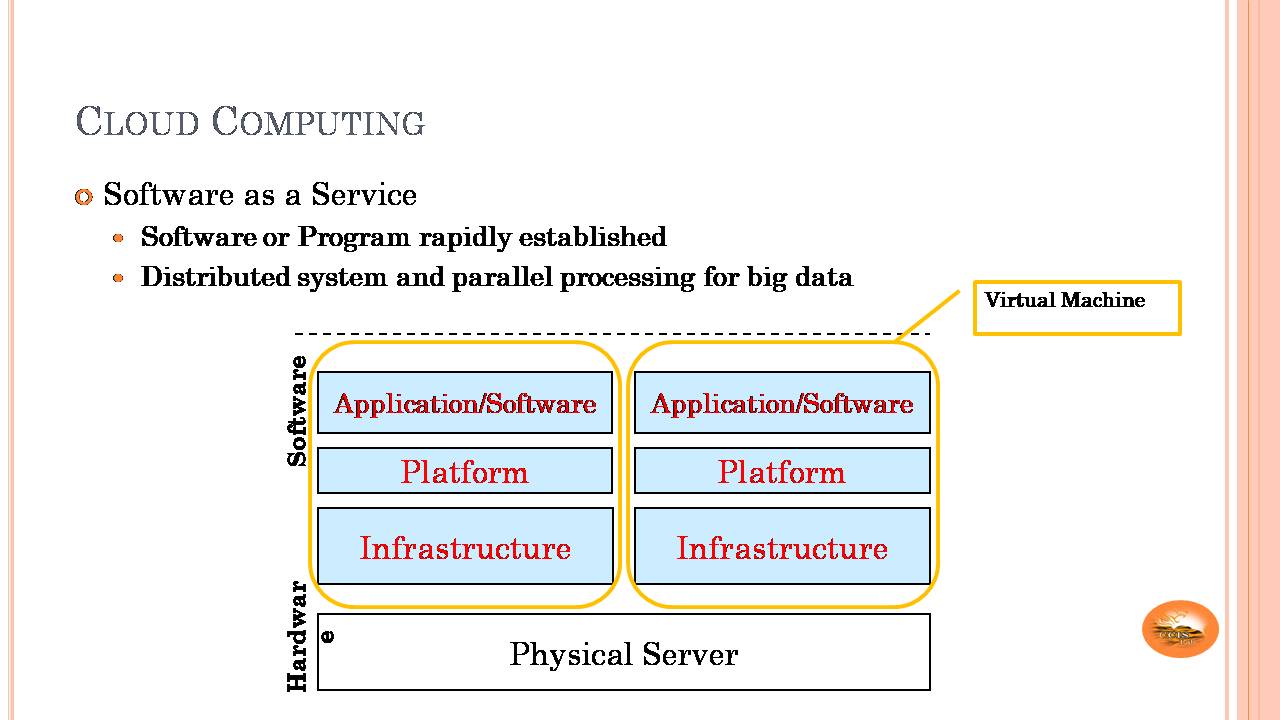 |
In Cloud Computing, Software as a Service is one of the important services.
Software or Program can be rapidly established based on virtual machine.
In addition, Distributed system and parallel processing for big data can be done be various virtual machines.
|
| ICACT20210125 Slide.07
[Big Slide]
[YouTube] |
Chrome Click!! |
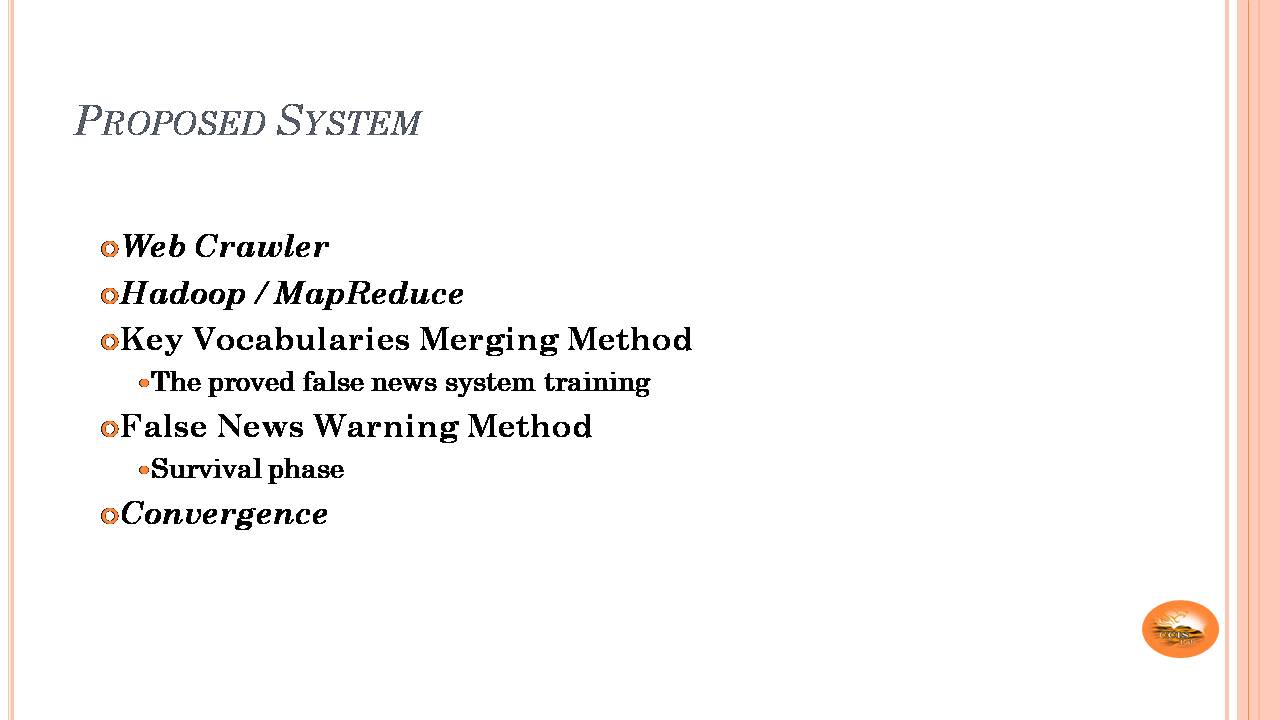 |
In this research, we propose the system including:
Web Crawler,
Hadoop / MapReduce,
Key Vocabularies Merging Method including the proved false news system training,
False News Warning Method ,
Survival phase,
and Convergence.
|
| ICACT20210125 Slide.08
[Big Slide]
[YouTube] |
Chrome Click!! |
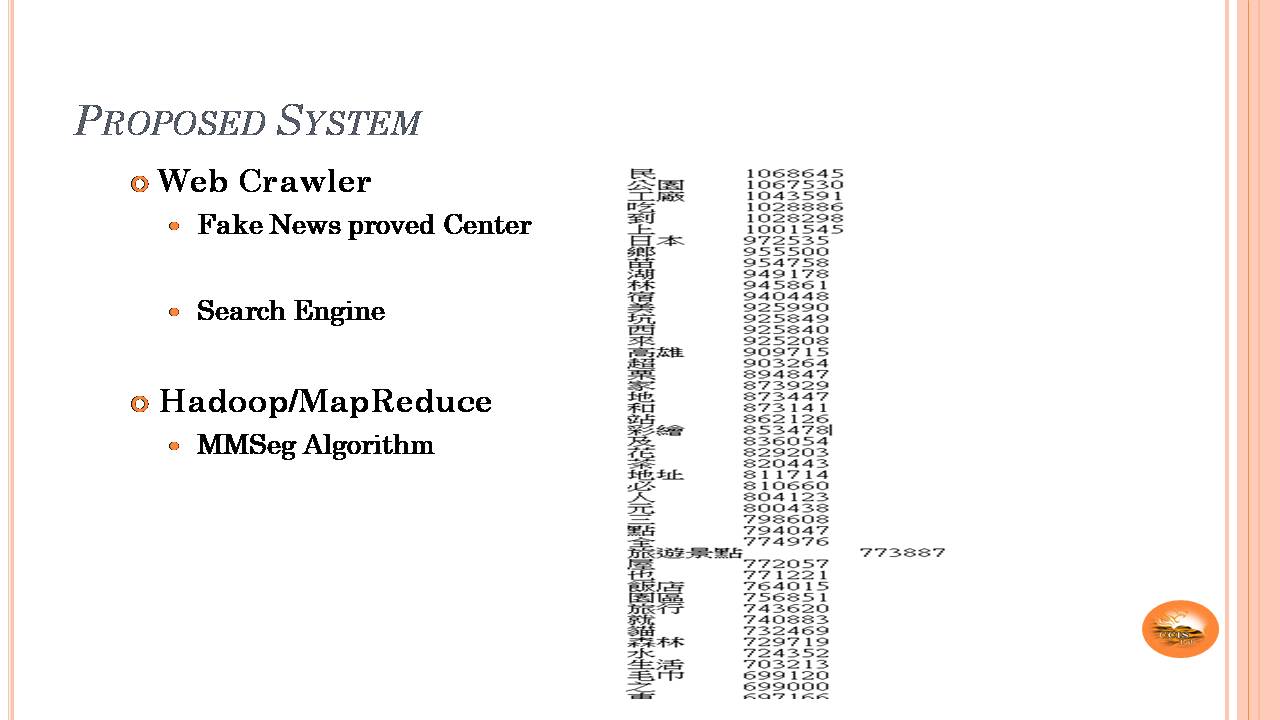 |
The Web Crawler is used to collect the data from the third party Fake (False) News proved Center. The news from this resource is already proved and verified.
Other unproved or according to the proved false news are collected from search engine.
Based on MMSeg algorithm, the Chinese vocabularies can be divided and recognized individually.
|
| ICACT20210125 Slide.09
[Big Slide]
[YouTube] |
Chrome Click!! |
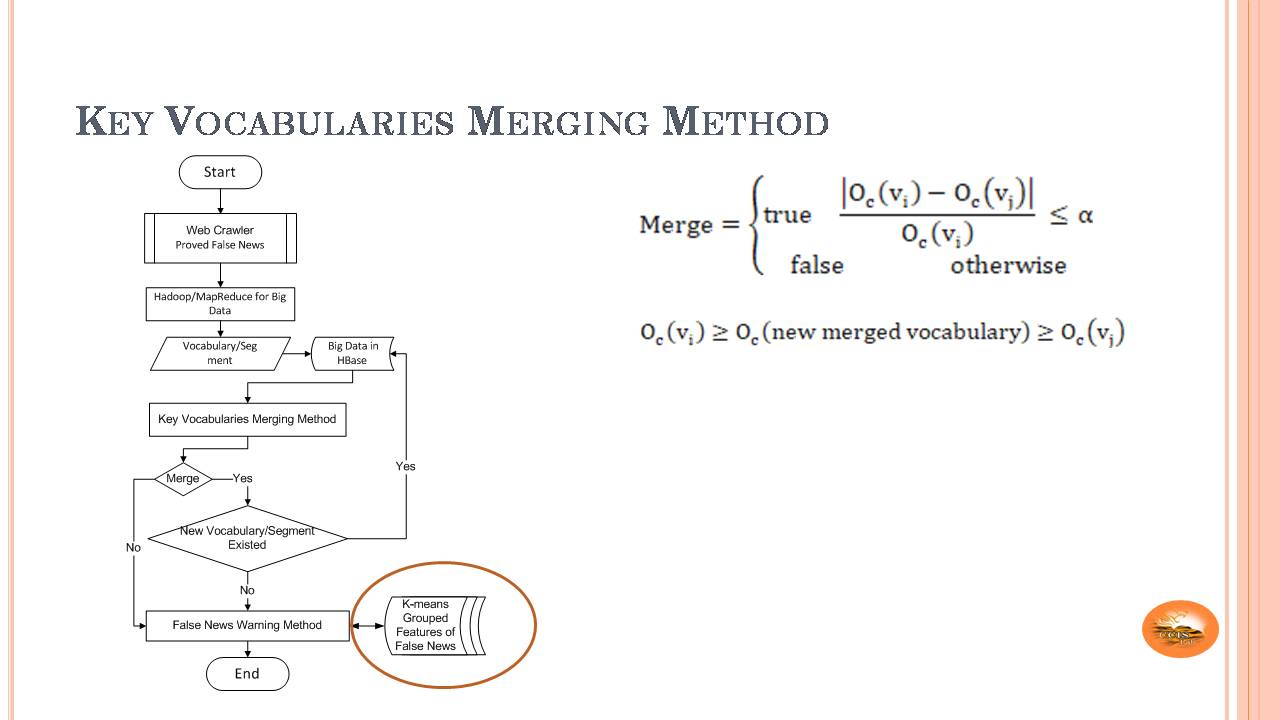 |
Based on the on demand given value, the merging range can be defined for two independent vocabularies merging.
New merged or created vocabulary should appear in the original news or text.
If the new vocabulary is rarely or never used, this new create vocabulary will be deleted as "useless key vocabulary".
|
| ICACT20210125 Slide.10
[Big Slide]
[YouTube] |
Chrome Click!! |
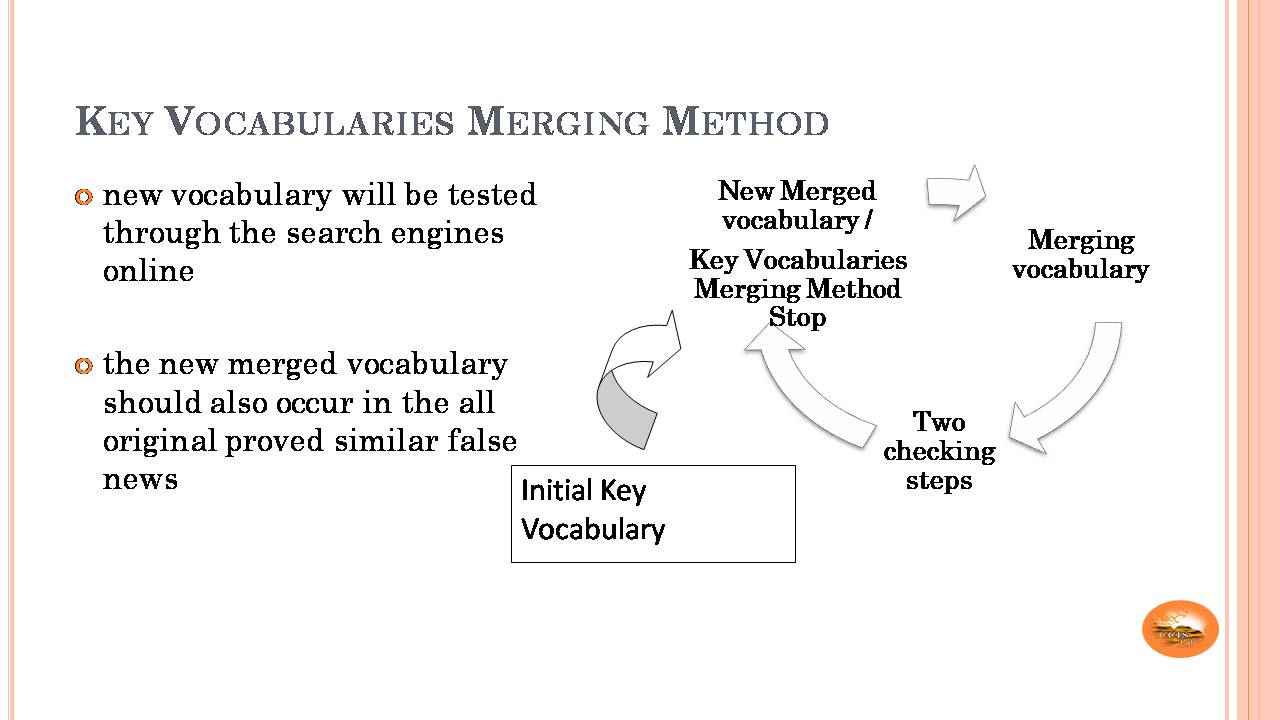 |
After many generations, the merged vocabulary will be extended.
When the vocabulary is no longer extended, this vocabulary could be set as the feature vocabulary of this false news. |
| ICACT20210125 Slide.11
[Big Slide]
[YouTube] |
Chrome Click!! |
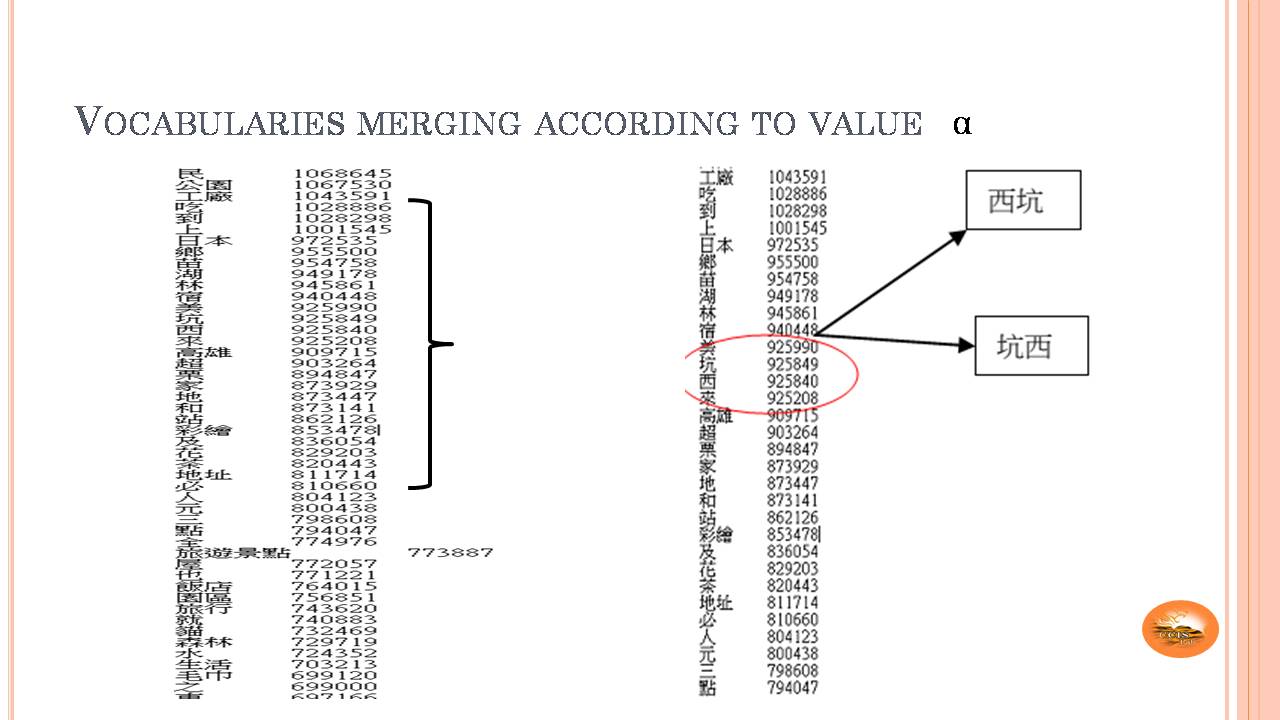 |
An example here.
Left side is the first generation after the MMSeg algorithm to recognize the Chinese words with its appearing times.
According to the given value, only vocabularies within the range would be merged as the new vocabularies.
For example in the right hand side, two independent two vocabularies are merged as two new possible new vocabularies for further checking. |
| ICACT20210125 Slide.12
[Big Slide]
[YouTube] |
Chrome Click!! |
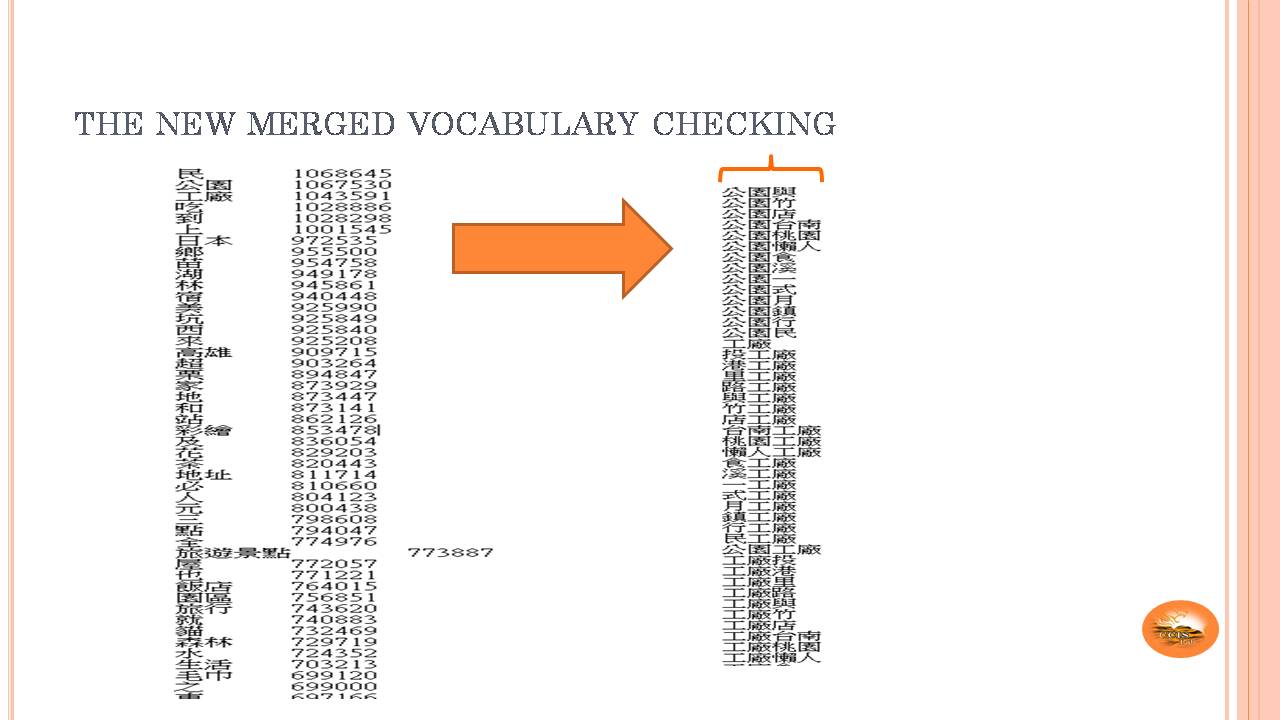 |
After merging, the new vocabularies are extended from two independent original vocabularies.
The new vocabularies will be further searched and checked. |
| ICACT20210125 Slide.13
[Big Slide]
[YouTube] |
Chrome Click!! |
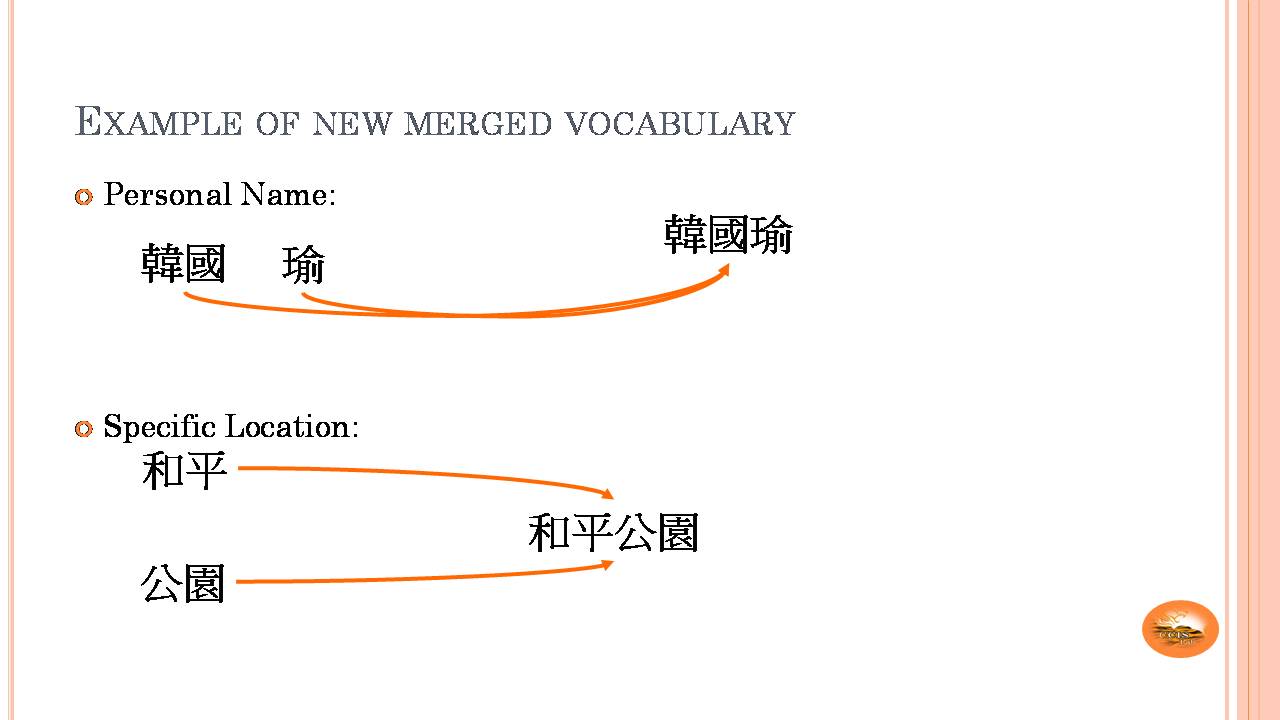 |
Some vocabularies are special, such as personal names or location names.
A name could be combined from two independent vocabularies, both can be meaningful or one of them are meaningless when exists independently.
After checking, the new vocabularies would be useful and meaningful. |
| ICACT20210125 Slide.14
[Big Slide]
[YouTube] |
Chrome Click!! |
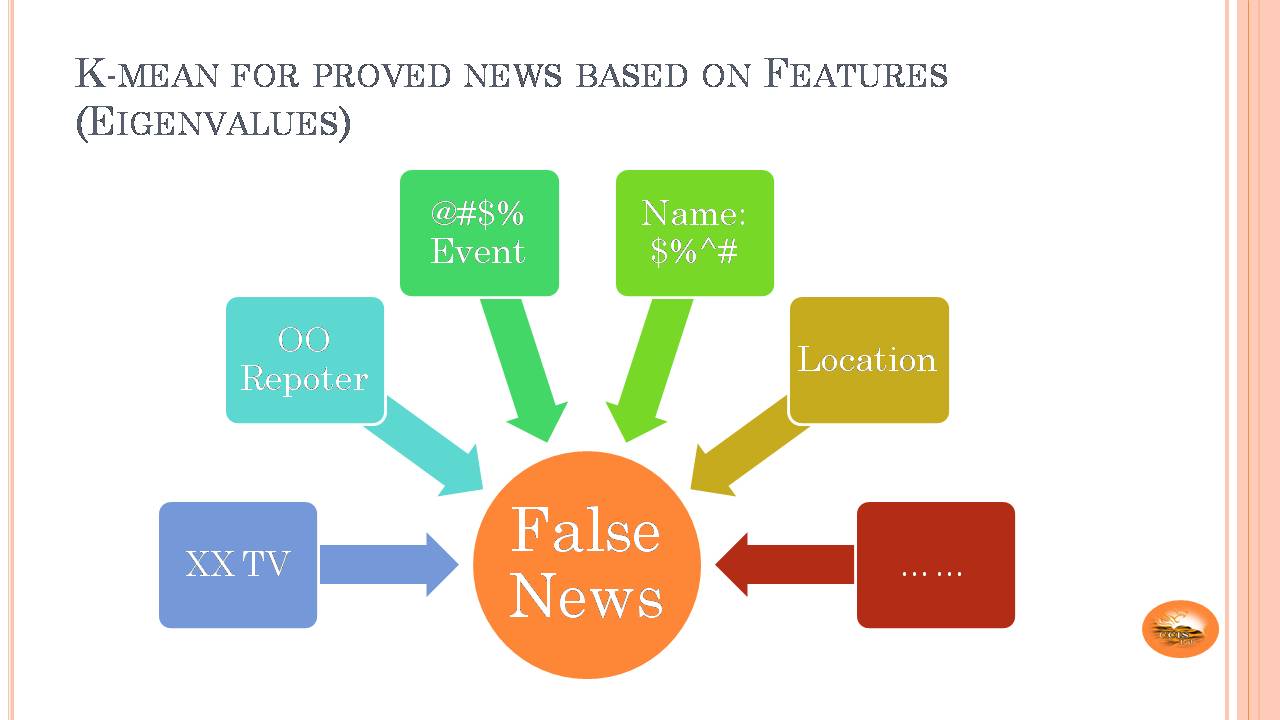 |
After finding various features or key vocabularies, based on K-mean method, the same even of the similar false news could be grouped.
After training different type of false news, several false news groups could be found. |
| ICACT20210125 Slide.15
[Big Slide]
[YouTube] |
Chrome Click!! |
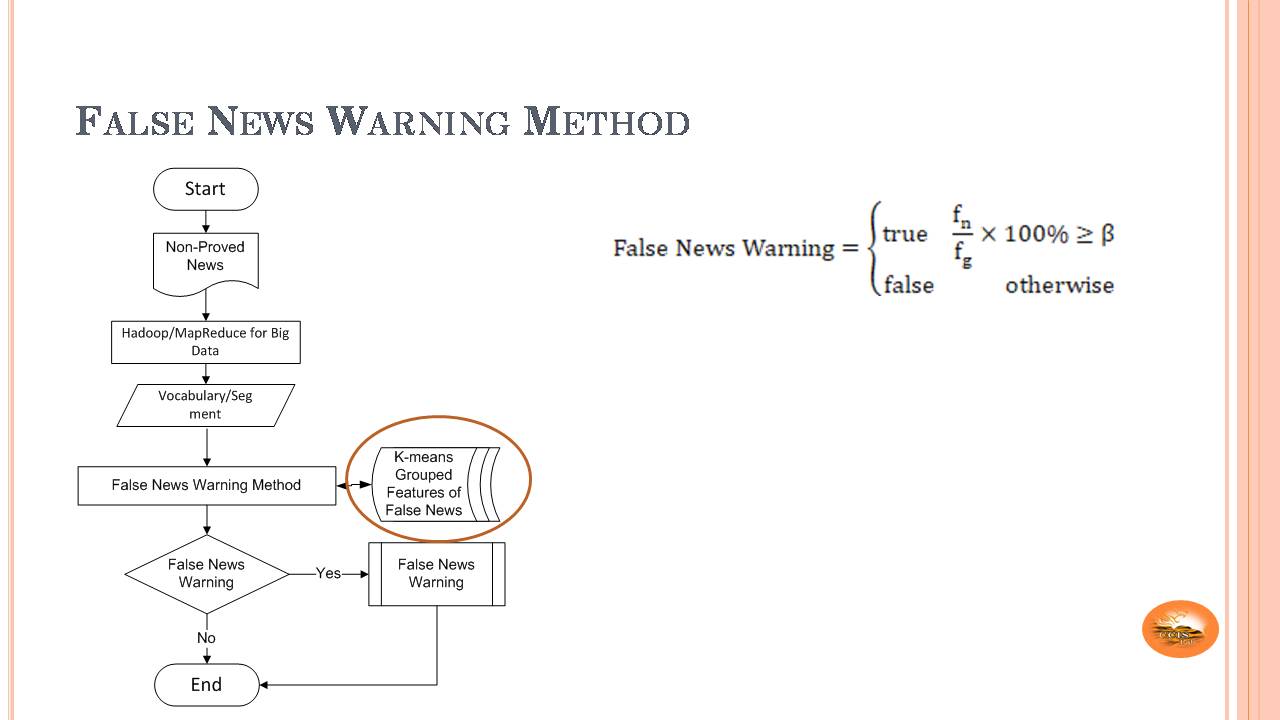 |
According to the trained system based on the previous false news,
the percentage of the un-proved news could be recognized according to the k-mean grouping result. |
| ICACT20210125 Slide.16
[Big Slide]
[YouTube] |
Chrome Click!! |
 |
Vocabularies of different languages can be managed.
Feature of web content or false new could be automatically found
Big data of false new could be grouped and managed
|
| ICACT20210125 Slide.17
[Big Slide]
|
Chrome Click!! |
 |
Thank you for your attention. |















