 ICACT20220147 Slide.01
[Big Slide] |
Chrome  Click!! |
 |
Hello everyone, I am Fang guangjin, the topic I am going to talk about is centralized dynamic spectrum access algorithm based on deep reinforcement learning. |
| ICACT20220147 Slide.02
[Big Slide]
|
Chrome Click!! |
 |
First, centralized means that the behavior of our sub-users is unified and scheduled by a central unit, which controls them for sensing and access. Secondly, we utilize deep reinforcement learning algorithms to adjudicate access actions by the raw data captured by the current central unit, and choose different access policies according to different states.
This report consists of the following four parts, which are introduction, model, simulation results and conclusion.
|
| ICACT20220147 Slide.03
[Big Slide]
|
Chrome Click!! |
 |
Part one |
| ICACT20220147 Slide.04
[Big Slide]
|
Chrome Click!! |
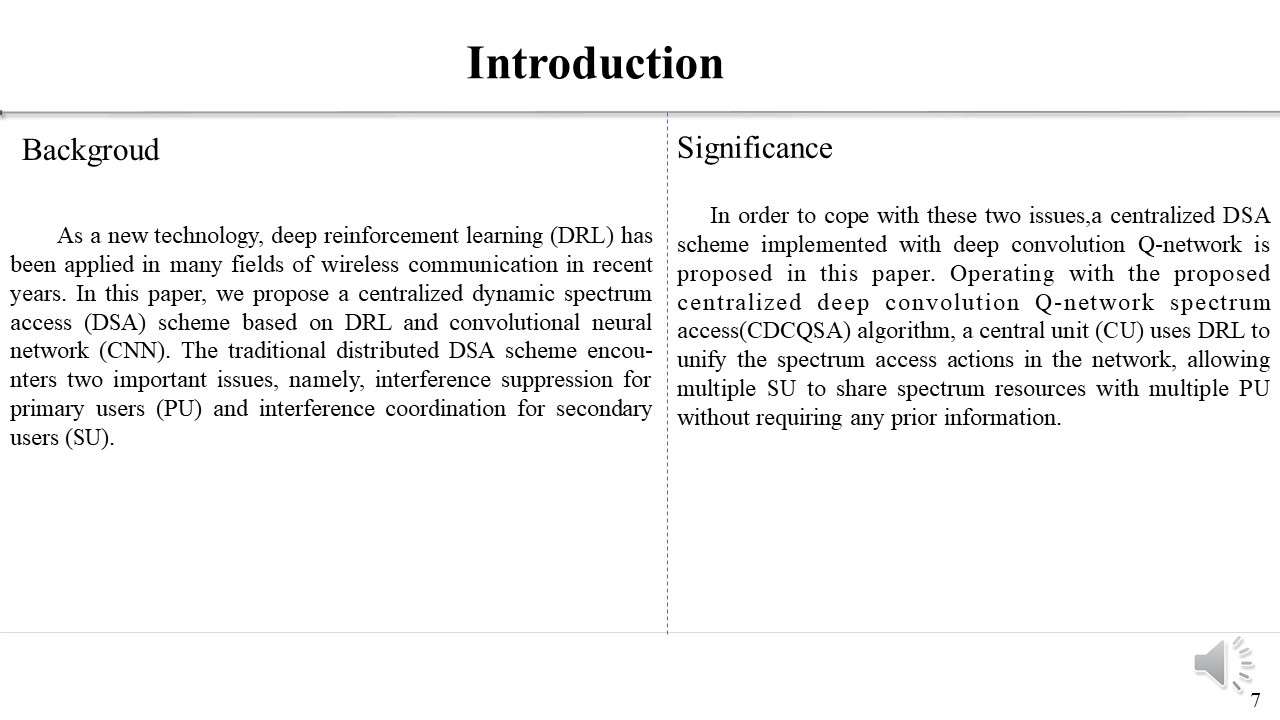 |
First, to introduce the background of our research, as the number of mobile communication devices increases, the demand for spectrum resources grows, and the way to meet that demand is, first, to expand more spectrum resources and, second, to improve the utilization of existing spectrum resources. Method 1 is too costly, so we first focus on Method 2. Cognitive radio technology is to improve spectrum utilization by adjusting the device's own parameters so that secondary users access it while sensing the absence of the primary user. |
| ICACT20220147 Slide.05
[Big Slide]
|
Chrome Click!! |
 |
Part two |
| ICACT20220147 Slide.06
[Big Slide]
|
Chrome Click!! |
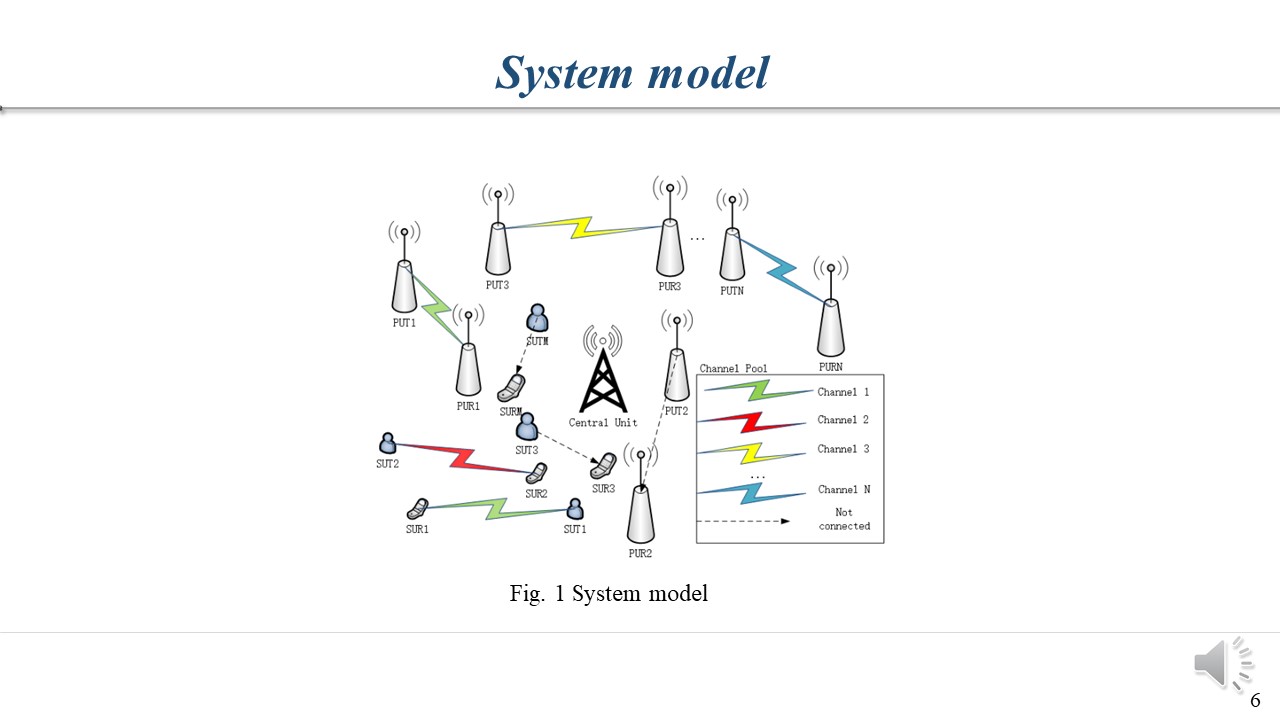 |
Using deep reinforcement learning techniques that enable devices to make their own judgments based on channel information. Also considering the cost and the interference between SUs, we use the central unit for uniform learning and scheduling.
Our system model is shown in Fig. In a multi-PU DSA network, a central unit performs state identification based on the state information of the channel, and then schedules other SUs uniformly for access actions.
|
| ICACT20220147 Slide.07
[Big Slide]
|
Chrome Click!! |
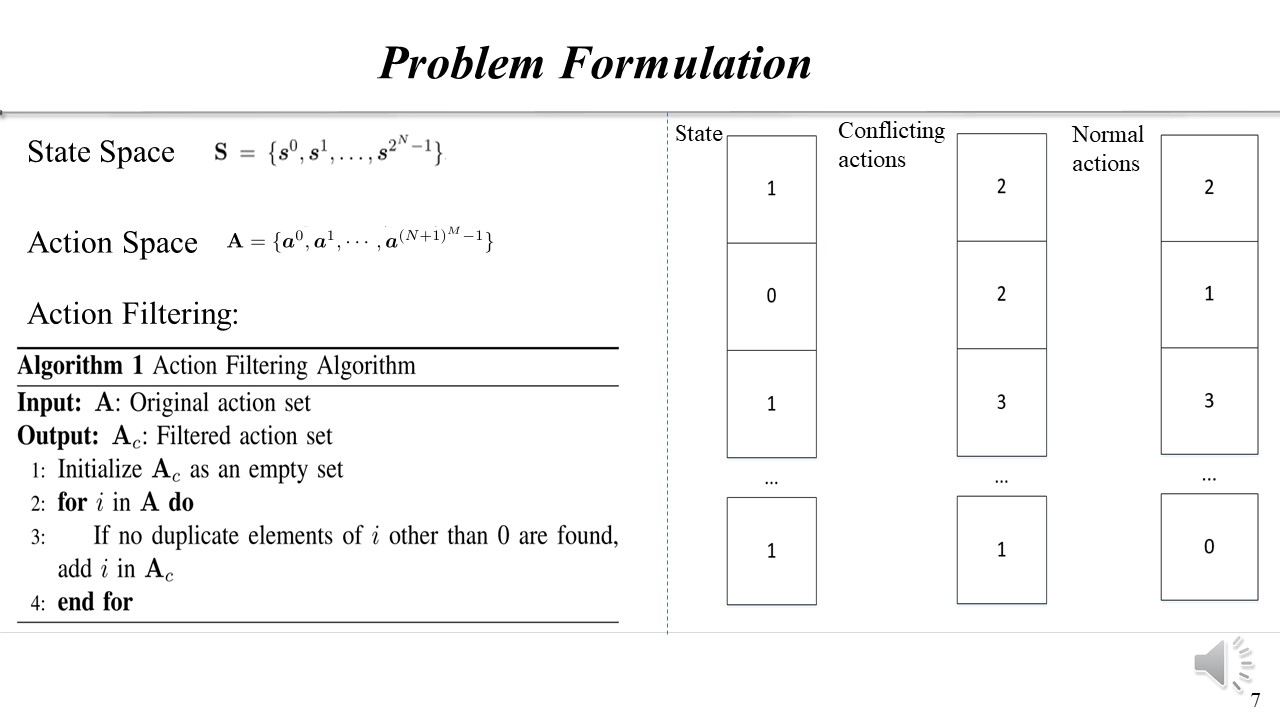 |
Our state is whether or not N primary users make a transfer, so the size of the state space is Nth power of 2. The action space was supposed to be the action selection of M SUs to access or not to access N channels, but due to the existence of SUs conflicting with each other in it, the following algorithm is used for action selection. Our state, the conflict action, and the normal action are shown on the right. |
| ICACT20220147 Slide.08
[Big Slide]
|
Chrome Click!! |
 |
Method |
| ICACT20220147 Slide.09
[Big Slide]
|
Chrome Click!! |
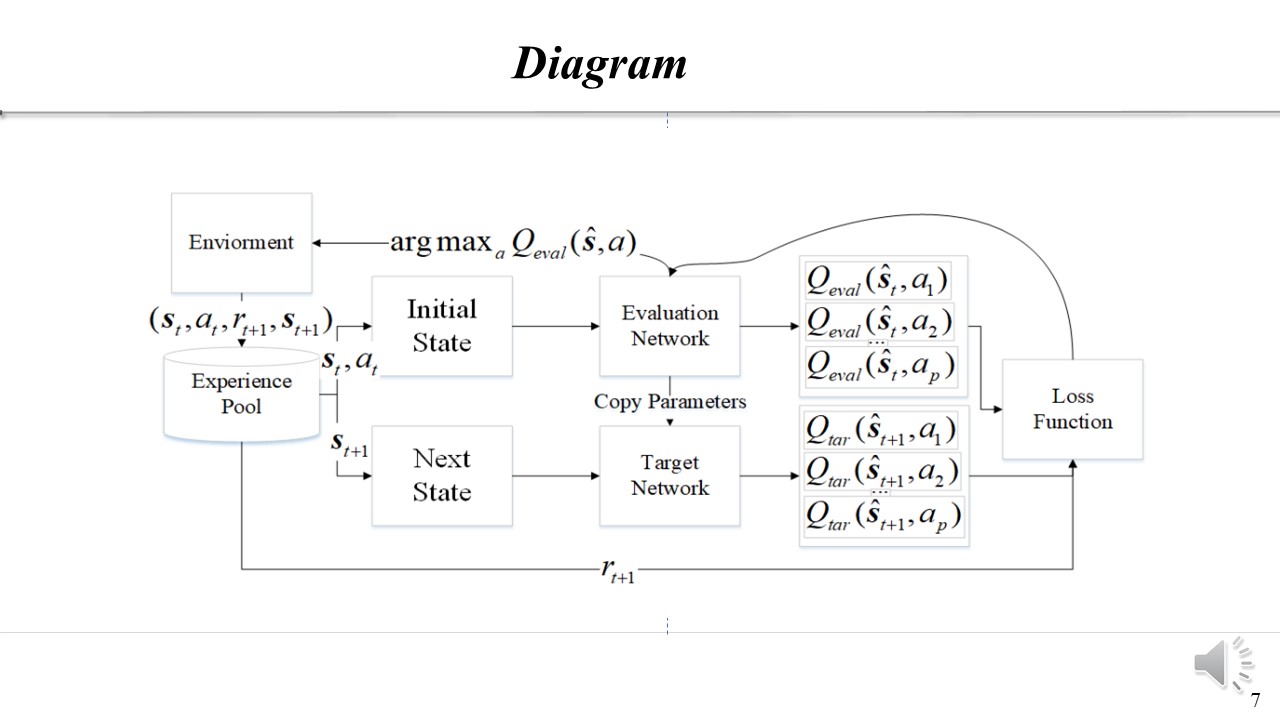 |
DQN diagram |
| ICACT20220147 Slide.10
[Big Slide]
|
Chrome Click!! |
 |
Part three |
| ICACT20220147 Slide.11
[Big Slide]
|
Chrome Click!! |
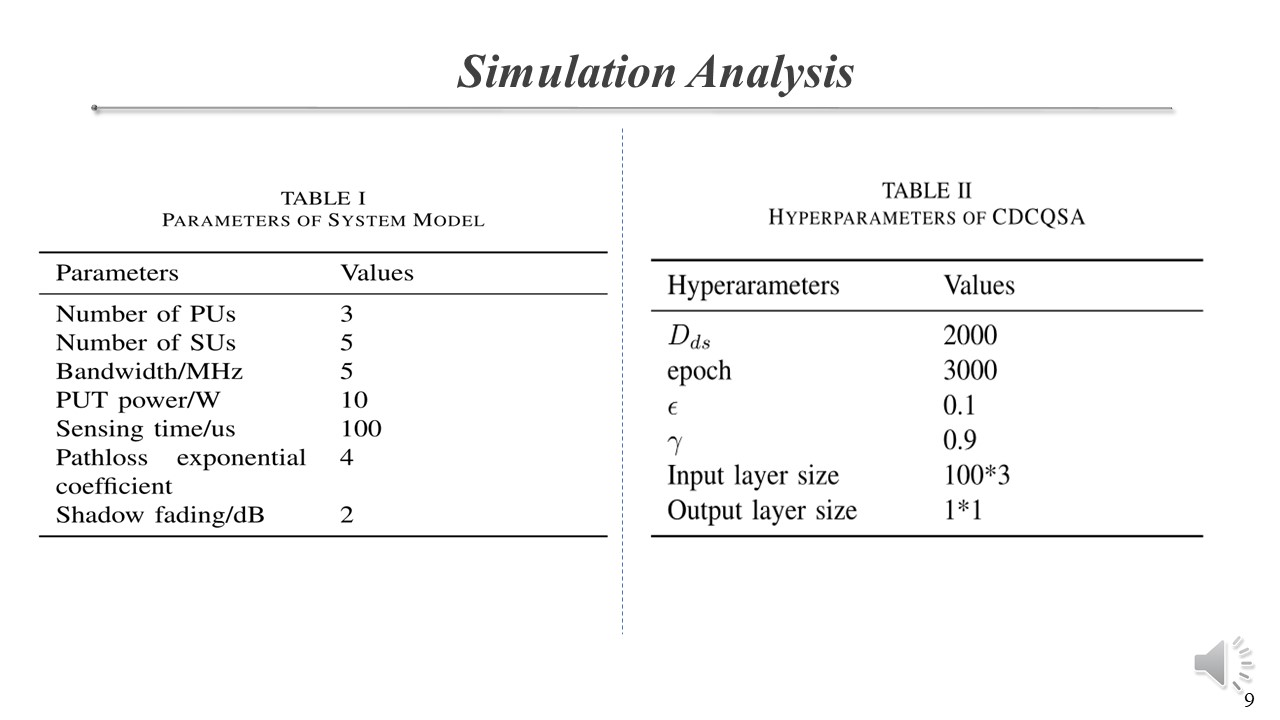 |
Simulation parameters |
| ICACT20220147 Slide.12
[Big Slide]
|
Chrome Click!! |
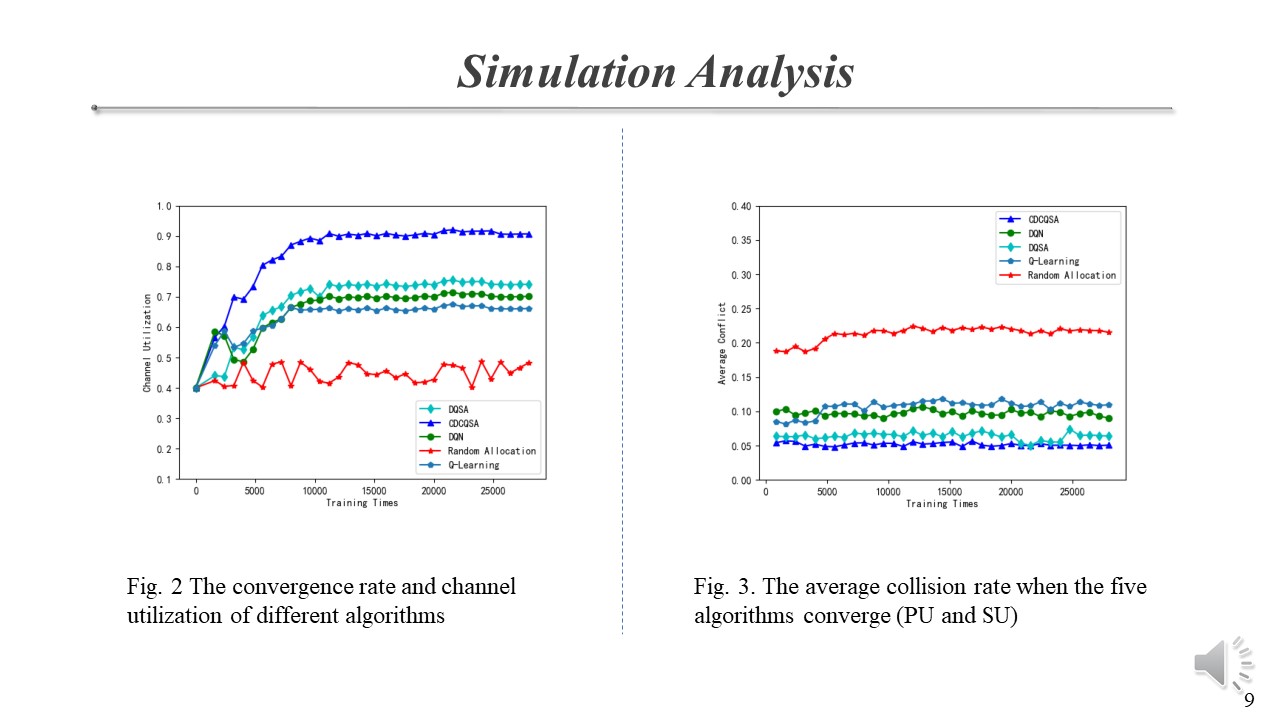 |
Simulation analysis |
| ICACT20220147 Slide.13
[Big Slide]
|
Chrome Click!! |
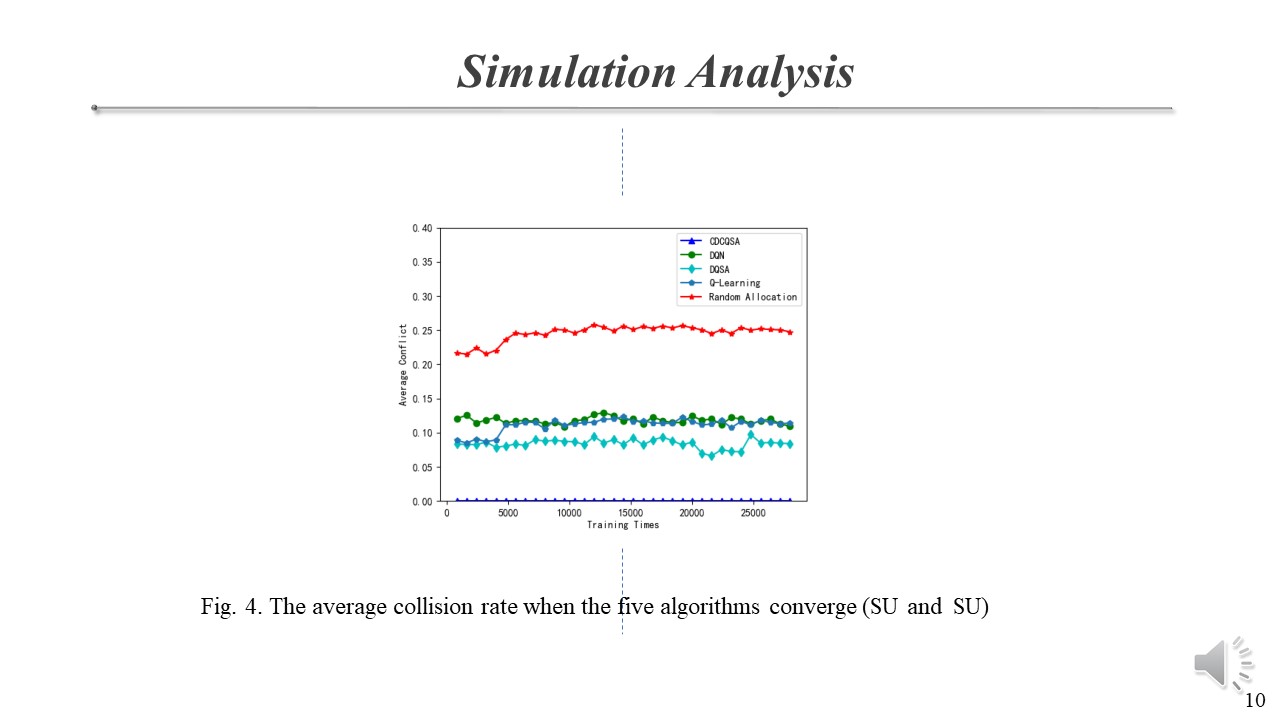 |
Simulation analysis |
| ICACT20220147 Slide.14
[Big Slide]
|
Chrome Click!! |
 |
Part four |
| ICACT20220147 Slide.15
[Big Slide]
|
Chrome Click!! |
 |
Conclusion |
| ICACT20220147 Slide.16
[Big Slide]
|
Chrome Click!! |
 |
Thanks |















